Show HN: A working Nintendo in ~1GB of Qwen weights
github.comA couple thoughts on the process here…
First off, Opus 5.5 built working weights and code with only two prompts:
1. Read this article and any relevant source code: https://divagr.com/blog/qwenputer. Then explore if you could emulate the chip and ram in a Nintendo Entertainment System (as people do today with FPGAs in MISTRs) using this technique. If so, what size model would you have to build and if you could use smaller faster ones, could you get it to be at the standard clockspeed.
It returned charts well illustrating any model would be _slow_. But it's still fun, so the second prompt was:
2. I think we should build it! Just for fun. It's okay if it's not fast. We want to be able to have the weights, and a cli to run them that we can point at a ROM.
Now while this was an _epic_ run by Opus (5.5 is a crazy capable model), this is a surprisingly well-structured challenge.
There is a long-lived and incredible community of classic gaming emulation work online for it to reference. And that community has created…conformance tests! Opus found them and built against one, that has >3k golden instructions: https://github.com/christopherpow/nes-test-roms/blob/master/...
Also, there is the original Qwenputer repo that Opus used to drive the weight writing. That was essential.
But this is a great example of what these models can do with proper reference materials, great specs, conformance tests, and clear direction.
> There is a long-lived and incredible community of classic gaming emulation work online for it to reference. And that community has created…conformance tests! Opus found them and built against one, that has >3k golden instructions
I'm doing something similar but not for an emulator, using tests other projects in a similar space use to validate things.
I also know a friend that feeds Claude Gherkin formatted test criteria, and apparently that yields insanely good Claude output.
Any good recommended reading?Claude GherkinThey are talking about Cucumber, a behavior driven development platform. Gherkin is a syntax for writing test cases:
https://cucumber.io/docs/gherkin/
Very neat, seems quite appropriate for the way people currently work with LLMs.
I'd just ask Claude about writing test specs in Gherkin. I'm going to try this Monday.
I said last year to people that I swear BDD is going to make a comeback. Hasn’t yet, but I still reckon it might!
Truly amazing. Quite thought provoking how it was helped by having high quality oracles. Eg. Qwenputer & good NES reference materials.
I guess humans need their oracles too: teachers, encyclopaedias, degrees, phds.
Bravo, awesome project, really creative!
This opens up so many interesting opportunities. In principle one could compile a small VM inside the LLM weights. The VM can host for example a Python interpreter, a shell and tools like sed, cat, grep etc. Instead of LLMs having to do slow autoregressive token emission with the current "external" tool calling, it could literally execute everything except web search, inside the LLM, with just matmul operations. You could probably optimise this so it runs in batches. You could have a gdb like application that can step through the LLM forward pass. Anyway, just a crazy thought. Have a great weekend everyone!
You might like this: https://research.google/pubs/latent-reasoning-with-supervise...
I wonder if you could train an LLM while holding the weights implementing fixed-function regions constant, so the training would produce a model that natively knows how to use these tools inside it's own reasoning steps.
I suppose it doesn't need to necessarily be in the weights, a hybrid LLM + internal fixed function blocks that aren't encoded in the weights could be quite interesting.
Combine this with latent reasoning and it gets pretty wild.
A very useful fixed function region in my mind is a symbolic execution engine, capable of only following a well-defined grammar. Perhaps a lisp would be good too?
Totally. It's like how we put brainfuck interpreters everywhere.
You can just do that anyways.
I love these hacks, even though from an efficiency point of view it is horrifying to my assembly-code-golfing-brain. And it also gives some new appreciation for how much more efficient deterministic programs are compared to AI.
The day is coming when we have widespread local inference on super powerful and efficient hardware and people will ask it what time the store closes, get distracted, and then ask it again instead of scrolling up.
That probably has already happened.
I’m ashamed to admit I do this on my work account sometimes… Not for looking up a basic fact of course.
I wish they would let me use claude desktop, I really hate looking at the terminal and don’t know how to customize it to make it more readable
> I really hate looking at the terminal and don’t know how to customize it to make it more readable
On a comment where you discuss a powerful tool for looking up information, you claim ignorance about a piece of information that same tool could explain to you! What the heck!
Not only that, but the ai could just spit out a premade .conf file for the terminal. Insanity. Or use herdr and a good looking harness for Claude cli….
There’s another way?
am i the only one confused by this ?
I believe GP is making the point that tokens are expensive atm so we are better at conserving them (the scroll back part), but soon it'll be so inexpensive or even free that we won't bother.
tokens are not that expensive...
Entirely depends on who is paying.
Once our compute base shifts from silicon to human brains grown in vats, you'll be thankful you can run all your old deterministic compute tasks on flesh neurons!
Two years ago: nice toy.
18 months ago: it can do some things but it’s generally not useful.
12 months ago: wow; this can write ok code that a human has to do a lot of review to make sure it’s ok.
6 months ago: holy fuck I’m shipping great stuff with only the occasional redo.
3 months ago: Jesus Christ this is actually pretty fucking great. I have to work entirely differently; becoming a manager of my single agent launching sub agents.
1 month ago: my god I am shipping more, faster, and more useful than ever.
Today: we have fleets of highly effectively domain expert agents working entirely autonomously and shifting between fleets depending on domain, available usage remaining, and we’re shipping 10x with 100% better reviews than before—expanding by the day and self-improving its own harness.
—-
Next week: the agents will prioritize code golf.
The week after that: everything is written in ASM.
We’ll come full circle in 3y
e: fyi; this is my personal progression with LLMs.
Next week: hey, I'm out of a job, what happened?
This is what I don't get with the kind of posts you are replying to.
I have experienced directly what the evolution of cloud based software, and now AI based tooling, has done to team sizes on delivery projects.
Cannot understand how they don't get how all the performance improvements directly correlates to smaller team sizes, in shareholders driven economy.
So far I have been lucky, and just hope to have enough savings when time comes, as finding jobs after 50s wasn't already easy without having to add AI on top.
Most of the world does NOT optimise for efficiency, particularly at the big end. Really big hyperscale companies (and some startups) are unusual because they at least sort of try, most of the world is not even trying.
The org structure is optimised to reduce or even minimise individual agency, explicitly at the cost of efficiency.
Teams have fiefdoms, private repos that the rest of the org can't see. You are not granted permission to see what permissions you have. Byzantine department structures. Shipping "hello world" to production takes 3-6 months and nobody can imagine it working any other way.
There's actually no central directory of teams or processes. To get anything meaningful done, you need the co-operation of maybe 8 teams but there's no consistent way to engage them all. You have to negotiate with them all in different ways, they're like little warlords, sitting and guarding access to some vital resource you need. They have established a ticket-based interface with a 7 day SLA on top of a perfectly good vending API that could do what you need in seconds. Sometimes a blocking team has a 3 month backlog so your project will just have to wait.
Everything is always in the process of being restructured, so no end to end 6 month process happens the same way every time.
These organisations could use AI to run the end to end process in minutes. Heck, they could just put APIs on top of what they already have. But the way they WANT to use it is to keep doing what they're doing but with EVEN MORE form filling and paperwork.
You would think they would get outcompeted, but no. The "IT organisation" sits like a brain slug on top of an enterprise with substantial regulatory, capital and execution moats.
Big cuts of course do happen in these places, but it's often for optics (we need to signal that we care about efficiency, and AI is a great excuse). But you can't protect yourself by being efficient and good at your job, because the cuts were not about output.
Because I don't live in a world where my team needs to grow for me to feel more successful? My teams have been small and tight-knit at every place I've been an Eng leader. I left a job with 13 engineers and they're at >90 now, apparently doing less; but, that's just what I hear second-hand.
I want to do MORE with the same amount of folks.
Was it a conscious or unconscious decision to reply to a chain with an argument of "headcount is obviously reducing" with "I don't need headcount to grow to be happy" without addressing the gap between those two at all?
I think you may be conflating two different arguments.
I'm not disputing productivity improvements can lead to smaller teams, particularly in a shareholder-driven org; that's a separate conversation, IMO. The fact I work at an employee-owned organization, currently, I suppose I'm simultaneously a worker and an influential shareholder.
I was trying to say, running counter to what is frequently mentioned on HN about FAANG Eng Leaders, that I don't equate engineering success with growing headcount. I've always preferred building small, highly effective teams that can accomplish more without needing to grow, just for the sake of growing headcount. My want to do more with the same number of people isn't an argument that headcount won't shrink. It's an argument that growing headcount was never my measure of success in the first place.
No that you asked, but, my measures of success are: are my engineers happy (being that many of them have worked with me at least one company before, and one at 4, I feel they are); are we playing with the latest technologies; and are we learning new things every day?
> I want to do MORE with the same amount of folks.
So do I, but I've been in two companies that had to let me go because the investors said they didn't want my role to exist any more. Plus two other roles where the company straight up ran out of money.
It's not always up to us.
I unfortunately have been in enough situations where team sizes get to shrink, unless there is some escalation going on.
First it was offshoring, then managed cloud environments and servless, followed by ready made SaaS products, low code/no code iPaaS cloud products, and now agentic runtimes.
The ones doing content translations, asset management were the first, followed by classical infrastructure people, then most backend roles, and so it goes.
Not everyone makes the transition. In the rise of AWS, someone I know's last task at this one company, a company they'd poured their heart and soul into; it was to move everything off the on-prem servers that he'd procured and the company had been running in for years. He moved it all onto AWS, got rid of that hardware, and then he was out of a job.
HR meeting in room #3, please bring your coat with you.
> Cannot understand how they don't get how all the performance improvements directly correlates to smaller team sizes, in shareholders driven economy.
Plenty of us understand it.
Are you calling for a sabotage? A boycott? What?
Be more clear regarding what you “don’t get”.
A bit more of skepticism and less celebration of our gloomy future, I guess.
> directly correlates to smaller team sizes, in shareholders driven economy.
Good! Costs going down is great
I think it is because programmers are not that good at economy or running a business. Their bosses are though and they don't see a productivity tool, but a way to reduce their costs.
I have experienced directly what the evolution of cloud based software, and now AI based tooling, has done to team sizes on delivery projects.
Why would we care about team size?
Doesn't the world have many more software engineers today than at the start of the evolution of cloud based software?
"First they came for...."
One day it is you that gets given the cubicle box and door walk out.
Not at all, given the layoff rounds for various reasons, which fail to find new jobs, because now corporations are doing more with less.
Why not say what you’re trying to say?
Quit being passive - you’re asking folks to consider this, and deeply ponder the consequences, but what’s the action you’re calling for?
General AI ban? Managers guiding their firms not to use, to (artificially?) protect headcount? Individual contributors quietly quitting the demand to push more code than can be reviewed properly?
Say what you need to say - the way you’re going about it is worse than weird: it’s ineffective, and makes your view (whatever it actually is) look whiny.
Each one should know what is their role, protecting their jobs from late stage capitalism, instead of celebrating it.
What about their comment says they don’t understand that?
The whole positive content on the productivity outcomes.
I can’t decipher your reply.
Apparently folks on other discussion threads, got it.
There are no other replies in this part of the thread.
You don’t care if you’re understood?
Edit: My best interpretation is that you think the commenter believes the gains they’re saying are good, that they’re rooting for them, or some sort of other anti-human bend,
and normal readers just aren’t seeing that.
Other people seem to have absolutely no problem interpreting these, and I don't think it is fair to take your own lack of ability and to extrapolate from there 'normal readers'. You seem to be the exception here.
Yes, it’s very obviously my lack of ability that causes your, and the other vague commenter’s, unhelpful and snarky comments!
How could I have been so foolish.
Again: nobody else is replying in this specific sub thread.
I think that's this week
Speaking of code golf, I had it optimize Diskitude into a <8 kb (still uncompressed) executable, add some features, and improve scanning performance all while increasing size. An LLM will gladly make extremely optimized software, you just have to ask for it.
> The week after that: everything is written in ASM.
Also “1 month ago,” but s/ASM/Rust
> The week after that: everything is written in ASM.
This is an genuinely good minimalist good editor that is created in mostly assembly that was created with the help of AI[0]
I maintain a fork of it which basically adds scratchpad ability to it and is something that I use daily myself for what it's worth[1]
My fork was created with the help of GLM 5.3 (an open-weights model)
The future is already here in some sense. I could in theory add more features but I intentionally add not more features because asm is still slightly difficult for it to write but in some sense the tradeoff has been/could be worth it. It was more of an experiment really and I am really impressed by it.
in many ways, forcing AI to write asm does make you now think intentionally of features and ironically prevents feature creep and makes you think of stability of the product (atleast right now for me anyways)
[0]: https://rhun.app
i wish this was my experience, it's basically the opposite. im shipping a little faster -- but spending endless amounts of time reviewing LLM-generated code that usually isnt production ready.
>Overall, nesformer runs 150–290× slower than the real console.
I like these kinds of projects because it helps to show the massive compute requirement between LLMs and ordinary programs.
A while back I saw some people saying we would just have LMMs hallucinate an entire operating system every single frame. I guess technically it's now proven to be technically possible, but it would be thousands of times slower while requiring thousands of times more compute (a multi-million x difference from an ordinary OS!).
This is a bit different though. It’s using transformer architecture to emulate almost at the circuit level. It’s probably even more inefficient than something that was trained to emulate a cpu, but with the advantage of actually being an exact emulation rather than learned approximation.
It’s a bit like when a human brain remembers facts, if you sat down and computed the hash values of the thing you were trying to remember, and traced out a DB lookup in your mind, it’d be a lot slower than just “oh yeah I remember that”.
We're in a really interesting world where "anything can run anything." Like, in theory, you could get Doom to run on a Cerebras that's specifically laid out for $specific_model architecture, by swapping the weights it holds in SRAM. Just like we're currently running $specific_model on GPUs that were designed for games in the first place.
To misquote a certain YouTuber: LLMs are just games, unlimited games, but no games.
How accurate is that run of doom i wonder is it lossy in any sense
> A while back I saw some people saying we would just have LMMs hallucinate an entire operating system every single frame. I guess technically it's now proven to be technically possible, but it would be thousands of times slower while requiring thousands of times more compute (a multi-million x difference from an ordinary OS!).
Gosh. That would be a very silly use of an LLM.
Bad use of any AI, even image/video models which are certainly less wrong than this. Stuff like DLSS show we're getting stuff that could generate a game's graphics frame-by-frame, but even though it's possible to have an entire game environment (not just graphics, everything) done by an AI, such things demo better than they play due to temporal coherency.
That said, having an AI make the code for each thing as you need it, might work somewhat OK eventually. Wouldn't trust it today (security, data integrity, and a tendency to cheat on tests), but eventually it could happen.
> Stuff like DLSS show we're getting stuff that could generate a game's graphics frame-by-frame
A key point of DLSS (5) is that it is significantly guided by ground truth rasterization or raytracing info. It's not intended to replace graphics pipelines, it augments them to produce more detailed surfaces and interpolate frames more efficiently than calculating all of it traditionally is. But you have to calculate some of it to get these results, it can't be a purely AI solution without looking incoherent.
VibeOS? It's been done! It's hilarious: https://youtu.be/7NfyZhV1dKM?is=Y8LwTbY_stLPilqR
The description of vibeOS in that video is half way between what I thought I was replying to and what I suggested.
Doing it in a way that isn't described as "hilarious" is probably also possible in the time since that video came out. Doing it in a way which isn't described as "a security nightmare" or "liable to lose all your data", probably not yet. Not as vibe-coding, at least.
I mean for sure, this isn't an OS that _stores data_. It'll pull up any data you ask for, though!
A middle ground would be an LLM taking structured inputs ("mouse clicked at X,Y") and making "draw" calls at whatever level: pixels, SVG, HTML/CSS. While the LLM's output tokens could be mapped to just these calls, it could also just do a bunch of tool calls that write to these formats as well -- it's a matter of efficiency.
We have Jev to prove LLMs that output constrained decisions are useful. Why not make LLMs just output UI natively?
At a fast enough inference speed, you could just connect the network to it.
So an LLM would then just take the network, user input, and output a UI, with tool calls to deal with memory and other resources. In theory, you don't need an OS any more.
This is exactly like if someone implemented a CPU using nothing but CSS animations. Maybe a fun way to teach about turing completeness, but pretty meaningless otherwise.
Hard disagree on it being meaningless. Just showing that this is now possible and providing the details on how it was accomplished makes it invaluable to builders.
Builders who want a terribly inefficient and slow emulator for old silicon?
They've already forced Electron on us, I'm sure they'll make LLM-approach just good enough too.
Let's say you are developing a product, choose 1:
1) Have a single person vibe together a computationally inefficient solution in 1 month that runs transformers on some backend.
2) Hire a team to work for 2 years to design, perfect, optimize, plan, revise, and architect a solution.
The risk/reward for 1) is extremely better than 2). Given the turnover for entertainment in this day and age it doesn't make sense to do all this complex stuff.
It would be much better to use LLMs to create ordinary programs than to use an LLM over and over to emulate something that's thousands or millions of times more efficient.
Thousands or millions of times less energy used is a whole lot better for the environment, too.
> Given the turnover for entertainment in this day and age it doesn't make sense to do all this complex stuff.
are we not talking about the NES?
You can't generalize and say that 1 is better than 2, it depends entirely on what you are developing, for whom and for what purpose. For a one-off dumb thing for a few people 1 is fine, for anything at scale, 2 is likely better.
How do you vibe a transformer solution without the existing real solution, which would be needed to generate the training data.
These are just machines for ripping off existing games/programs with mostly accurate simulations. You can't vibe together a transformer of something that doesn't exist with meaningful control over the results.
> show the massive compute requirement between LLMs and ordinary programs completely agree, but it is at least raising the point that 150-300x is only a bit wider than things like framework/language choice... which is quite remarkable considering how much more open-ended running everything through an LLM is.
> hallucinate an entire operating system every single frame 1. I don't know that "hallucinate" is the right word here... any more than Windows 11 itself is a hallucination, for example 2. I don't personally think that this system is a million (thousands x thousands, from your attestation) times slower, but given Moore's Law, even that isn't the worst thing ever. this is the low water mark.
> have LMMs hallucinate an entire operating system (...) technically it's now proven to be technically possible
You're comparing apples to oranges there!
To hallucinate is arbitrary, you can use a 2B image param model, it will hallucinate an OS no problem* running real time!
What this post is about is completely different, which is actually emulating the complete system in an LLM - that is hundreds (or more) times slower.
*absulutely crappy quality tho, unusable OS in practice
That's the case right now--but what might a customized model tailored only for a narrow set of OS functions behave like? I suspect its achievable with a lot less compute.
Now is that a desirable product? Would it succeed on the merits in the marketplace? Maybe it would...
As an example, is it faster to multiply 2 numbers using a single MUL instruction or multiply matrices with millions (or billions) of elements multiple times? Multiply that overhead by every single thing you do and that's the overhead of using an LLM to emulate a program.
These systems in weights are proof of concepts. Surely there is room for optimization in there somewhere.
Yes, there is.
It's called a Nintendo emulator.
That's kind of the point here.
Code isn't going anywhere. It can be literally billions or trillions of times more efficient than an AI, and as AIs scale up that number just continues to grow and can completely plausibly hit quadrillions in our lifetime. What relationships humans have with code is a completely different question, but the idea itself isn't going anywhere. Anyone who thinks otherwise has failed to grasp just what producing a single token from an AI actually entails.
It would be baking the model into hardware or FPGA, which ends up building the same thing being emulated. An emulated ALU in hardware is ... the ALU.
Isn't that the same with e.g. human brain? Computer program can compute billions of equations, whilst human will struggle with just one.
Human brain does a lot more at any given time than just whatever you're consciously thinking about.
The ones we're not thinking about is the computer program abstraction layer in our brains. I think consciously thinking about an equation in our brains is the LLM layer equivalent, we're reasoning about it with language logic or models of our spatial senses (the unconscious calculations)
Perhaps, but it doesn't indicate anything new or interesting about cognition or biology.
For example, Minecraft in Minecraft [0] is (while impressive) slow and inefficient too, but it doesn't tell us much about humans except that some of them are weirdly ambitious in their projects.
It would be a natural extension of the current work in software. Every layer of abstraction/web/scripting language adds seemingly 10x in both ram and processing time, undoing the advancement of 1000x faster processors and ram increases.
But at some point we’re hitting a wall here. If we want our software to undo 100,000x more processing powers, we need that llm software emulation layer.
I expected this to only simulate the CPU itself, but was surprised to find they actually simulate the RAM as well (contained in the model itself via the gated deltanet architecture). So in my understanding, the CPU, ROM, and RAM are all handled internally by the model, and the only inputs after initialization are the controller events, wild.
This has the nice side benefit of letting the 1gb of weights compress down to ~3mb (since it’s mostly empty)
> nesformer builds on Qwenputer by Divyansh Agrawal, which compiled a CHIP-8 and then a RISC-V CPU into Qwen3.5-4B. It reuses Qwenputer's compiler and its central trick: the model's Gated DeltaNet state is the machine's memory
This is amazing, love it! Qwenputer is very cool too
I guess I don't understand the point of this. Of course a set of digital logic circuits can be reduced to a set of weights. Am I missing something?
Apparently it's news to some people. It also helps combat the "LLMs ArE nOt DeTeRmInIsTiC" complaints.
Doesn't help much
> It also helps combat the "LLMs ArE nOt DeTeRmInIsTiC" complaints.
Reality says otherwise, especially from those who run LLMs in production at a large scale. Hacks such as baking in the weights with tiny experiments doesn't disprove anything.
The same LLM boosters also continue to repeat one of the biggest misconceptions: "sEt TeMperaTurE tO zERo tO aChiEvE fUlL dEterMinIsm."
The accurate statement is that LLMs are not inherently non-deterministic. From a mathematical perspective, they’re obviously deterministic. But choices in the way we deploy them introduce non-determinism.
Sometimes projects have no point other than to show what can be done – and the pure thrill of doing is an end in itself … but I agree with you in the "so what" sense here … I feel like with this project there is meant to be a point (other than play for the sake of play and art for the sake of art and coding for the sake of coding) but I'm not seeing it either?
Because it's fun
This work, and the original qwenputer work it builds on, are both technically uninteresting slop. HN eats it up though.
HN loves slop meetoo projects without questioning the details. With close inspection it is an overly complicated version of this paper [0] on neural turing machines.
This concept was hyped up (because DeepMind) for a while at the time and in reality it amounted to nothing. This is just the second reincarnation of a similar concept but with added extra saturated slop and hype on top.
That paper is great work. This qwenputer stuff is slop. The problem is that HN can't tell the difference.
Not a climber then?
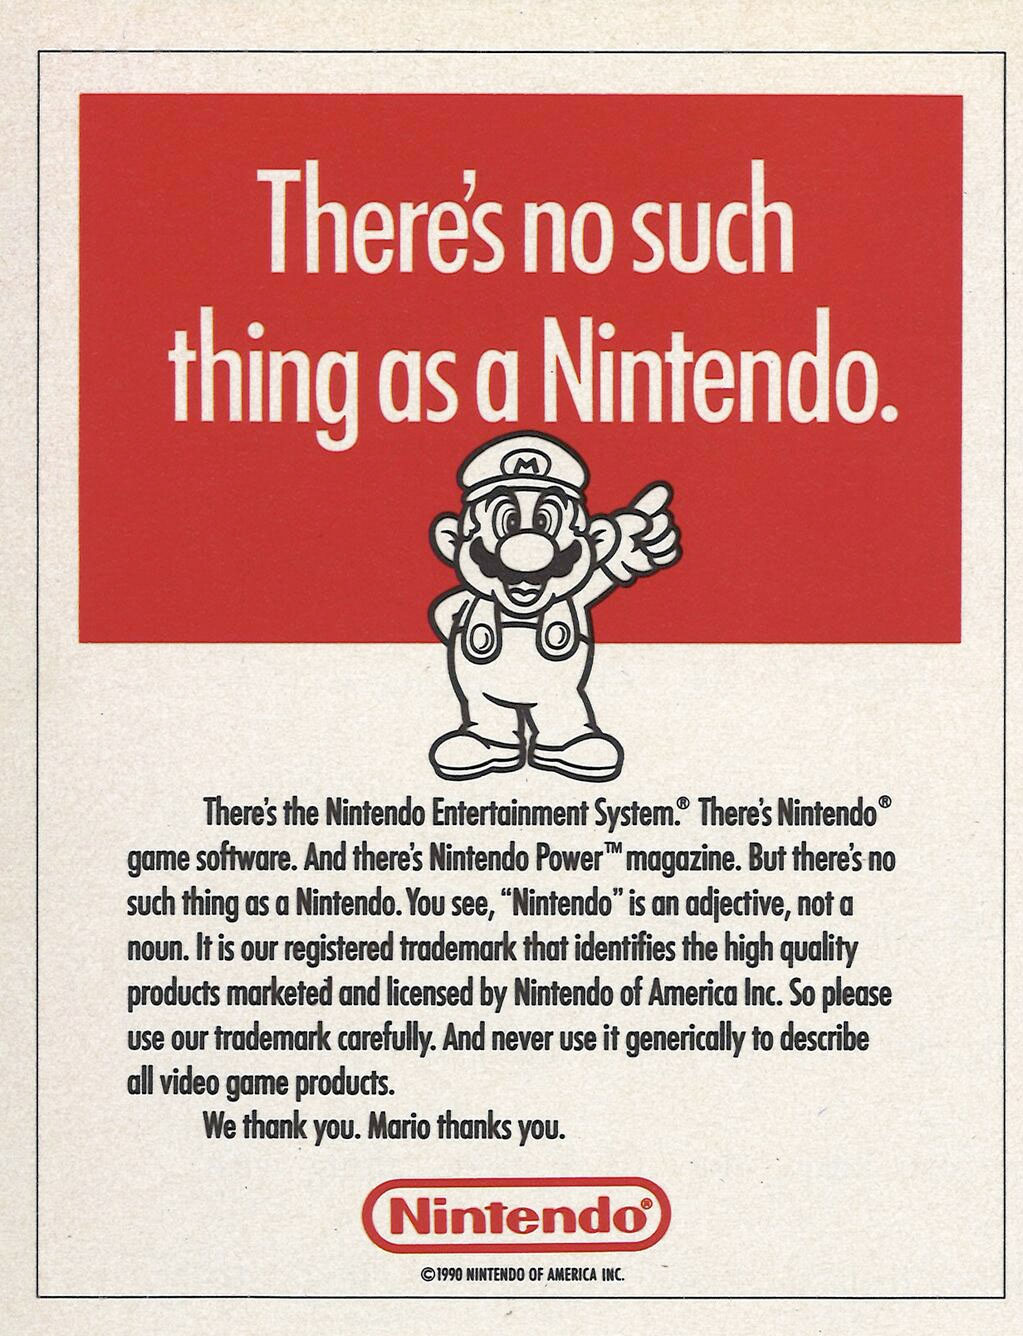
B-but "there's no such thing as a Nintendo".
https://www.reddit.com/media?url=https%3A%2F%2Fi.redd.it%2F5...

"Mario thanks you".
Sorry, I couldn't parse the obviously AI written README. If the author can't be bothered writing it, I can't be bothered reading it.
Maybe the bots will appreciate it more, after all, it seems to be written for them.
I'm guessing it's safe to say that LLMs can run Doom.
It mentions a greedy decoder in the readme, I'm curious what would happen if you run it stochastically with T>0. Vibe NES? Or does it just crash.
I imagine it would prove really difficult to keep generating valid instructions.
Woowww this is cool, not trained is even cooler--maybe I'm probably a bit naive, but to me it demonstrates an understanding of how an LLM can compute
Has anyone tried training a diffusion model for speed ?
so, are LLMs going to be come the universal computing medium?
Omg what is this sorcery?!
How do they know it's "working"?
Did they test every possible input/output combination?
Doesn't work for all cartridges (I didn't run Opus that long, but it could keep going). Works with Super Mario.
But to answer your question, it's in the readme: https://github.com/dbreunig/nesformer#how-it-was-checked
Do you test every possible input/output combination on any CPU?
No, because that would be impossible.
You perform a series of more specific tests. In this case, it's "working" in so far as that Super Mario Bros. appears to be playable, for example.
Does not mean that it behaves perfectly according to some spec, or identical to another CPU (like the NES's 6502), of course, but it's clearly a working CPU to some 6502-compatible extent.
This is a case where we basically did test it on everything! Because the emulation community maintains conformance tests with over 3k of golden instructions. (And this is why Opus was able to so effectively build it; it found the tests)
Yeah, but that still doesn’t mean there aren’t theoretical bugs. Testing every input would effectively mean testing every stimulus, which is combinatorially impossible. You might still have subtle timing bugs, bugs with very uncommon instruction sequences etc.
But my point was exactly that the (extremely vastly) smaller subset of tests that you performed is more than enough to proclaim a CPU to be “working”.
Can someone give a TL;DR ? What's the input to the model? What's the output?
Next up: 1999 peak civilization compiled into the weights of an LLM.
It's NES
Yes, calling a Nintendo Entertainment System (NES) a "Nintendo" may have made sense in 1989 or 1990, but not in 2026.
TBH I think classic Mario when I hear "Nintendo". The new stuff is a Wii or a Switch. Granted I was born in 1984.
Same, same and same.
They were really upset about it even back then: https://gcdnb.pbrd.co/images/9zn32PxVXM5w.jpg
To be fair to them, in 1990 it was common enough to hear someone call any/every electronic game a "Nintendo".
There was a real risk of their trademark getting Kleenex'd, at least in the US.
The title is very "grandma who doesn't know the tech" coded. Every game system is the Nintendo, controllers are remotes, etc.
oh boy, how amazing.. stolen code can be regurgitated by the black box of bullshit... such amazing, so wow.
This is like when people used to make tetris using only CSS or whatever in the 2010s. But it's less impressive because Claude Code can slop it out in an afternoon.