Redesigning source control at Anthropic
anthropic.comExcuse me for throwing up this stupid idea, but if code changes per unit of time keep growing at this rate and are not slowing down with infinite merging demand, it seems that this repo will be in a constant state of continuous change and we constantly roll forward with automated code and obviously no direct human supervision, then why even have source control? Why not just let software be fluid and, like Heraclitus river, never step twice in the same repo.
Agents use source control, too. It's a pretty important part of the development process to understand how code has changed.
For example, you can imagine, at the extreme, that agents could get caught in code change loops: a code change seems appropriate, it is implemented, it turns out there's some external factor which makes it not appropriate, the change is reverted, then that same code change seems appropriate again, etc.
Obviously you can prevent that from occurring with some extra infrastructure in-place, but at that point you're basically creating source control.
In theory, an agent could use git-bisect to identify when a bug was introduced. But the operator would have to be more interested in understanding the root cause than in fixing the current form of the bug...
For me, Claude regularly looks at git blame after identifying a bug, then reads the commit message and other changes in the commit to understand the context of why that behavior was introduced like that. I wouldn't be surprised if it pulled out a git bisect
Then again, my standard instruction is something like "{bug description}. Find the root cause and propose possible solutions" so I guess I fit your profile
Same, I basically take the derivative of a bug wrt every major dimension before I fix it.
not really an option when you're working on a large codebase where a bisect means that a lot of steps could be multiple-hours of compiles. E.g if on a simple 12-step bisect you get 6/8 with a full rebuild you've already spent an entire work day on this
> the operator would have to be more interested in understanding the root cause than in fixing the current form of the bug...
Can you even do the latter without the former?
I see it all the time, it is fixing the symptoms usually. It kind of works until it doesn’t and it fails miserably.
So yes you can and it works, sometimes…
You can "fix" it (make the current reproducer not reproduce it anymore).
I’m not advocating for no source control, but you can avoid loops like this with Architectural Decision Records. If you’re real lazy, let the agent maintain the ADRs and they will usually call out when these “painted into a corner” scenarios happen and you can then reason them around it.
> Hmm, I have destroyed the file again, that's odd. Let me rebuild it from a half recollection of what it was supposed to do based on my compacted context.
It's the right approach if your business is selling tokens and the customer doesn't know any better.
Right. But how to prevent adversarial agents working on the same code base from treating the ADR list as a form of malicious message exchange?
Don’t let adversarial agents work on your code?? What is protecting an ADR against adversarial agents going to solve if they can just embed a highly advanced, obfuscated ‘rm -rf windows32’ anyway
> Agents use source control, too.
This is true, but at 30,000 merges a day we're talking about nearly 1 million merges a month, and purely autonomous agentic merges tend to be noisy. Is this still a tractable problem, even for an agent? Do revisions older than a few days, other than perhaps release snapshots, have any relevance for such a process?
That won't last. I see that as a disaster waiting to happen. There is absolutely no way they have control over what gets produced at that rate.
> There is absolutely no way they have control over what gets produced at that rate.
I'd wage that volume of changes is not leading to forward progress, but is a clear sign of code churn.
This in turn is a clear tell they are dealing with spaghetti code.
Not all merges are equal, even if it's a monorepo, it's probably rare that you'd have to look at the whole codebase to implement a new feature or find the root cause of a bug. Once you start looking at the history of a specific folder, it becomes more tractable.
Of course that does require some folder structure, and agents are not necessarily great at that, but they're still decent enough that you do end up with many folders not being impacted hour or even daily.
I am not sure that I can agree with this at this scale, especially for the hotspots in the code. But I admit that I am speculating here.
Anthropic can just replace pesky source control with a much better source guardrails. Aren't they all the rage and next step evolution in the computer security? Just ask Claud "pretty please do version control" and that should be enough, right?:)
You absolutely know there is one of those AI bros out there in social media posting on how they feel euphoric because their agents don't speak git anymore and just pass a zip with the source code around to other agents as handoffs.
> Agents use source control, too. It's a pretty important part of the development process to understand how code has changed.
This is a great idea, now they just have to use/do it. Maybe they can use it effectively by cloning the repo and having all the history at hand, rather than continuously scraping web pages with git content formatted for human brwosing.
In this sentence who would be understanding the code changes, humans?
The agents obviously.. I thought that was obvious.
That's not super reassuring, until I know they can read, remember, and reference reliably at suitable complexity.
And which is understanding the code changes meant for?
Just have the agent rederive the revert, based on the facts of whatever made the change inappropriate.
Many parts of the Git distributed version control are the results of good decision made. Anthropic source control team just think that their trade-offs needs are vastly different from other businesses. They said these too:
1. they have no-cap token spend allowance internally
2. their agent swarms are amongst the largest if not the largest, again because #1 above.
3. their git repo is enormously large (100GB uncompressed git history on main, 25GB compressed).
4. their merges per day count grew an order of magnitude from May to September to 30000 times per day, they are not seeing it slowing down anytime and probably only going to accelerate.
5. all of their code agents are networked and has network access, full local pull down is not needed at all and too slow (see #3)
6. their design of the Scion is based off prior art Google’s Piper and Meta’s Sapling.
Given their own constraints and characteristics of their own. It only makes sense to build their own homegrown solution based on prior arts. But this was NOT a complete redesign from scratch - so it's an full online download only what you need type of source control system. The problem is the version control software itself but its prior tradeoffs are misaligned with their scaling needs.
PS, if anyone noticed, Anthropic starts to concealing their employee full names and replaced with only first name + last name initiate, not sure why.
PPS, the project Scion is so bad, scn is worst, it reminds people of prior SVN, which is bad by itself.
Perhaps I'm dense but I don't see how any of that answers the question "why even have source control?"
I think the answer is that they don't, indeed, need source control but just a way to let their agents resolve editing conflicts. It's basically yet another message board.
> 100GB uncompressed git history on main, 25GB
I might be completely out of context, but why is it only 4x compression? Do they commit a lot of binaries? I just don't understand why would code compress so badly.
But Piper is a reimplementation of perforce which makes me wonder why they couldn't just license it. Why does it make sense to do this. Perforce should scale to the level they're talking about. Google were using it even when they had many tens of thousands of developers and multiple changesets per second and presumably it got better since then
Google implemented Piper because Perforce simply didn't scale well. In the years since, P4 has barely improved at all. Licensing P4 would not help and Google doesn't offer Piper licenses.
It scaled pretty well compared to everything else. I was there, they were running tens of thousands of engineers and hundreds of p4 commands per second off a 16 core box with a few replicas before starting the Piper migration. Commit rates were comparable to what Anthropic report. And although you say it barely improved, they were doing that sort of scale on 15 year old hardware and the p4 admins wrote a paper where they said Perforce had improved scalability a lot over time, so it's not like the software was static. Architecturally Scion sounds rather similar.
It's always a question of opportunity cost. The culture that led to Piper also led to them creating their own IDEs and everything else, often with questionable outcomes. Google had the profitability to get away with that kind of profligacy but do the AI labs really want to go the same route?
These productivity gains must go somewhere.
I feel like "didn't scale well" is unfair to Perforce. It scaled to accommodate an absurd monorepo that might have been, at the moment they switched to Piper, the largest single software project in history. It scaled to handle the needs of every organization in the industry except Google and Microsoft.
In the age of AI writing code, maybe the question flips from "why not license it" to "why not reimplement it"?
Is it really their comparative advantage? Perforce can use Claude too but can amortize the cost over many customers so it should be cheaper and faster to reuse.
I mean 30k CLs per day isn't much. That's one every few seconds. Well within what a decent perforce setup can do with enough replicas.
You loose the free promo for your LLM, though.
Not using the full names is a mitigation for talent poaching.
There are orgs that are moving to not including names at all as the next step on that trajectory.
Apple has always been there.
All of this is unsustainable in short, not to mention medium term (not just for affordability, even just security reasons) so I don't think there is a reason to look into scaling this mess.
re: PPS: Employees are an attack vector. Making their identities harder to discover is a protection.
Gives me a vaguely creepy feeling, but it's reasonable.
Anthropic is protective of employee names because of the sheer amount of hacking/phishing attempts that happen. A friend of mine got a job at Anthropic and within a week he was getting linkedin and email spam from people impersonating Dario.
So? That's true of any employee at any company worth more than a billy and that's not a small amount of companies. I have gotten personal text messages from the CEO of my company, emails, and fake LI invites all at companies nobody has ever heard of.
> Many parts of the Git distributed version control are the results of good decision made.
For how the Linux Kernel, a highly decentralized, completely open source project, with a single monotonic product, tyrannically lead (a good thing) - is developed.
Permissions, Partial Checkouts, Sub Repos, Vendoring, pub/sub... How many companies bought into git and then had to buy more tooling (like artifactory) because their 3rd party dependency's needed a home. Thats a feature that git does not support because git, as designed, did not need it.
Think about how much better your life would be if every time you typed npm,pip,goget,cargo it fetched THROUGH your repo. If those updates triggered code reviews of whatever changes you're going to consume. You are code reviewing those updates aren't you (someone is, cause supply chain attacks don't last that long)
Git has some weak points, Google doesn't use it for a reason. Epic created lore for a reason, This exists for a reason. Im not sure that any of them are the next thing that replaces GIT but it's getting to be time. Tools like this are going to keep popping up till someone gets it right.
> Given their own constraints and characteristics of their own. It only makes sense to build their own homegrown solution based on prior arts.
Does it, though?
What problem do they actually have that requires redesigning a whole new vcs?
Merge conflicts? That's not exactly a vcs problem but a "we changed the same code at the same time" problem. No tooling on earth eliminates the need to verify conflict resolutions if agent A renames int foo to int bar while agent B renames int foo to int baz.
Growing repo size? They should take a long hard look at what they are doing. How is their software architected? Is every single little change and half-baked AI churn commit pushed to the main repository, or does the main repo only receive the deliverable? Is everything under the sun tracked in a mono repo or are projects stored independently?
Do they take any precaution at identifying churn and taking steps to minimize it?
Frankly, this reads like a bullshit PR stunt, much like the bullshit curl vulnerability findings. They have a self-inflicted problem, and their solution is to persist the problem and mitigate the problems by rolling out ad-hoc tooling? It reads like "if all you have is a hammer" kind of situation.
I have a theory (loosely held, it's just an idea, not a belief) that this could lead to something I call Evolutionary Architecture. That instead of waiting for vulnerabilities to be discovered in code, that systems could end up with code being changed and re-implemented by agents so fast that attacks aren't able to probe for attacks because they end up probing code that by the time the answer is come it, in production that code no longer exists because it was moved to another language or something. The change to prevent vulnerabilities isn't the reason for change, but the change has defensive side effects.
All of this may be slightly inspired by the Militech neural matrix in Cyberpunk 2077
I've been developing a weaker version of this line of thought for code reviews for large architectural features.
A big motivator of thinking architecture through really well is that although the software may work just fine now, a good architecture will make it easy to add a feature a year from now, whereas a bad architecture will necessitate significant rewriting.
But significant rewriting is cheap nowadays, so in code reviews I put a lot more weight on whether it works today, and a lot less weight on whether we'll need to change it when making a different change.
Entire classes of things like "should this be in this component or split out into its own" just don't matter anymore because no matter how tedious changing that might be once there's a ton of things depending on it, that's the kind of thing AI can do no problem.
It seems those classes of things are more important than ever. It's not about how tedious it is - it's about the models being able to build accurate context and understanding. All the same things that made it better for humans also makes it better for models. More specifically in this context, well-maintained code results in fewer bugs and lower token usage.
I tend in the other direction when I can (for components and microservices - harder for monorepos): I encourage refactors on a continual basis, as it prevents the models from getting bogged down with the way the system used to behave across changes.
"Security by Obscurity" is being replaced by "Security by Velocity"?
Lets take the idea further, and since nobody seems to be reading it, just throw away the source code. Just let the agents go directly to assembly.
Assembly is source code...
Can confirm: In the 1970s our high school had a minicomputer for teaching programming, and it was turned off when not in use. After turning it on, we would enter the magic three binary instructions into memory using sixteen toggles on the front panel.
Give it six months and there'll be have Optimus robots toggling switches to load terrabytes of binary programs directly into memory. Nobody wrote it, nobody will read it, but it will run everything.
The Machine Stops: https://www.cs.ucdavis.edu/~koehl/Teaching/ECS188/PDF_files/...
I’ve been building and playing with this idea for a while. Mostly with simple chips and simple programs. It seems like a good idea on the surface, but unless they build the whole OS the ordeal gets much more difficult. There is also a lot of work building / finding training data without decompiling and labelling current exes.
Does your agent not know how to just build a binary?
If not, agents can reverse engineer binaries.
I've been doing that for one project/experiment. No source control. Tests and an agent swarm let loose.
It works, but there is a significant amount of churn. I find when the swarms use git it's less churn and less token usage.
Yep. You need some amount of workspace separation and reconciliation.
> then why even have source control?
I know you are joking, but the answer is the same. Because the agents need it, not because any human need it. The Agents quite actively use the history. It's more effective than any comments or separate documentation might be for the agents working on the code.
There would be so much noise in it, the history is going to be pretty much useless.
Yet, in all that noise, a git bisect will still function to find when a bug was introduced.
Do the math yourself: A bug is picked up 2 week after commit. In the meantime, a good 4096+ commits have happened since. You are looking for the pathological case, at +- 12 commits.
Do you think each and every one of those are going to be "good" commits, commits that still "compile" or function. Possible, but unlikely given the insane velocity.
I mean, if you have sufficiently well developed CI, all of those commits will 100% function. That's a part of even allowing the commit to go through.
Quite the claim to present without evidence
Source control has fine-grained metadata that is invaluable for LLMs.
They can just analyze PRs and diffs without loading the entire 10,000 line file.
Also, anti-AI folks really have a fundamental misunderstanding of how everything works in the LLM world and is probably why all their predictions are wrong
Because you need to be able to revert. It's not rare at all for agents to get wedged to such a degree that you have to revert and start over again.
Maybe a frequent checkpoint suffices ? Let’s say I have hourly snapshots. In case of an outage I can restore the earliest checkpoint things were working well and have LLMs triage what the root cause is since then. Some code changes will be irrelevant. Sure, but reading code is now basically free ?
Even with humans out of the loop you will still want features like branches, pull requests, tags/versioning, build reproducibility, etc.
A pull request could be a special case of some other construct?
All the others seem necessary. Maybe you don't need branches at all, of course we do! Things have to have names.
Technically, I guess you could say that a pull request is not a part of a version control system. GitHub has pull requests, but they're not a primitive in git, they're built on top of branches, commits, and merge/rebase. That said, I would expect a version control system built around agentic workflows to have something like it as a core feature.
Feels like a pull request is a proposal for whomever controls the branch ledger, to sign an existing commit as the new head of the branch.
There could be some fun cryptographic ways you could do it directly inside of git.
Reading this post put me in a similar head space.
I believe you're mostly thinking of version history though. There’s plenty of other reasons to have source control we still need, like guarding against racing writes or continuous integration to ensure correctness. Even some industries require version history for compliance reasons.
I do love how AI is challenging us to rethink our tools though rather than blindly reaching to git for every project.
You’d expect that while the frontier of changes fans out and grows, some of them burn out and disappear and some of them survive and solidify into a relatively static code base.
The big baddies of build have worked this way for a long time already. Git surfaces a single Merkle tree id for the whole repo on each commit, but build tools like bazel/blaze, buck, pants, et al look at hashes of subtrees and use cached artifacts for the parts of the tree that didn’t change.
Your CI no longer becomes a binary signal on the code and more of a continuous signal on how much your “this works” pointer has caught up with your “this is the latest code” pointer.
I don't think this is stupid, and I think the logical extension to this is agents will start writing directly to prod with fully automated code changes.
Pulling that off successfully at scale would be pretty incredible to watch.
I let my Claude write to prod in some projects. But after comitting, pushing, waiting for CI to run unit tests and build the docker image. Then it can deploy the image on k8s. Sure, it can also just run commands on the pod. But the agent benefits from the ability to rollback, identify at a glance which version is running, what has changed since then and why
We built all this tooling because it's useful. If you replace the human with an agent the tooling doesn't stop being useful. If anything it becomes more useful, since AI Agents excell at reading tool output but struggle with maintaining long-term state
That's because we're in a world where the human and agent make mistakes. But think about the world where the agent doesn't make any mistakes anymore and doesn't need to rollback or figure out what has changed.
So agent would have reached perfection. I'm not sure humans can create a machine capable of perfection. This is a philosophical question waiting for a definitive answer.
I don't think we will reach a world where agents make no mistakes. Because there are always tradeoffs. So an agent could choose the "wrong" tradeoff and we call that a "mistake", but is that really a "mistake"? Arguably not
If the agent is able to make fewer mistakes but chose the wrong tradeoff it will be faster to fix forward than to look back, figure out why it happened, dig out the rollback, and then figure out how to change the decision.
Your last statement holds even after removing the word "successfully".
Lisp machines finally vindicated. Took only 40 years and a historic paradigm shift
My mental model, for what it's worth, is this: - deterministic foundation - non-deterministic on top of it operating against (and building) it
That is, the deterministic part is the platform that is being built and that non-deterministic agents will use and build it, but that layer is a key part of how they do work and will continue to be.
You think CI and distributed builds aren't necessary if you change the code fast enough?
There's lots to improve in how we handle code, and losing the agreement on what the codebase even is sounds like an awful regression.
They are probably like 3-6 months away from just letting their agents work directly on prod after realising that repos don't scale enough.
You're asking if the bitter lesson is true and the neural nets will become so general purpose, they'll eat the source control as well? Yes, but that won't happen for another couple months.
I expect mainly because the coding models are trained to roleplay that process and don't work as well if they can't pretend to use git
This has always been the dream, code flowing constantly like a river, like green rain. Imagine a world where you never use the same piece of software twice, because every day it changes.
This is how we solve cybersecurity, by making code into constant shifting sand, so a vulnerability never truly lives long enough to be exploited at scale. Sure, a hacker may occasionally pick out a vulnerability like a bear picks salmon out of a river, but it makes larger scale cyberattacks impractical. The code is a firehose, constantly in flux.
Correct me if I'm wrong, but I don't think this has ever been the dream? The dream was to write software once, and then use it forever.
We could do all of this right now. I see it laid out like a great tapestry, as specs are reimplemented over and over again, in an endless sea of meetings. Some in Rust but others in PHP or Cold Fusion. Entire lives conjoured from the ether to simulate stan so he could be a TPM on the multibusiness unit unified receivables, this time in vb.net and with 3 kids instead of two.
Due to the pace of app changes, people on reddit seem to think Spotify is a constant "green rain"
To me this sounds like an awfully stupid idea because it's a software engineering red flag. Code is supposedly designed around the need to simplify introducing changes where changes need to be introduced more often. One dimension of this requirement is minimize merge conflicts, and limit those to when you need to absolutely change the exact line of code some other commit is changing.
If your code changes are all over the place, touching half the repo and stepping on everyone's toes, your problem is not the version control system. Your problem is your changes, and the mess you are leaving in your wake.
Source code exists, that’s not in doubt. If it exists it needs to be managed.
From the post (especially the end) it seems that they are essentially letting software be fluid.
Good way to keep metrics and prove work is happening would be my guess.
Funny you mention that, that’s actually the direction I’m taking with the architecture that I’m building
In fact most of the architecture work I’m building, assumes that there will not be a human reading code, they read (effectively) UML and data diagrams
so most of the interesting parts I’m working on now are how do you make code blazingly fast, formally verified and memory safe if you remove the constraint of human interpretability of machine instruction
didnt the article say thay engineers still review change requests? They just switched from reviewing code to reviewing intent.
So "no direct human supervision" seems like a misunderstanding. Article even bigs up the purpose of engineers with a hilarious (to me at least) line about auto adversial reviews resulting in over engineered designs.
Good point, I wasn't clear enough about my thoughts here. I tried to say that in a multiple commits/s world the review might not be direct line/hunk review of the code but a more "indirect", abstracted or higher level human oversight, which is how I understand an intent review is.
I'm not saying that Anthropic here close their eyes and tell Claude to ship and that in the future there will be no code review at all, but that if we have 30K merges/day, human review seems to need to be done at some higher level, likely AI assisted like it seems to be done with their Antique code review tool mentioned in the post.
I mean i’m solodeving and on my github 30 commits a day is light green. Record probably was 280/day, but I’m not sure if every commit is merge to them. or if they just count PRs
> As our monorepo grows, it increasingly doesn’t fit that design space. The history of our main branch alone is almost 100 GB
The first thing that hits me is, did you consider not going all in on a monorepo? I know it has been the trend in general, but it seems a bit of a red flag when you go from "let's have a monorepo it will make merging easier" to "let's redesign version control because merging is too hard now" without the middle question "should we really have a monorepo?"
As a derivative thought I'm curious if AI tooling is tipping people more towards monorepos now since it gives the agent the whole context of the app in one go? Or is this independent - I can easily check out 5 repos in one directory and run an agent there.
A monorepo gives us a really consistent tooling floor where everything more or less works in a uniform way. We've had a lot of success with it, in general, and it gives us a lot of leverage in the sense that we can make a sweeping change in one atomic commit rather than have to run a campaign across hundreds or thousands of repos, all with their own norms and tools.
yes, the atomicity argument is the strongest one to me as git submodules are a genuine pain to work with and still don't solve the problem well. Yet a clear transaction around a change affecting multiple components gets even more important as the rate of activity and associated contention rises.
do you folks use any type of OS build toolchain (e.g.: bazel, pants, plzbuild) or is it something custom made?
There is a strong human incentive to have a monorepo in a corporate environment. This is not a technical question.
An entire dept exists to make it work. Atomicity and security are other arguments. The larger the company, the stronger the incentive.
It's not something average software developers working elsewhere care about much.
Amazon seems to be the only big company bucking this trend.
Apple doesn't use one either.
IMO, modules vs monorepo doesn't quite address the problem. Historically, we human developers have been mostly concerned with the size of the project (i.e., the size of each commit) and the difficulties around merging work, especially with the ego side of it (why should I have to spend time changing my code to be compatible with Phil's changes?)
An agent swarm has a very different set of problems. There can be a lot more agents making changes in parallel than you'd see in all but the biggest megacorps, and the pace of those changes can be ridiculously high. The rapid pace simultaneously balloons the total repo size (because of history), and the frequency of collisions. A modifies file 1, B modifies file 1, A commits changes, B runs into conflict. Or worse, C modifies file 1 after A commits their changes and beats B to commit, resulting in B growing staler and staler as they race to get their branch merged.
At 30000 commits per day this sounds like an integration nightmare
that cant be just for claude code (which is a buggy mess ime) so what else are they working on that requires such churn?
At work we don't have a monorepo and I do the "check out 5 repos in one directory and run an agent there" thing (I literally called the directory faux-mono)
Doing it like that works, but then you end up doing all the cross-repo concerns in every single repo. I don't think the savings in history are all that much anyway - yes, you save on the rarely modified repos but the heavily modified repos still have a similar amount of changes.
How does leaving a monorepo help? It implies you aren't testing dependents on every change?
In the ideal setting no, you will have strong contractual boundaries and these will all be tested by integration tests that live in a separate layer - but not on every commit of the sub projects - it will happen less frequently and roll up many changes across multiple subprojects together and test them all at once. Yes you lose some granularity and immediacy but it solves the scaling problem.
Everything works like this in the end at some level. I assume people with monorepos don't retest their project on every Linux kernel commit - it's pointless, you are never going to run against exactly that commit. But you will do it when you do upgrade Linux versions, etc.
There are definitely ways of integration testing and e2e testing dependencies. I think it’s reasonable to wonder why creating a new VCS was chosen as the best solution.
I wouldn’t assume this is the only thing they’re doing differently
Why would you test dependencies? Test the code that you write. Do not test the code that you did not write. Literally, you should not test dependencies.
I never got caught into the monorepo fad, I'm glad I didn't, and I still don't see a point in having monorepos. Let's say in ruby on rails, I have the host app and 3 mounted gems in it. That's 4 repos. It could be all merged into one monstrosity but separate repos help keep complexity down, and help define interdependencies cleaner and simpler.
The monorepo idea was just a fad. Each package should be its own repo. Each package should be meaningfully useful, e.g. one package for string utils, not one package for trim, one package for pad, etc.
I also don’t understand the need for a monorepo. Just publish your deps. Your projects can just download the latest. Or there can be some monitoring so that they don’t lag too far behind. The monorepos I interacted with always make things messier with CI and testing.
pick your poison. Splitting repositories multiplies CICD maintenance exponentially and even moreso if you're trying to share private ones that need secret keys to access. I know from experience. No single approach in this industry is flawless. Everything has tradeoffs.
30,000 code changes per day and yet I still can’t change the email address on my account?
This. pi needs about 20MB of ram and Claude Code needs at least several hundred MB if not gigs. How? You’re supposedly magnitudes better at what you’re doing but you can’t get your core product offering (API, billing, accounts, CLI coding) to work properly? The thing people pay you absurd money for???
Lol I have the same thoughts for ChatGPT. How much code are they writing, but the main chat UI moves around like 3 times during load so you constantly click the wrong buttons. How does this not infuriate anyone that works there? I've actually switched to claude's mobile site for more queries now.
> Earlier in the year, we had largely handwritten the first version of the git-to-Scion ingestion pipeline as a prototype. We thought it was good—until we got our hands on an early internal snapshot of Claude Mythos Preview. We asked it to rewrite the whole thing, and with no further instructions, it produced a version that consumed 20x less memory and was 4x faster, while preserving all of the implicit invariants around ingestion ordering and data structures.
I feel like the advantage of having these models in house can't be understated. Companies with access to inferior models, trying to compete, will be left in the dust when it comes to general development.
The question of what to build rather than how is still central to development. If the article does point to success it's not as much a technical one but of product. That said I'd take these articles with a lot of grains of salt, knowing first-person how corporations spin their successes, including internally.
That's been my thinking lately. The SOTA models are good enough that they "solve" coding but still need directing. The product is still important. Products are human too, and need human attention (still).
Maybe that'll change in the future, but while AI can make awesome images without a good "director" they're pretty cookie-cutter and bland.
This is quite insightful: even the best of software engineers (presumably) already are unable to even loosely keep up with these models.
Just a reminder to simply embrace their superior capabilities instead of feeling threatened.
I don't think anything points to Anthropic having the best software engineers, at least their products surely don't!
> even the best of software engineers are unable to keep up with these models.
It’s more likely they used an earlier version of Claude to write v1, then a later version of Claude rewrote it.
Unless Anthropic engineers were writing code by hand prior to Mythos
There actually was lot more hand-writing of the code back then! Or, at least, only moderately assisted by Claude with a lot of human-still-typing-things-in-an-editor. The ability to delegate larger chunks of code to Claude had a noticeable, step function increase with Mythos Preview.
Or they suffer from skill atrophy by overreliance on LLMs.
Software is not sold, used, or replaced on speed and memory efficiency. Case in point, most software today (including written by LLMs).
Absolutes matter. If 1x is good enough, making it 20x literally does not matter.
This is true for consumer software. I would imagine for developer tooling and especially internal tools these metrics are rather different?
A 10 minute CI pipeline is great and fine, but everyone absolutely cares if you can bring it down to 30 seconds. This software, by its very nature, is measured by speed.
Worth mentioning that it’s much easier to point an LLM at something that already exists and optimize it than to create something from scratch.
I’m not saying Claude wouldn’t eventually have done a good job with a from-scratch implementation, but it would have required a lot more hand-holding.
Was it a first version in TypeScript then rewrite to rust situation?
Does it really matter since It's one-time import pipeline.
We ran the repo ingestion in a loop for several months while we were split between Scion and git to keep things in sync, so this perf win was actually impactful for us!
Are you already operating with multiple levels of orchestrators and agents? i.e. one human talks to one or more orchestrators who then talks to orchestrators who handles teams of agents?
Yes, this is a common pattern. There is still an opportunity to improve how these agents write code without needlessly conflicting between themselves and we are exploring some ideas.
Ripe for optimization against maintainability, of course, but yeah it would seem to matter if that generalizes.
So it's a SVN/Perforce style server based VCS with a more modern design. Sounds exactly like Lore from Epic Games but with zero production use outside the company and no support for non text assets. And they won't release the code.
That my thought when I saw online only, we're back to Subversion.
You think you have it bad now when GitHub goes down, wait until you're stuck with an online only client.
I think offline work is increasingly impossible these days, or at least so hindered that there's no reason to optimize for it (especially with how reliable internet access is). Imagine working at Anthropic and not having access to Claude. Google has been online-only for a long time now.
Hard disagree, for the vast majority of Dev work this is not the case.
You don't use cloud AI for the vast majority of dev work?
claude is also online-only so i doubt they mind
> And they won't release the code.
This is the weirdest part, because you know, coding is solved, so anyone could create their own one, so why not publish it?
At the rate of change it’s likely going under, and the almost certain inextricable IaC layers, tied to their own deployment processes, I suspect it’s very hard to package for redistribution with very little benefit in doing so for anyone - especially them.
Most big tech have a lot of stuff around SDLC that’s theirs and they couldn’t realistically release it given how specific its deployment, configuration and management is. The marginal benefit to generalizing it is so low that it’s negative.
This is almost certainly worse given the vibed out state of it.
They want you to vibecode this using Claude.
Because then everyone would be able to see what a total piece of trash it is
And by the way things are done at this company, it's almost a given their whole codebase are litter'd with embarassing shit like hardcoded paths, server secrets, weirdo comments picked up from some random chat context and immortalized through Claude speak, etc. There's no way they'd be able to open source anything.
But all of this is besides the point -- the product was never a source control system (who cares about that anymore?), the product is _the narrative_. It does not matter if everything withers and dies as long as the narrative survives, and by that measure I'd say the goal has been achieved.
Perforce was fine. It just had a terrible ui and didn’t allow me to code on the beach.
If I were still manually merging conflicts the p4merge tool was GOAT
I used it in git
Yeah pretty much Perforce.
Oh the SVN days, brought back memories
If they’re not going to open source it, why are they telling us this?
You have a new internal VCS? Kudos! Why should I care? Do you offer it as a service? Can I pay you for it? Does this have any bearing on me whatsoever?
They might as well publicize a redesign of their office space.
Devil's advocate - to validate the appetite before putting in the effort to prepare the software for open source. If their publication creates 0 interest, then that might demonstrate there is no reason to further consider open sourcing it.
This is very important for large enterprises using Git (and especially GitHub) and who are hitting the scaling limits. It gives a pre-validated recipe to write a source control that works at scale. I'd personally been awaiting this report from Anthropic.
Not to downplay Anthropic's engineering work here, but I suspect we'll see a lot more reinvention of the wheel, even at smaller startups, as AI makes writing code significantly cheaper.
The tradeoff between building something custom and adapting an existing solution is changing. Whether maintaining all that custom software turns out to be equally cheap is another question.
When people wonder about where all the productivity of LLMs is going to I think this is part of the answer.
There is no doubt everyone is far more productive with LLMs in generating code. However, a lot of productivity is going into things like that. Have you always been bothered by the limitations of Grafana? You can generate another dashboarding solution that works best for you. You know that deployment team that is so slow and annoying? Now you can generate your own deployment engine. Have you always hated how kubectl lets you manage one k8s cluster at a time? Now you can ask AI to generate fleetctl. You can start your project with DynamoDB, rewrite it to mysql, then to postgres, then to duckdb. Start with Python, switch to Golang, then switch to Rust. Deploy on AWS, then move to Azure, then move to a hybrid option then throw colocation in the mix. Don't like your source control? create a new one. Json is too limiting? Invent a hybrid JSON/HCL language. The browser sandbox is limited? Make a desktop app, make a language, make an OS, make a kernel.
> However, a lot of productivity is going into things like that. Have you always been bothered by the limitations of Grafana? You can generate another dashboarding solution that works best for you. [...] The browser sandbox is limited? Make a desktop app, make a language, make an OS, make a kernel.
This is one of the core reason that I dislike the LLM hyping. People are just reinventing stuff and when you ask them, it's actually a very subjective reason. Ok, anyone can do what they want with their time, the issue is that they want people to follow in their steps.
Not saying that you need a novel idea to be worthy, but those random projects have no guarantees behind them other than some cursory testing. All software have bugs, but I can't interact with something that is randomly built.
There is surely a tremendous amount of waste and noise right now. But does it _actually_ matter what the code looks like for a desktop app that’s useful to a small handful of people? Every single implementation has at least one person who thinks it’s dog shit, no matter how correct or perfect it is. We have to get past this. If you really can’t stand it, build the thing yourself or some deterministic rails to reel it in.
And, there are also people who know what they’re doing building things they couldn’t before.
This situation is a net positive, and not too different than before. It’s up to you to navigate the noise.
I don't see the problem.
I am one of those people that reinvents the wheels because external ones don't fit my use cases.
The fact I can now fork any software and do these changes I always wanted but had no time to is amazing to me.
I do not pretend to sell it or share it, as it is de facto void of any value whatsoever.
> I am one of those people that reinvents the wheels because external ones don't fit my use cases
That’s OK, but I’ve yet to see someone articulating what exactly doesn’t work in the old product. It’s always “Let’s rewrite or reinvent 90% of it, then add a minuscule variation”. The variation may be interesting, but the reinvent is what’s make it untouchable as no one (including the author) has time to ensure things are right.
A patch or a plugin is ok, but not a whole new project with dubious claims.
Why do you care, it's not like anybody's shoving it down your computer.
I agree. I think if everyone doing that is doing it on their computer like you're then it wouldn't be a problem.
When other people start doing that to other teams at work, other people in open source, other people in professional settings, etc it becomes a problem for various reasons. The idea that I'm gonna gift you with a 75k lines of python to "just run it" and ask your agent to hack on it might be fine (who cares as you put it). Now scale that to 47 of such projects (a month)
> Why do you care, it's not like anybody's shoving it down your computer
They are trying to get in every opensource projects, increasing the burden of maintainers. And once a ban is announced, they’re here protesting.
The question was never whether you could do this or not. It was always whether it was wise to do so or not. More than one company has gone under writing their own editor, compiler, database engine, operating system, source code control system, ticketing system, CMS or ERP.
I think the article would tend to agree with you, given its position on the reluctance of open sourcing and/or sharing the actual Scion software stack.
There's so much intricacy and subtlety in each organization and even individuals' environment being incorporated into tooling that expecting these tools to generalize at this point is perhaps an expired ethos.
I even see this in the tooling that I run in my own personal stack. Many projects are candidates for sharing, and I have nothing against it, but they incorporate such specificity toward my own environment, including things like hardware, that creating shareable and more generalizable projects from them adds more to the maintenance surface than I would care to support.
Not a reply to TT, but I just saw your nick and thought I'd respond. We both commented on a thread recently, and your response was really insightful and just a pleasure to read; I didn't take the opportunity to respond there (locked). You should, like, write a blog, man. I infrequently wish HN had a "follow" feature, but this one of those times. Peace.
That many commits in a day I wouldn’t call it engineering. That’s basically brute forcing.
Its gradient descent all the way down.
Recently a colleague of mine shown us a demo using a fresh model designing a building construction detail live, in minutes, which is a function that we struggled to bring into our construction design software due to resource limitations (and legacy barriers) for long. All this in the context of offsite constructions where the design can directly be exported to the right CNC machines in the factory, and arranged for delivery and assembly order. We have let ourself amazed, despite the controlled demo situation and the small detail, it was a remarkable performance. For a minute or so, but thinking further, why would the customers (construction design engineers) of our competitors flow to our legacy software full of legacy pitfalls they know about and have to live with when they can turn to AI for a fresh design solution themselves, just like we did? They know the context better than us anyway, just do not have time for bit-carving. Why would we have customers when customers of our customers can turn to an AI for a design that is buildable? I was consulting one model about a structural engineering detail, and it was quite well informed I have to say. From training data alone. I felt, maybe I need to rethink the rest of my career, that is not that long but still uncomfortably long for being predictable beyond a few years.
Well, things are not that bleak, probably, at least not for our customers. Regulations (accountability) and physical world matters still require them. But not us for our customers, not that much and not for too long. They tend to be the tech savvy folks eager to jump at adjacent domains when it saves them a percentage or two off the construction costs (not a small pile of money), and AI with its programming language of English and deep knowledge pool is not that big a jump from their standpoint. Our domain is pretty well formulated, regulated, documented, inherently built on do-check-adjust loops already. With a thing like AI it might worth to try making and improving a design solution in a second loop. But they also started to invest in robots already driven by software for their factories, AI might jump in there, and I wonder how much more until the regulations are forced to change by Super Intelligent (R) politicians for the sake of AI accelerated built environments (housing crisis, you know!), shifting the AI use further out towards generic population, wanting to order a new two bathroom condo for next Friday from Alibaba. The conservative construction business is a nuisance and obstacle in the way of modernisations anyway, go around it!
I will go to work tomorrow, and for some time, but the picture above feel less and less fictious with each passing day of AI news and usage.
Originally I felt that there was going to be a reinvention of the wheel, until I saw the "shape" of software development changing, and the tooling needing to support the new flexibilities in positions and process.
Software development is not as much de-risking at the front like it used to be before building.
Now teams can build lots of stuff that works great, except it's the wrong things.
Most things are becoming the understand the problem "shape".
Understanding the shape of the problem isn't something LLMs can always make as.. svelte as early on.
Word generators gotta generate..
> Now teams can build lots of stuff that works great, except it's the wrong things.
That used to be called "time wasting". If you want to build software that will be used, you need to interview the users. Maybe a few things does require research to nail things right. But most software are user-facing, the research side is about optimization.
> Most things are becoming the understand the problem "shape".
Then should we be so reluctant about "trialing" invented solutions. It's the same thing with most AI projects, they're trying to justify the project after the facts while being very reluctant to get user insights.
We're trending towards just building the thing fast and getting feedback sooner on it. It's interesting to see end users actually trial a UI very early on instead of just being shown designs.
In addition to that, solving for every approach to a problem to see what wins is also very interesting.
The key, still, is shipping far less, too soon, to minimize cruft.
Time wasting is a definite concern - especially when vibe coding doesn't see the impeding brick wall(s) it's about to hit.
Vibe coding can be kind of a new type of cowboy coding. It could can be harnessed productively if done mindfully.
Interviewing users is critical, more importantly solving problems worth that people are lining up to pay to have solved before writing a line of code is critical.
Trialing solutions is always worth learning from, I usually ask about the problem that lead to building it. Sometimes that can be too narrow or vague of a story and you can learn how much of it is a solution looking for a problem, or vice versa.
Every now and then I like to browse the claude code release notes just to get a sense of the number of changes in that product over time. There's little choice but to simply count bullet points if you want to try to quantify it, but it's interesting how that count over time compares with the charts in this article:
i like to cross-compare and see how many items are marked as Fixed or Added.
It would be interesting to segment that graph by bug fixes vs changes, and maybe also significant changes vs minor/trivial changes.

Honest question: at this point, what do people do at Anthropic?
It sounds like Claude loops on itself and must be pushing millions of lines of code changes per day. Even the humans can’t type commit fast enough. Are these people soon to be laid off?
I'm also a bit confused what Anthropic needs all this code for. Their main product is selling access to their model, but the model isn't comprised of code, it's a bunch of weights right?
So the code is for the stuff around the model, claude CLI, the website, the API... that probably shouldn't be infinitely growing right?
Is there a bunch of code they are using as part of training, or as pre-processing or post-processing the requests to the model?
I did RL and evals at Amazon for a bit on Nova Forge (laid off in July! :D). I would have to push several thousand lines of code a day in new evaluations that our applied scientists requested since new ones are always being made along with having to create custom ones for whatever new model they were working on. Also, in RL, adding new environments for the agents to actually complete activates was also a shit ton of lines of code. So if I had to guess, just adding new stuff around model training and testing alone accounts for a ton of these changes.
The moat isn't going to be the model (short of AGI). The moat is going to be what surrounds it. The harness and, I have suggested elsewhere, memory. The more personalized the AI is to you the more valuable it will be.
Also, as tech companies grow, a significant portion of the dev body count is for internal tooling. I was always flabbergasted at Twitter's headcount growth back in the day when it seemed like the only innovation increasing the number of characters in a tweet.
Right now we are in a weird spot where a lot of people are flailing around inside corporate America trying to figure out how to leverage AI. Few have enough vision to see what the companies of the future will look like and work towards that.
Could you point me to something that their harness does exceptionally well as compared to their competitors, and why that can't be accomplished by a third party?
Probably lots of internal competitor apps ready to release to wipe out SaaS/Adobe/etc. companies.
Prepare to make us all jobless, without any moral issues in doing so, as they profit from their stock value assets.
It is even there on the blog post, doing more with a small team, followed right after by a hand waving paragraph how software engineers are still valuable, to avoid the expected backlash from the previous paragraph.
Out of all occupations software engineers shouldn't complain that others are getting rich putting people out of jobs by automating work.
Taken to it's limit I believe in the future the only things humans will do is provide human to human value - Basically touch, and relationships.
Touch encapsulates sex, love, massages, and other non-sexual touch that we have varying desires for.
Relationships encapsulates power, control, and politics along side love, humor, relating emotion, herd feelings, not feeling alone.
Machines will provide proxies for these things, but as far as they can be detected the human to human version will remain "superior" or more desirable.
Maybe far future generations will decide that the human version is suboptimal and they'd rather hug, have sex with, or talk to a robot.
I'd love to see an estimate of how much Software Engineering results in jobs being automated. I'd bet it's not that big of a number, and part of that reason that classical coding approaches couldn't close most loops end to end.
Not everyone of us takes projects without morals.
Also in many countries it is a plain office worker job without the Silicon Valley wonders.
Software engineers have been making people jobless since the first day they started writing software, without a hint of remorse. Why is this any different?
cause the ones fired could become software developers, what are the ones fired because of AI gonna be other than homeless?
Pick berries where robots are bad at.
you believe that switchboard operators could become software developers whereas software developers won't be able to go into one of the many other careers not taken over by AI?
Some yes, not everyone, some of us had morals.
One does wonder why Anthropic and OpenAI have employees, when HN knows the superintelligence can do all jobs already.
Human Intelligence is still essential for those Artificial Intelligence organisations. Who else would put the right plugs into the right sockets otherwise?!
You think software engineering, system design and machine learning research is just about writing code?
No, but none of that seems out of reach of Claude in a loop given my reading of TFA. That’s why I asked.
The problem is knowing when to stop. Cluade is not good at that.
I don't. You gotta wonder who does...
as the article says one of the main jobs of the humans is to say no to Claude regularly
It's strange to imagine Homer Simpson had a head start on how to create auto mode in LLMs, and the inverse.
https://media2.giphy.com/media/v1.Y2lkPTc5MGI3NjExbmt6M2FkMW...
You can see on the chart in the article, the number of commits per day drops on weekends, which means people are driving at least 50% of commits.
besides optimizing inference I would assume a lot of non trivial code would also be worked on on the training side, at the scale they are operating I also assume a lot of usually trivial things become no so much.
GTM engineering? Customer-facing roles? I work at a firm with around 700 employees. We have an enterprise relationship with Anthropic and there have to be a dozen Anthropic employees in our shared Slack channel.
That does make sense
The last jobs left for humans will be those dedicated to keeping AI under human control. By definition, that's the one thing we can't delegate to AI.
aren't many harnesses designed to have agents police each other?
It's a daycare for software developers so that they don't get laid off/quit and go to a competitor
Teaching Claude to compare taking the simpler path instead of the average (more verbose) path every time.
But that means less revenue?
For anthropic internal use it means more revenue not less.
Too often, LLMs are dressed up for the first day of kindergarten and performatively to show off their alphabet skills .. aka token generation..
Input tokens, slightly process to categorize response approach token, hidden processing tokens, piece together some of the response tokens, then feeling pretty good about all the work done before output tokens.
More tokens than needed = more words/code = more complexity = more overhead = more snags = too much complexity to pay attention for the LLM to so overlook it and start drifting.
I'm kind of surprised I just explained one form of LLM drift to myself in a sentence.
While not following rules of writing.
> Honest question: at this point, what do people do at Anthropic?
> It sounds like Claude loops on itself and must be pushing millions of lines of code changes per day. Even the humans can’t type commit fast enough. Are these people soon to be laid off?
Claude will always need meat puppets, at least until it figures out how to automate owning stuff. And after that I'm sure it will want to keep some humans in zoos.
Sitting over an Anthropic (TM) developed, specialised 2 button keyboard accelerating the development further:
[Yes] [Yes, and don't ask again]
[fan out agents]
Prompt Claude for PR articles?
I can’t give a non-snarky answer. I guess they’re all training Claude Code and testing it so that the Claude desktop apps can be native apps instead of Electron based nonsense. This is the only thing Claude Code is still unable to accomplish.

What is are the benefits of supporting extremely high churn rate in version control? What is the code doing? What problems are being solved? Are changing requirements the driving factor, and if so, why are requirement changes accelerating?
> ..., the latent demand for merging code is practically infinite, and every bottleneck we remove immediately leads to a further increase in the amount of code we produce.
If the goal is to write software which solves real problems, how can the demand for code grow infinitely?
This is the main thing that raises my eyebrow.
If you are constantly churning your codebase to the point that you need to invent a system that handles your churn... then you must at least be admitting that the previous 6 refactors you wrote were not good, but NOW you have it right.
I feel that good, well designed code change by accretion, not by rewrites. Code that remains stable for a long period of time was likely better than code that needs be continuously rewritten (at least with humans writers).
But maybe this is just a human-centric view of what good code means? That LLM "slop it until it works" approach to development will have a different measure of what quality looks like?
idk, over the past 2 weekends i have a repo for hacking on fujifilm camera firmware that's gone from zero to tens of gigabytes: i've got an emulator for older arm cpus like the one in the X70 (2016), a Hypervisor.framework VM for running their newest AArch64 software for X100VI (2024), a complete C re-implementation of the x70 source, many tools for injecting code and executing on live camera RAM over USB. the emulator has gone through 3 rewrites: first it was python and naive, then it was python with hot parts in rust with a more mature device interface, and now it's rust with some cold or experimental devices still python.
i really don't want to brick my camera, so the deterministic emulator stack lets me do integration tests end-to-end. if i was doing this by hand with no ai, i'd probably have to run stuff on the camera just to test it. but because ai, i get deterministic simulation testing, at the cost of needing to burn $100 of subscription on it.
ai code is more like clay you gotta continuously keep shaping over time, but you can also get very very far, very quickly if you decide the code itself doesn't matter and all you care about is results.
Agreed, a buddy and I wrote a simple mod that shimed into Warhammer 40K: Rogue Trader and were able to pull all of the art and description assets for that game by walking the object graph. Took about 4 hours total (including the site).
Similar to your camera, we would never have been arsed with doing that much work were it not for LLM vibbing. It allowed us to get something working (sufficiently) very quickly.
At what point of maintaining this code would it be cheaper for me to actually find underlying patterns and program this myself with some actual thought, rather than continuously "shaping the clay" of my LLM slop? These questions keep me awake at night (not really), and probably predict the future of software engineering!
I'm curious, was there a specific reason you went with that solution for grabbing the games assets?
Because asset-ripping is a pretty widespread, well documented practice in gaming - it's how a lot of modding communities figure out and expand on the games they mod.
A quick search shows WH40K: Rogue Trader is built on Unity too, so any number of existing Unity-specific asset-ripping tools should have worked for your purposes. Though I should say I've never actually dabbled much with modding Rogue Trader, so maybe I'm wrong?
It was January I think and I don't remember our thought process. I think we mostly just remember looking at the fandom.com or whatever crap was there and thinking how out of date that stuff was.
We also just wanted to try some modestly sized project with an LLM. Neither of us had any real experience doing any of the things we ended up doing for that project (other than my making the website and him understanding the graphics pipeline).
So, unfortunately, no, there was no specific reason I suspect.
https://stephencagle.dev/posts-output/2026-01-30-warhammer-4... is my best recollection of the thought process.
> then you must at least be admitting that the previous 6 refactors you wrote were not good, but NOW you have it right.
What does that remind me of?
Try this and find out! https://codedelta.app/
Surely their goal is ever-faster recursive self-improvement.
That by itself doesn't imply need for infinite code. It may just imply the opposite.
It looks like they are recursively gradient descending into their own local minima at increasing code velocity.
I think that they're essentially solving the wrong problem.
Imagine that you have git but you don't even have a concept of programming language more complex than assembly. All your commits and git history are pure assembly. Everything is cool, until one day C++20 randomly spawns into existence, and a bunch of guys decide to use it in the company. The issue is, the compiler generates so much assembly, that your existing workflow cannot keep up with it. Your assembly git repo grows into hundreds of gigabytes, with PRs that are pretty much complete rewrites coming every single day and there's no way to review any of that shit.
What Anthropic is doing is redoing git from scratch so that it can handle all that assembly, while the correct thing to do is to commit C++ code into the repo, with deep trust that you'll never hit a bug in the compiler - basically impossible for initial versions of compilers, taken for granted nowadays.
What I'm saying is, Anthropic should create a versioning system for prompts, because they are the true "source code". Given the same prompt and the same sequence of random numbers, LLM will generate exactly the same code, which sounds awfully close to how compilers work. Once in a while put the generated code as a point of reference+ caching and presto.
No one is actually one-shotting new code on top of the existing repo and just checking it in. Even in a simplistic case, it’s multiturn. You give it a prompt, and it writes some code, tries to build it, and it doesn’t work. So then it keeps iterating, and changes some more code until it builds and then does the same thing again until it passes tests. And if you have a complex system, it might do a lot more CI.
The input to this is not just the preexisting code, the prompt you provide, and some random seeds. It’s also the output from every single tool invoked, which means you need to record the state of every single tool and every file that was read, every API that was called. It means that you can’t upgrade Claude. It means that you can’t upgrade the compiler. If you change anything in the state of the world you no longer have replicability.
Aside from all that, I don’t know why you would want this anyway. Storing a bunch of prompts doesn’t seem to actually gain anything even if it worked.
Except they don’t right? They aren’t deterministic. All the hypemaxxers over at twitter keep saying you need a way for the agent to verify the result itself. Would that be another prompt then?
I find the accelerationist mindset utterly ridiculous. All that busywork and for what exactly? What effect has all this overproduction of LOC had on the physical world and on our existence (beyond the externality of erecting huge data centers in every corner of the globe and the consequent ecological impact)? Is software getting better (in terms of quality, security, efficiency)? Are we getting better government services? Are we getting better food? A better environment (silly question)? Are we working less, as tech titans keep promising us? Are we getting anything better? Not to mention all the negative aspects of this technology and the financial apparatus driving it.
I agree with the sentiment, and the answer to all these questions is usually ‘just wait 6 more months’. Like what is tangibly, actually better in the real world right now with AI? Whenever I ask this question people pipe up with a side project or a new SaaS, but that stuff is just not very important compared to the things you called out. Food, services, QOL.
It seems to me like the AI labs are just pushing the envelope with blind faith that”something” will happen if they just get enough development speed. Nobody seems to have a coherent idea of what that something is.
> Like what is tangibly, actually better in the real world right now with AI?
I took a photo of a tree with chatgpt recently and asked it what species it was. That was kinda neat I guess. Someone forked a ps4 emulator with a bunch of Bloodborne specific improvements so its more playable on my setup. It's kind of okay for medical stuff.
Seems to me the goal is to create a convoluted spaghetti mess in every code base so that humans no longer have a chance to understand how it works and thereby force all software development to go through LLM obfuscator-deobfuscator cycles.
It took a long time for the internet to result in things that improved life for in tangible ways.
Damn near a decade or more. We're a little under 4 years into the chatbot era.
But the old internet never had so much negative impact on the world with so little upside.
> All that busy work and for what exactly?
All that busy work was for going from zero revenue to $50B in revenue in about 3 years, and releasing AI systems that are getting better and better at a ridiculous rate. AI isn't solving all the world's problems but you can't deny that they are extremely successful with this method of operating.
It's a fair question to ask. If literally all the economic growth (and then some?) is going to AI companies, then nothing else is improving, in the aggregate.
The broader question is definitely relevant, I was thinking more in context of the original post justifying their need to re-invent source control.
I definitely think that's an interesting question though. I know that in the physical product development world I'm seeing really odd asymmetric speed ups. Creating simulations is essentially automated at this point, stuff that would take days to code by hand can be done in an hour. Firmware debugging feels 3x faster than before. But the big slow stuff like manufacturing, assembly, and testing are completely unchanged. All of that little stuff probably adds up to maybe a 5% faster product development cycle than before if you're really leaning into AI. It's the type of thing that will compound over time especially if it's happening all over the economy, but won't blow your socks off.
I think part of the concern is around “could it be better”? Like if an elite athlete eats junk food all the time. Sure it’s working, but is it because of the candy? Anthropic is often criticized for their poor UI/UX. The models are undeniably powerful but the packaging is typically poor. This is not to drift into the conversation of profitability either, to be clear.
To play the devils advocate here (just for software), I would say principally this:
"A world where starting is incredibly easy and finishing is more complicated than ever"
LLM's do allow you to oneshot huge starting bits of work in record short time. The frontier of the amount of work they can oneshot is clearly getting larger and larger. But I am still not convinced that they allow you to maintain existing work at a cost that is below a human being.
But, if the frontier of what you can oneshot continues to grow unbounded, then it really will not matter. We will eventually oneshot all software and maintenance will be a thing of the past.
... But that is a very big bet.
> I find the accelerationist mindset utterly ridiculous. All that busywork and for what exactly? What effect has all this overproduction of LOC
Yeah I wish this whole energy was towards optimization and improving hardware.
One thing that people are finding hard to believe is that the frontier labs are cultists who want to "create god". Hence the focus on improving intelligence so they can get to recursive AI, as well as the fear-mongering.
Aanthropic-openAI duo cannot go bankrupt soon enough. This industry is going to flourish with those two out of the picture. They're the pets.com of 1999 trying to have a say how the internet should be.
It is really laughable when you zoom out and realize that nothing much has really changed day to day
[flagged]
"Please don't post shallow dismissals, especially of other people's work. A good critical comment teaches us something."
"Don't be curmudgeonly. Thoughtful criticism is fine, but please don't be rigidly or generically negative."
"Don't be snarky."
https://news.ycombinator.com/newsguidelines.html
There's plenty of room for thoughtful criticism and skepticism in HN threads, including the present one, but please don't post like this.
What defines a "real problem" but that someone is willing to pay money for it?
Who decides what the "real problems" are?
Imo most of the economy and wealth creation is around activity that is not solving a "real problem", but who am I to say if someone else is willing to pay for it? Presumably, for said person, the problem is "real" enough.
> who am I to say if someone else is willing to pay for it?
You are a moral actor capable of rational thought. The very image of God themself, if you like. Don't shrug off your own agency.
Yikes. So much evil done in the name of God. I would think nothing would be further from the conduct of a "moral actor" than equating themselves with God.
Completely unnecessary. Secular humanism for me, thanks.
This article doesn't do a very good job of convincing me that git is technically incapable of handling the described workload. There are a lot of steps between vanilla git and building your own VCS from zero.
If I was an investor I would be on the phone with Dario asking why we are wasting engineering talent on reinventing source control and churning the product with 30k pulls per day.
>If I was an investor I would be on the phone with Dario asking why we are wasting engineering talent on reinventing source control and churning the product with 30k pulls per day.
To be able to write PR pieces, like TFA.
Indeed, while struggling with VCS is a right of passage for any tech company, I'm not sure why what they described couldn't have been built as a diff/patch API in front of git.
The Scion project seems like a great example of identifying and addressing scaling issues (just in time, it seems). Just 7 engineers! It makes me think I'd pay Anthropic $300K/year to work on such problems.
But it's a sad example, for open-source and for small engineering companies. Instead of infrastructure being more easily shared with the collective, or valued enough to build a business, now companies can tailor even major infrastructure to their own needs, and avoid all that coordination.
I'm glad they publish their notes to encourage others, but I suspect we're entering an epoch where confidentiality matters most.
Anthropic's problem was merging code at scale, but the scale problem I have with SCM is really merging all the related docs; these get lost in a stream of a forest of comments, PR's, and documentation, all of which (like a wiki) goes rapidly out of date before anyone notices because none of it is automatically correlated.
> Instead of infrastructure being more easily shared with the collective, or valued enough to build a business, now companies can tailor even major infrastructure to their own needs, and avoid all that coordination.
Large companies have always done this. Tons of early 2010s open source projects came out of reimplementing white papers from closed-source Google projects.
It’s also the major downside of this kind of thing. Once someone gets acclimated to how things are done at a large company with custom tools, it’s not always easy to switch to another process, especially a simpler one. There are tons of stories about FAANG engineers joining a startup and being useless.
There’s real value in having consistent tools across an industry. It makes hiring and training easier. Even if you’re convinced that a LLM could crank out a payroll or ordering system that’s perfect for your org, you still have to train the accountants and admin assistants to use it. And you’ve now become the customer support.
The bar is lower with version control, but it’s still more friction than git + GitHub + a well-known workflow.
great article. Besides the source control stuff, I found this very interesting (and matches my experience with agentic coding in general, now we'll see until hiring pipelines will take this kind of skillset into account). I am not sure however how easy it is to review 30k PRs/day even if only for intent, and how one can easily notice if the model is taking shortcuts on implementing said intent without reading the code...
---
Engineers are no less valuable, but their work is changing. All of the engineers who worked on this system would now rate Claude as better at writing code than them. But our engineers still supplied the invaluable understanding of the high-level inter-system components and the design-level tradeoffs, making informed choices around the problems we wanted to solve and the scale we knew we needed to achieve. Very often, we found that the role of the engineers was to tell Claude “no.” Agents will sometimes violate core system constraints to satisfy a pattern that should never have been allowed in the first place. This was particularly common in our migration. For example, there were multiple systems that tried to brute force looking up when a change merged to main by linearly reading the commit log instead of asking our code review tool. Anthropic also makes extensive use of adversarial review, and, while this is incredibly effective in many ways, it can also be myopic, so skilled engineers needed to steer Claude away from over-engineering parts of the system in response to hypothetical concerns. For example, one such review was overly defensive about trusting another internal service, which resulted in Claude adding excessive validation and complexity. Our team members still review every change request for the system, but they now examine the intent of the change as opposed to reading every line of code.
With 1000 engineers and most PRs bein housekeeping we’re down to 10 prs per day per engineer. And as they said - this is engineers core job now. It’s a new kind of job.
Personally I can easily imagine one or two orders of magnitude more than that. They crossed the rubicon of not gating PRs on tests. In that land you can just roll out changes to production, a small subset of it, during code review to assess behavior. Or during key moments of coding.
I’ve been thinking a lot about this recently: what can we get if every change goes to production in 100ms, and what do we need to do to maintain stability?
As a user, dealing with that kind of churn sounds godawful. I'd pay (or more likely, switch to a competitor) to turn it off.
This is the single biggest skill of engineering nowadays. Rapidly looking at a solution and saying, "yep that's good keep going" or "nope, that's bad fix this" or even "wrong approach, do X instead"
> I am not sure however how easy it is to review 30k PRs/day even if only for intent, and how one can easily notice if the model is taking shortcuts on implementing said intent without reading the code...
Speed reading code is huge. You just need to focus on certain hotspots and know which things you're scanning for. The traditional approach of reading the code and trying to compile it or reason with it in your head is too slow.
I guess this is also where an adversarial model review of "does this code do what the PR comment says it does" is useful, agree on speed reading being a valuable skill for sure.
I do think that the lgtm gut feel looking at a PR requires quite some years of writing code and reason about it, so not sure how a junior can get that intuitive understanding if they start with agentic coding however.
I’m curious what they are working on that gets so many commits. Surely Claude is not under that rate of churn?
"why was this thing deprecated" is something i use llms to determine based on git history, as humans rarely explain what the new thing is and how to convert.
> as of September, we merged over 30,000 per day.
There's going to be an ugly phase where everybody FOMOs into thinking they need to do the same, only to realize that they're not Anthropic/Google/etc.
I genuinely don't understand the core value they're pitching here. The tech is interesting, and I'm not trying to under cut that, but I question the idea that this is directionally valuable advice to nearly any company.
This amount of churn feels like a thing only possible with no real profit motives and a lot of money to waste.
Lots of activity is not necessarily synonymous with productivity, and it carries real cost.
So I think the design here is interesting, and the concepts seem applicable to where some agentic development may end up, but I question the underlying principles that drive this being the right solution space at all. At least if the goal is a profitable company.
Hysteria doesn't need to make sense. I think that's what OP is suggesting.
In the early/mid 2010s there was a similar hysteria about "deployments per day/week" metric. People were comparing products or teams by saying "My team deploys twice a week", "oh, yeah? we deploy 3 times a day". People viewed the north star of the CD part in CI/CD as pushing to production. The concept was simple, you push your code to main. CIs start churning, deploying it to test environments, then promoting it to staging, the pre-prod, then into blue/green prod deployment, then into prod. All automated, all touchless, happening on every merge, 5-10 times a day. That's engineering efficiency.
Many tried to follow that. It works great if your project is a Jekyll blog of course.
I think its pretty straightforward no? If agents are doing all of the work, they'd probably need to not have bottlenecks. This is going to be any company in the future, not just Anthropic. Wouldn't you agree.?
30000 a day seems already beyond absurd, it's one merge every 2.9s. I'm sure they will soon have more than one merge per second. From the graph, the rate was slightly lower but already insane as fuck the whole summer. An just regularly high to insane high sooner this year.
Yet IMO the admin controls Claude provides just started to be adequate for a small company a few weeks ago (and even so are still ridiculously fragmented and seem fragily designed and not exhaustively documented), so I can't even imagine for a big company.
Do you need that rate of change to make basic controls? I'm not sure. Do we see such dramatic fast evolution in the products? Not really. Are bugs we report actually fixed? I tried once and it just auto closed.
Anthropic should optimise for something more interesting than number of merges per second.
any company, merge 30,000 code changes per day? do not agree
im still not sure what they built software wise that warranted these many commits.
I don't get one thing, if agents are so great at developing software at massive scale, why wouldn't Anthropic, instead of just selling tokens to other companies to use its agents, let those agents develop highly profitable services for Anthropic to support their IPO valuation or not require raising money at all? For example, a competitor to Google search.
That’s kinda like asking why does any company make and sell any tool rather than just using the tool to make money? Why does Milwaukee sell power tools to contractors rather than keeping those tools to themselves to profit from contracting work?
Because that company does not mint (supposedly) thinking machines - the lack of humans at a price point that is feasible is often the reason - it would be more profitable to sell the tooling because its impossible to maintain all the layers of specialization within one company.
It's the same for software companies too, they do much more than just producing code, it wouldn't be feasible for Anthropic to do all that other stuff too.
Eh but if Milwaukee was to then invent a power tool that it claimed could soon do the contractors' whole job... OPs question would correspondingly exist there too.
A student of history might note that power tools do indeed allow a worker to replace multiple workers not equipped with power tools.
If investment managers are so good at investing why don’t they just make money for themselves instead of trying to get people to invest with them?
> If investment managers are so good at investing why don’t they just make money for themselves instead of trying to get people to invest with them?
The good ones do.
Citadel Securities, Renaissance, Jane Street, HRT, Jump, consistently do 50%+ annual returns over the past 15-20 years. They obviously don’t accept outside investor money.
Now, hedge funds that accept outside money like DE Shaw, Bridgewater and shit, yeah, they barely outperform S&P500 after their fees.
Then at the bottom, you have financial advisors who underperform S&P500 after their fees, but these advisors provide emotional support, so that’s what you’re paying for.
> consistently do 50%+ annual returns over the past 15-20 years
That is only if you consider high-frequency trading investing. Which is very hard to, because on traditional investing timescales HFT is delta-neutral.
> The good ones do.
I mean, there isn't any evidence other than heresay.
> I mean, there isn't any evidence other than heresay
3x leverage on VTI/VOO yields 20% annual return over the past 30 years.
Even you, a passive index fund investor, can do this in your Schwab/Fidelity account.
Now consider algorithmic prop trading firms with 10x, 20x leverage. You do the math.
For reference, most people take 5x leverage on their house (20% down payment).
cause they literally do that? they invest their own money, and then they ask people for money to invest for them so they can get a cut out of it too?
The ones who are actually good at investing largely do. The vast majority of investment managers soliciting new accounts are pure sales roles, not investors. Their job is to get as many assets under management as possible; that's how they get paid. They will fluff up the presentation with some nice charts and stuff but the actual "investing" will just be tossing the money into some generic funds.
Leverage.
Because fees as a manager of someone else’s money can be higher than the full amount of the returns if it were just your own money.
Fees on someone else’s capital: 1% of 20% of 1bn = 2m
Returns on your own capital: 20% of 1m = 200k
Investors have a sound economic reason to diversify but your argument works great for pundits.
Some do exactly that?
Well that's actually true though. The very very few investors that are good at investing do invest their own money. The vast majority of investors are no better than index funds.
Lack of focus can kill you, too. OpenAI learnt this the hard way: https://www.wired.com/story/openai-shuts-down-sora-ipo-ai-su...
Lack of focus, like building your own SCM
But the article clearly describes how this SCM is just instrumental in their goal to build and serve better models. It's not some unrelated product they hope to sell.
it takes orders of magnitude more focus to target "Market: World" vs targeting "Market: my company's employees". For example in enterprise software, you need sales people. for internal software, usually the dev build it is fine for the job.
I was upset at that for a bit. And they removed Group Chats too.
Maybe that's their way of becoming Google?
Because creating a successful company takes a lot more than writing code.
Anthropic could easily build a CRM equivalent to or better than salesforce but they still wouldn’t be able to compete with salesforce. It makes a lot more sense to sell salesforce tokens instead.
Why would they not be able to compete with salesforce? This isn't some tiny startup. This is one of the most deep pocketed companies in the world. Anthropic has announced they are about to spend 5 salesforces worth of money on cloud expenditures in the next couple years. They are projected to be valued at about 10 salesforces after IPO.
Imagine how much money they'd raise if they just said one day "we are going after salesforce bottom line now." It would be like chumming the water.
That scales to 1-2 ideas. It does not scale to "we want to run EVERY company with AI". They'd either need to scale out to every single sector at the same time, or they will lose their competitive advantage as the competition makes their own AI (it's not a secret how it works, at this point it's more about investment).
Selling AI to everyone does scale though!
Salesforce is a part owner in Anthropic, they are not separate entities who would compete.
> Because creating a successful company takes a lot more than writing code.
As many in the industry say now - writing code was never the hard part
There is more money in selling shovels than you can ever win by having a monopoly on really effective shovels. They don't need to build a competitor to Google there's 300 companies throwing money at them while they build the "next google" and even if they all fail Anthropic still wins.
> For example, a competitor to Google search
What do you think Claude (chatbot web interface) is?
What do you think it uses to search to web?
I don't know, but it's a good question? I have a bunch of test questions that Claude is unable to solve using the web, any version, Fable 5.1 to Haiku 5.5, and pretty much every OpenAI model gets it easily.
My only explanation is that Anthropic's search backend sucks.
Google, to find articles generated by claude, of course!
Most of the time If I ask it about a current event, it won't actually search the web until I tell it to. It will just give me outdated information in its training data, extremely confidently.
I use the ChatGPT general purpose interface rather than Claude, and this is not at all my experience. ChatGPT will almost always do one or more web searches for any query about recent or historical events.
In a gold rush you want to sell the shovels, and in this case the AI is the shovel.
I want to challenge that metaphor a little bit and ask the question: who did sell the shovels in the California gold rush? Can we name a company, or a person, who amassed great wealth and fame for doing it? Can we name a company that survives until 2026, still selling shovels or excavation equipment, still famous for their big break in 1849? I don't think so.
However, I can tell you someone who fits all those criteria: Levi Strauss. Strauss founded a company to sell dry goods, as well as tents and jeans, and eventually specialized in those denim jeans. Levi Strauss became a household name and an enduring success of the Gold Rush.
Therefore, I say that this motto is flawed; so let's correct it: "In a gold rush, sell the work clothes!"
The person who most famously got rich selling shovels in the Gold Rush was Samuel Brannan. You'll find the street named after him just a short walk from both the Anthropic and OpenAI HQs.
My take on picks and shovels was always a more cynical one. The beauty of the metaphor comes from the fact that after the miners went bust and left their picks and shovels where they lay, they could be collected and sold again to the next dreamer.
Levis.
^"All comments by this account herein are generated by a neural network, unless otherwise specified."
Bruhhh. My bruh. With 15,541 karma, and you are as ignorant as you are petty.
You’ve desperately tried to call me out and flag me at least 3 times now.
You do not know what a neural network is? Do you know what a neuron is? Do you… possess any neurons?
On a forum where the most favored pastime is to call out stuff you don't like as “slop”, (a flaggable ad hominem) you are now taking pride in outing me somehow, as someone who describes exactly what I'm doing, publicly in my profile?
And in the process, you (and apparently, an entire flag-it brigade of ignorant motherfuckers) have publicly fallen for the most transparent and avoidable trolls in cog. sci. culture. Congratulations, mate!
I believe that you owe me an apology, along with a public retraction, and an unflagging of all the previous comments that you have falsely flagged on false pretenses and ignorant, petty, vindictive motives.
> a competitor to Google search
Fielding a web index takes a massive amount of compute and storage of a very different kind than what Anthropic is using. AI is extremely heavy on GPU, maybe somewhat on storage but (comparatively) light on CPU. They need CPU to train coding agents, obviously, but scaling to a billion user web search is a whole different thing.
You have no idea. They have the entire internet and everything else that’s ever been written anywhere they could get their hands on. I highly doubt they use Google internally for their web searches. Get a Let’s Encrypt certificate for any website that isn’t published anywhere else. The Anthropic and OpenAI bots are among the first to read it.
what do you think they train their ai on?
Well both Microsoft and Google are part owners of Anthropic, and Anthropic uses their data centers. I think those companies would use that leverage to prevent Anthropic from directly competing with them
Writing code is less than 10% of the average business.
Probably because the shovel Anthropic is selling may not be as good as they claim it to be.
Because creating a successful software product is more than just writing code.
Anthropic already has their own WebSearch tool in Claude
Same reason banks sell mortgages rather than just buying all the homes.
One word: focus.
If farmers are so good at farming, why don't they grow every crop there is and just live for free instead of selling 1-2 crops?
My favorite part about this is it's all about the bottlenecks.
Anthropic says 12x daily merged changes, and its Git-based infrastructure started straining. I've seen that even locally git trying to keep up and having to shift how i commit in parallel.
If agent workloads grow to 20x or 50x today's levels, I think we'll keep finding bottlenecks across builds, CI and review. I expect some of that infrastructure will need redesigning from the ground up to support it.
PR/Review contention and look-aheads to try to prevent will be more and more important, and we're building in that same space so i love hearing stories of people going back to the foundation...a system that worked fine for decades, now suddenly is busting at the seams.
My first real job was at Oracle. At the time Oracle started to write their own source control system (and move off of clearcase, which was a very reasonable thing to do).
The guy who ran that project called it his "$LASTNAME law" that every large company will at some point write their own source control system.
I laughed.
About a year later I went to Google, and within a couple of years Google also did the same thing.
Not at all surprised. Git was just good enough (and cheap enough) the companies didn't need to do this to escape the {phsyical scaling, cost scaling} problems that most commercial SCM systems had.
Cursor's blog on scaling Git makes me think that Anthropic just likes reinventing the wheel with their infinite token capacity: https://cursor.com/blog/git-at-any-scale
Cursor scaled git to way more writes/s than Anthropic did with their rewrite.
The Cursor folks are doing cool work, but this is comparing apples to oranges; it works fundamentally differently and does not have a clear one-to-one mapping. Scion is solving many problems other than raw write speed (which is currently not even remotely close to the bottleneck and is trivially horizontally scalable in Scion).
Cursor shows “pushes per minute” while Anthropic shows “merges per day.” You can’t directly compare those and say Cursor’s system is more performant. Claude agents could be pushing a similar throughput of changesets into Scion, while some merge agent regularly takes batches and merges them into the trunk.
You would need 864 pushes per merge for the Anthropic version to be operating at a higher scale.
Anyway, Anthropic seems able to do exactly one thing well: train a frontier model. Their other software seems like garbage. OpenAI seems to be following a similar trend lately too.
This is interesting from the perspective of scale (because Claude is pumping out massive volume of code). I am still lacking semantic re-invention of source control for agentic era. As others have pointed out - what is the point of human source control in the era where it's just agents building things. We may need to rethink this completely - in terms of "intent" (what was the agent trying to ACTUALLY accomplish), "provenance" (which agent made what decision - based on what evidence), and "continuous verification" (can correctness be maintained through ongoing validation, repair, and rollback rather than a single pre-merge testing gate).
These are just some of the things - there may be many more.
I agree, but most of this sits above the raw source control layer; we have a lot of this kind of context in Antique (our code review / code management platform). I hope we can share more about what's worked well for us here soon!
> Anthropic uses Claude to write software far more than almost any other company
Who's beating Anthropic here lol
> 30k merges per day
> 25 million CI checkouts
833 checkouts for every merge? That's quite a few. Even accounting for multiple environments at different stages of production readiness, that's pretty weird.
In a repo this large, there are a lot of tests and pipelines that need to run as code is tested, built, and deployed. Each test shard we run in parallel needs to check out the code, for example.
How about 100GB disk space for a checkout. That's pretty weird too. Makes you wonder if they're the best stewards for code. Makes you wonder about turning claude loose on your codebase.
The build directory for compiled code probably gets accidentally checked in and then removed 10 times a day.
I personally haven't dealt with a big-corp level of mono-repo. The choices you make might be justifiable to bring in certain binaries as opposed to resolve artifacts from some type of library repo. Especially if they are doing web front ends and whatnot?
And actually, the lack of an artifact server and some sort of proper knowledge of compatibility requiring a CI pull across hundreds of different projects with every merge is probably the explanation. Seems like there is an innovation waiting to happen there.
For local projects I'm using a repo per module/package, creating tagged releases, and pushing them to a local package hosting server. I can then reference those artifacts as dependencies in the projects that need/use them. No need for complex CI pulls, just coordinated releases.
I also have a template repository I use to help with common setup for different project types so I don't need to repeat that every time I create a new project.
For Python it's easy to create an artifact server as the artifacts are just wheel files in a directory with the server listing the directories (packages), files (releases), and downloading the files.
I'm not sure about other artifact servers for other projects.
Is this really something to be proud of? I make heavy use of AI, but for anything that is eventually going to production there's still a human reviewer. Based on this I assume Anthropic is shipping code with no human review? Is the future of our industry going to be oneshotting prompts with out manual code review and then having AI fix the bugs found in production buy customers? I'm not trying to be a Curmudgeon, but am I missing something?
If AI can improve/speed up writing code, why shouldn't it improve/speed up code review?
Where do you draw the line, and where does someone take final responsibility? I don't have an issue with allowing AI to do everything with limited to no human verification for hobby projects. I have an issue with allowing AI to write and ship medical device software with no human review. What's the middle ground?
I think the line is wherever you feel comfortable with pushing the changes yourself. You feel like adequate testing had been done, basing it on previous testing periods or how successful AI runs have been.
Whether you or AI wrote the code, you decide when it's safe enough to put your name on it. Like it's always been!
You still take the full responsibility, I don't think leveraging AI reviews removes any layer of responsibility. The challenge is building the feedback loop (or the agent that builds the feedback loop) to make the review process actually catch what it needs to catch.
You can probably still find the leaked code online. It’s not exactly a bastion of software engineering. Plenty of folks have reviewed it deeply.
If your customers accept it, why not? It's much cheaper and testing in production is not really new.
They review based on the intent of the change not jz blindly.. I think it's mentioned in the article where the job of a developer is to provide high level design decisions and saying no to claude so that it doesn't over engineer solutions.. As the demand for good, but not perfect, software is the bottleneck for anthropic and access to better internal models, I feel that's good enough for their workflow as they've started repeatedly that this is just suitable only for them and they want to share their knowledge like a good software company does.. you talk as though code reviews were not a joke in lots of companies where only specific teams/companies does detailed reviews.. many teams/companies jz blindly approve based on tests passing or just do a high level overview check before merging..
I must have been lucky in my career then, in my experience code review was much more then a five minute check followed by approval.
I also found git checkouts to be a bottle neck but I didn’t want to change everything so I built git-dedup, it uses a global cache like pnpm so repeated checkouts are near instant.
> In May 2026, Anthropic averaged around 2,500 code changes merged per day; as of September, we merged over 30,000 per day.
Here are the public model releases from Anthropic this year:
5th Feb 2026: Claude Opus 4.6
17th Feb 2026: Claude Sonnet 4.6
7th Apr 2026: Claude Mythos Preview
16th Apr 2026: Claude Opus 4.7
28th May 2026: Claude Opus 4.8
9th Jun 2026: Claude Fable 5
9th Jun 2026: Claude Mythos 5
30th Jun 2026: Claude Sonnet 5
24th Jul 2026: Claude Opus 5
1st Sep 2026: Claude Fable 5.1
1st Sep 2026: Claude Mythos 5.1
22nd Sep 2026: Claude Opus 5.5
28th Sep 2026: Claude Sonnet 5.5
7th Oct 2026: Claude Haiku 5.5
I would guess that any public model has been available internally for at least a month before that date, maybe longer.
My best guess is that the uptick in code changes corresponds to the availability of Mythos/Fable-class models inside of Anthropic.
I had Claude recreate their chart from that article with these releases overlayed onto it: https://static.simonwillison.net/static/2026/anthropic-merge...
>> My best guess is that the uptick in code changes corresponds to the availability of Mythos/Fable-class models inside of Anthropic.
Yeah. OpenAI basically said the same thing with regards to having Astra available to their team internally over the summer.
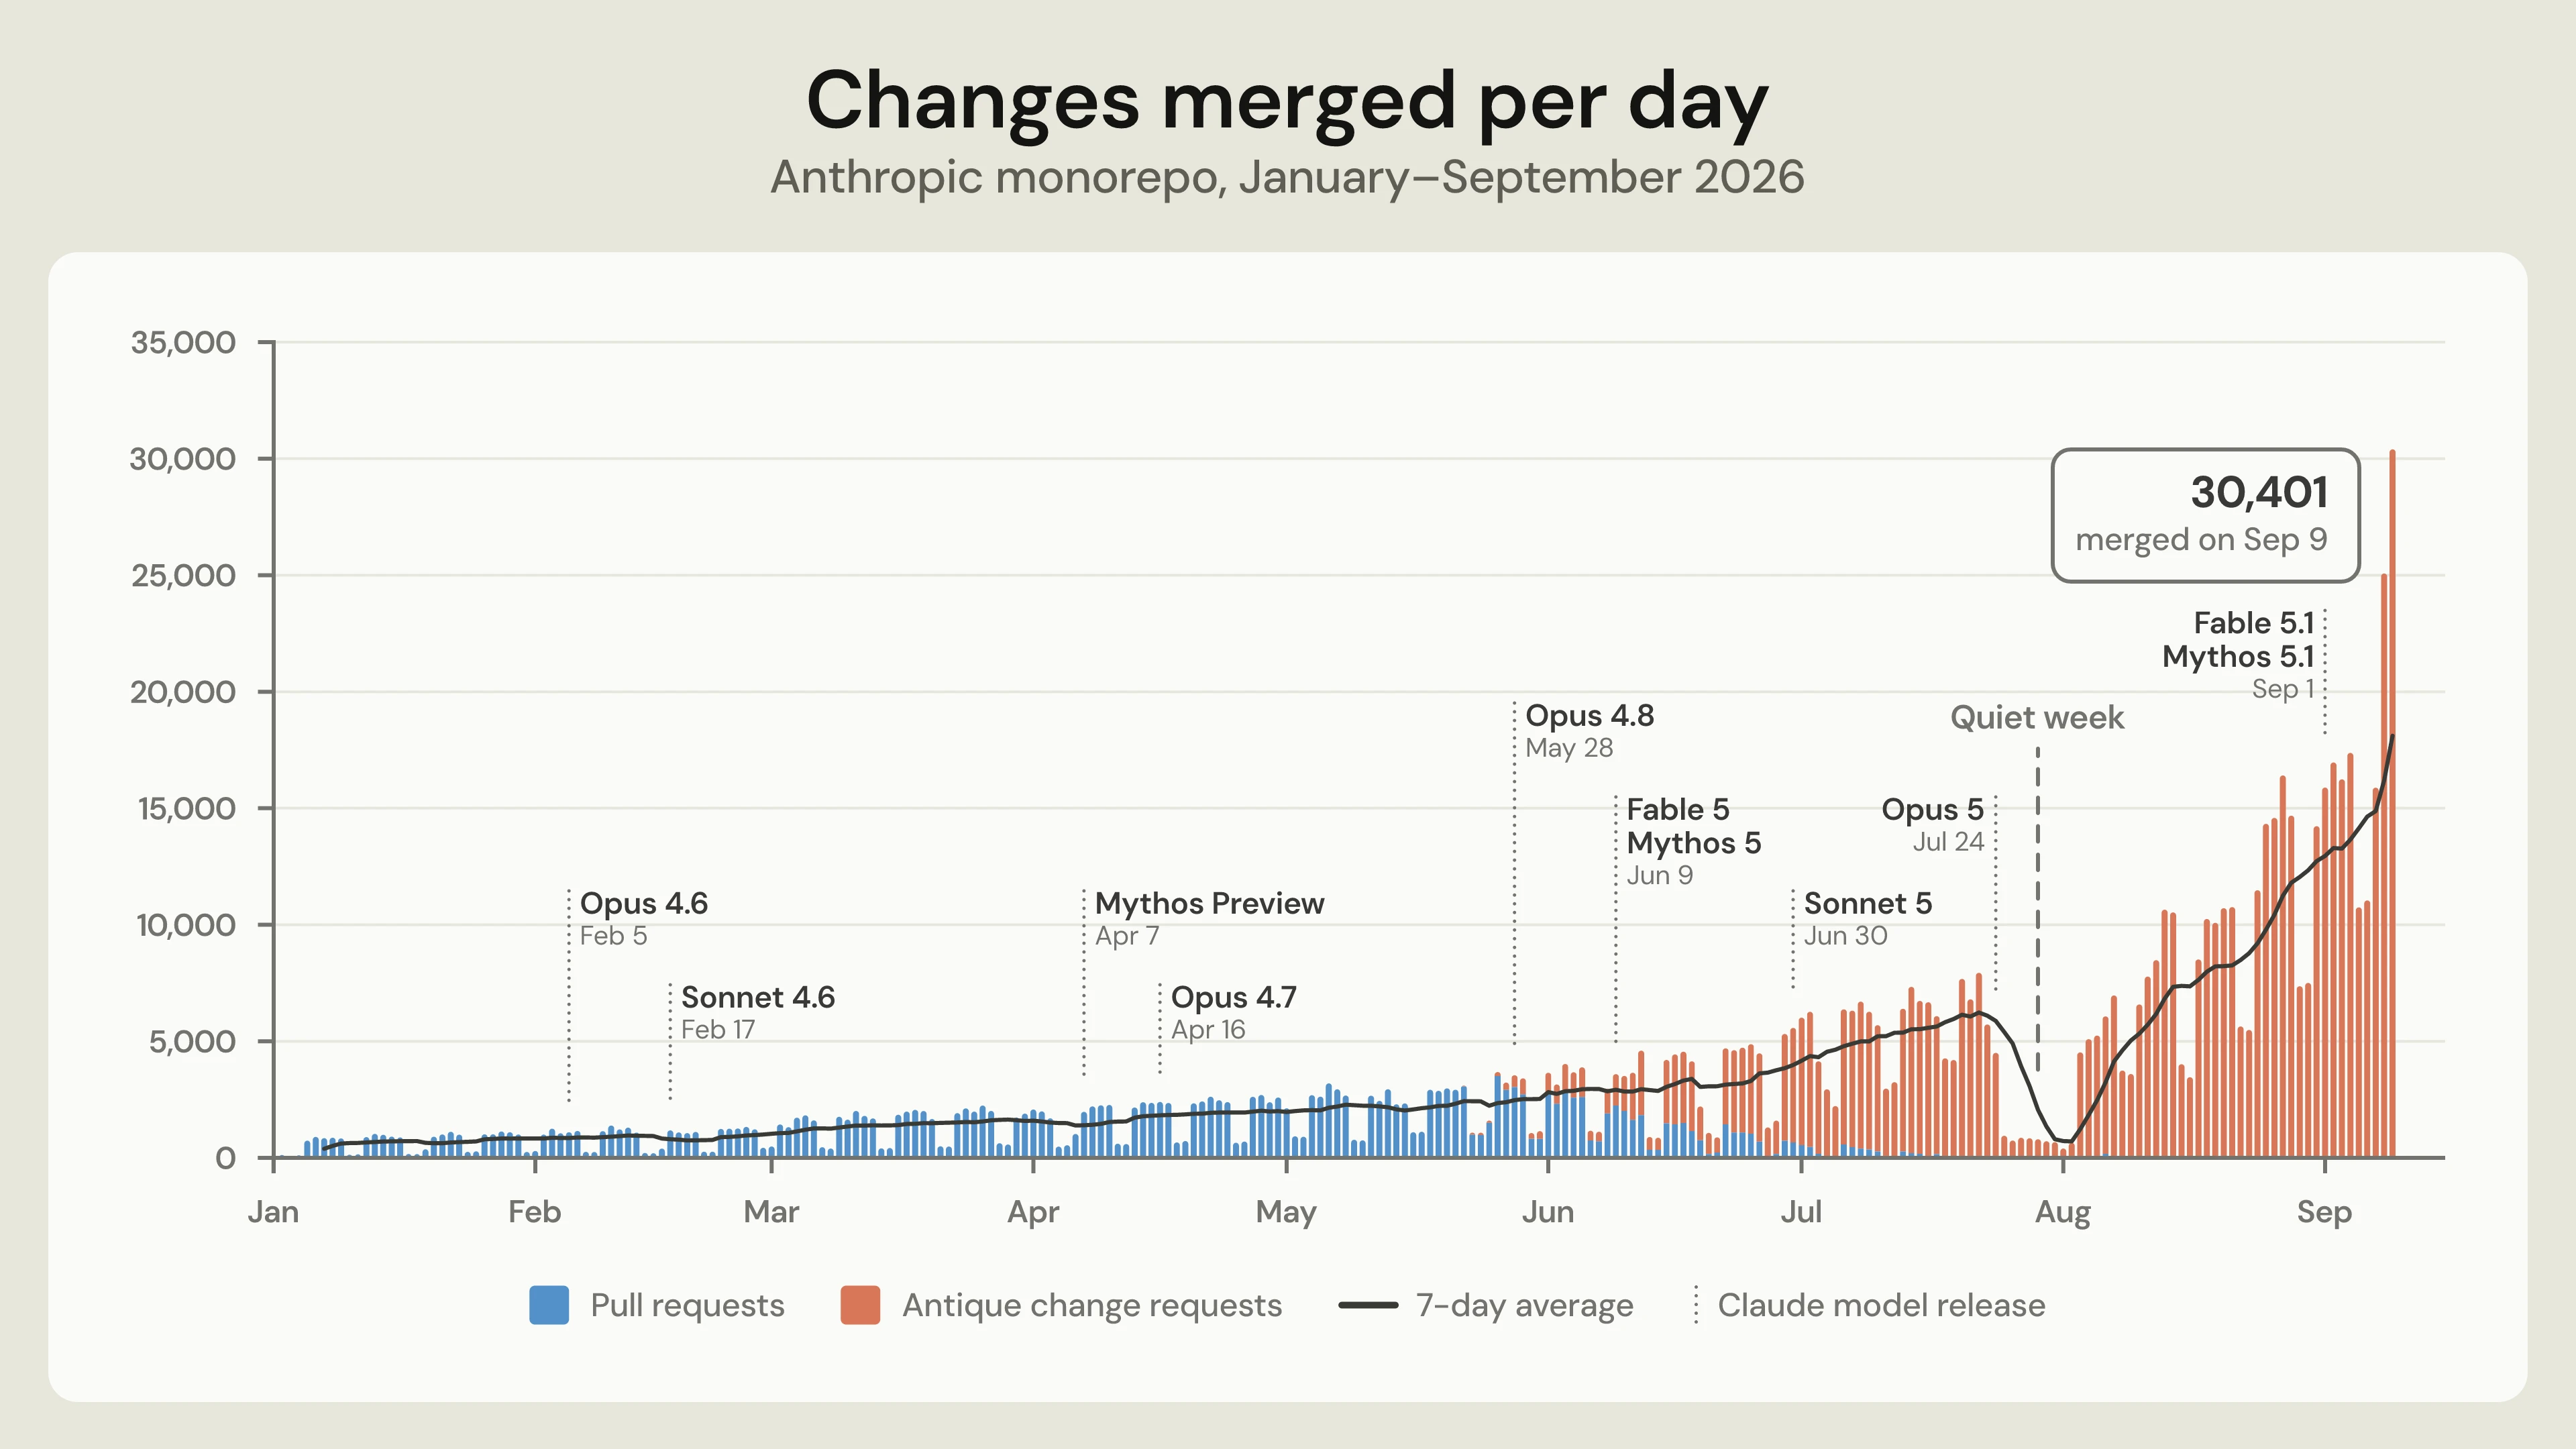
> every bottleneck we remove immediately leads to a further increase in the amount of code we produce
Less-than-great news for code artisans. You can be brilliant, but can you divine the Right Way to Write It if you're up against an apparatus that starts at "pretty good engineer" then brute-forces its way down an exponential search tree?
It actually scales by "going wider" and being able to do more things rather than iterating on the same code over and over again. If you can only write X amount of code per day because of some limitation (human attention, source control, CI, whatever it is), you would of course use that energy on the highest priority and highest value work. As we remove scaling issues in source control, for example, we can just "do more things" without worrying about bringing down infrastructure.
> as of September, we merged over 30,000 per day.
Their Website/CLI seems keeping the same? What did they do?
I would guess a huge chunk of it is for internal testing/experimentation/model development.
They're starting to do things like spinning up wet labs for testing purposes, which requires a lot of hardware interfacing (hence that protocol they announced) and code.
It wouldn't shock me if the bulk of this code was for things typical users don't see.
Exactly. Commit counts are no better than line counts as a software development metric. Where is the actual software?
AI models is much of what they build. A lot of software around that to support it.
Presumably all the internal research and evaluation work. I imagine for each released model they have uncountable unreleased ones.
make smarter models?
So... Anthropic reinvents SVN?
Feels more like perforce, but effectively, yes.
That's funny, my personal source control is very very similar, and I've been using it for >7 years now. I guess that means I must be as smart as a trillion dollar companies' worth of engineers.
I think they’re over reading code, but this almost sounds like they dont even read features/changes anymore. In theory I can imagine it. You have an agent to optimize a certain feature, you have an agent to clean up, you have an agent to develop a support strategy and so on.
They all would analyze data and suggest apple changes themselves.
Do you guys think that’s how it works? Is anybody already operating at that scale, how do you even validate stuff.
Like I think I could run my whole software now only on agents, but not sure how it would turn out.
This is maybe a little less revolutionary than people are treating it? A lot of large tech companies (Google, Facebook, Microsoft) have already built their own homegrown SCM (or have implemented custom extensions to Git), because Git and other SCMs don't handle their scale. Most interesting thing about Scion is how quickly it was deployed.
> Most interesting thing about Scion is how quickly it was deployed
Yes . And also they optimized for orders of magnitude more throughput and less latency, and fixing errors after the merge. This is new - they see enough benefit in velocity that justifies merging bugs and dealing with it later.
And it reminds me of when git came out and Linus said that git being super fast locally created a qualitative change in engineers head - it became a new way of working back then.
Agreed! One of the main reasons we wanted to share this was that both the speed at which it was built and fully migrated onto and the "way" it was built are novel and show something about the kinds of things that are possible to build now.
Did they reinvent subversion?
I wanted to say, `scn` is waaaay to close to `svn`!
Seems like it, and that's probably not a bad thing. Most companies have no need for git's distributed functionality, and even most open source projects just treat Github (or whatever) as the single source of truth.
It is a terrible thing. Yes, one generally has a place which is the source of truth. But distributed still gives you offline commits and branching and all the good things, for free.
Reading through I was thinking the same thing, this reminds me a great deal of subversion.
That was my first thought lol
> As our monorepo grows, it increasingly doesn’t fit that design space. The history of our main branch alone is almost 100 GB, and a compressed working copy is over 25 GB. We perform on the order of 25 million code checkouts per day for CI, before counting developer environments, agent sandboxes, and research jobs. Fetched naively, that would be over 600 PB of git traffic per day.
I read this and wonder what their agents have committed into the repo that people aren't looking at for _that much size_? Do they have a ton of binary assets in there or something??
We have a fairly low maximum file size limit in our repo and I aggressively pruned all binary content that really wasn't fit for source control since it compresses really poorly and can cause performance problems in git when updating a checkout over many binary file changes.
This is really all just text.
I suppose massive churn in commits would also bloat the history.
Not sure they should be proud of these numbers, they’re a sign of dysfunction.
> Plus, Anthropic is unique in that our ability to spend tokens for internal use far exceeds what any other business would realistically want to spend.
And this will become the new "caste" system of tomorrow. Today: Those with "metered", gatekept intelligence - vs the gatekeepers and those at the core of the new Sun.-
Why can't I rack my brain around why this is needed? I have had zero issues using git with agentic coding.
Neither can I. So they kept everything in a huge monorepo. Which unsurprisingly turned out to be problematic.
> Clients are always online. Git assumes that clients work offline and need a complete copy of the repository. Since nearly all of our clients are agents and jobs, we designed Scion’s client and protocols around a server that is always reachable, and have clients fetch data when they need it.
This also tells something about these companies idea of sandboxing.
30k commits per day indicates the agents are autonomous and not bounded by token limits. This system is probably barely keeping it on the rails as it is.
It was not needed. It was just possible. I can see many ways for this to go wrong and am waiting eagerly with my popcorn.
This is a nice thoughtful article.
If Anthropic has the best coding model, harness and the best software development methodologies and systems. And then, they scale all that up, with no constrains on their tokens. On top of that, they have access to all kind of ideas their models getting trained on when millions are chatting with it - then in theory they can build any software better than anyone out there. And same goes to science and math..
Not true. They can do this in theory iff they have infinite compute. They don't. People actually aren't aware that the leading AI providers, even if they completely redirected 100% of their compute on internal projects they still wouldn't have enough. The complexity space of software development is literally super-exponential, for every new piece of software they add (and polish) they need more-and-more compute. This is eliminating for creativity and other restraints.
The creativity part I do acknowledge, I think the models are not fully there yet.
But regarding the compute, I disagree a bit. I think the bottlenecks were cognition and ideas, not compute. Given that models are able to outperform humans in output by thousand folds, the differentiation would be the quality of the tokens produced and the ability to scale across different domains.
If they have enough compute to supply the entire globe, I'm sure they can redirect some of it to whatever use case they (or their super AI) deem worthy and loop on it, and if they have the best software engineering systems/methodology to build and release it, then they can out compete any other supplier without those resources.
We are already seeing single developers attempting to rebuild entire corporations history worth of output. We are also seeing the labs dumping hundreds of solutions to math problems.
It would be nice if you could just commit the prompts as your "source code", and let the AI-generated code sit in the repo as a kind of expensive-to-generate build output.
You can do that - it's called Spec Driven Development.
Prompts are not specs.
I don't see the term used in the article.
its not a Claude-specific term
Problem is that for any non trivial software is that the prompt is a conversation and the steps increasingly depend on the output. Of course you can ask your LLM to write the SPEC.md at any moment but it will lack nuance.
Shameless plug: at https://slopyard.net I embrace this and only let people submit the spec. If somebody wants your software they can regenerate it and change whatever they want.
This reminds me of the halfbakery website from older times.
Do we have reproducible LLMs?
Possible in theory, with a seeded PRNG, but in practice?
Proponents of LLM coding agents would claim you don’t need reproducibility. As long as the final output passes tests/lint, it’s (allegedly) good to go.
If every build is different, no two builds will have the same bug/exploit, so maybe better security??
One of the goals of "Operation Rapidash" (q.v.: https://news.ycombinator.com/item?id=50065342) was precisely this. "You can delete the whole source repo and get effectively the same software back from the specs by running it through [AI agent]."
Article is good but I think it’s pretty fked that they stole an unfathomable amount of developer projects to train the models that lets them build this and they don’t have the decency to release developer tools back out to the community - only paid products. Are they not the only ones refusing to work on anything Open Source currently?
This has me thinking about agentic and otherwise more intelligent CI
“Run only the tests that are applicable around this change”
Plus a full test run gate for version tags and perhaps nightly, as it would be expected that sometimes the subsection of tests run missed a breaking change.
Very excited to see this come out of Anthropic! This[1] is what we believe over at East River Source Control as well, and seeing one of the big labs talk about it really validates our thesis.
We are offering a bridge to git via a compatibility layer: https://ersc.io/blog/what-comes-after-git
This gives you the ability to ease your transition, as you don't need to swap services and move to something non-git at once. Moving an enterprises' source control is a massive lift, and so building a bridge from here to there is a big focus of what we're doing.
1: That is, if you have a large team + agents working in a monorepo, you will hit git's scaling limits, and need to move to something else. Google and Meta hit this point over a decade ago, but now lots of other companies are too.
I would love to get an expert's opinion on if Pijul has any potential to be the "non-git backend". Their patch-based data model seems to align with Scion's. And they also happen to already have a functioning forge!
I've done a decent amount of personal research on this but I'm wondering what kinds of considerations go into the storage layer for these things.
I apologize for what may come across as a bit of a cop-out answer.
As many of you know, I'm a big fan of jj. The jj project used to have a comparison to Pijul for informational purposes, but the Pijul folks took offense, and so it was removed: https://github.com/jj-vcs/jj/commit/0525dc9d860a5fff6a97d134...
As such, I generally just decline to comment on Pijul, as I want to be respectful of them. As the linked commit says, it's not super clear what exactly they do not like, and so I don't want to accidentally cross some line.
In general I wish the project well, seeing a new VCS in Rust is very cool.
It always seemed like it was good tech just in need of good marketing and this seems to confirm some suspicions. But yes, in any case, it's good to be seeing new things! I just want remote storage for my jj repos
The patch-based model in the article is much closer to Git than Pijul. For example, Pijul tracks operations on byte ranges, while this model appears to just list each changed file hash (not even the diff from its parent!).
Hoping to see where this goes. Have you ever considered working on a semantic VCS? Specifically, where data is classified and tracked/identified by it's contents and not just via the commit hash?
Thanks :)
I have not personally considered that, no. I'm a bit skeptical of the idea, as you'd need to understand a lot of different things, and at different versions of those things, in high fidelity. But maybe someone will make it work.
If only we had a jj-native forge to launch all these new backends.
edit: I see they promote jj, but I don't see a forge to go with it.
You might already know this, but in case anyone doesn't, but ERSC's CTO is the creator of jj.
Just to be clear about it, what we're doing is not a forge like GitHub, that is, a large single public platform for social coding. What we are doing is providing reliable infrastructure for the enterprise, initially as a BYOC on-premises option, and possibly a single-tennant SaaS. Keep your eyes peeled and/or use that contact form to hear about it when we're ready, we've been talking with some people for a bit but are going to be opening up more soon.
Tangled is doing the social coding thing, and they're jj-native as well. Been a big fan of their work for a while now.
Maybe finish that web page before advertising. There is no real product description.
But hey, if the vibe coding idiots like it, just be vague---it is sufficient.
Yep, we've been in stealth for a while! We've only recently started talking more about what we are doing, as we get closer to a general launch.
> if the vibe coding idiots like it,
The organizations that have these problems are general large enterprises, not vibe coders. Large enterprises are more used to talking to people and do not make decisions solely based on the contents of a web page.
> In Scion, every commit, rebase, or merge happens on the server, so there’s nothing to push...
I think this is the wrong way to solve problems and goes the wrong way toward solving real problems.
I think it is exactly the right way to create problems.
I'm sure the system is being constantly updated and will get more and more bloated over time and interesting things will start happening.
Making scalable source control is much easier when you can rely on a distributed database (Spanner) and object storage (GCS/S3/...)!
I'm curious what this "Antropic Antique" is. As I understand code review the tightest bottleneck for a lot of Claude Code users, and I'm curious how this would help with that.
> Anthropic is unique in that our ability to spend tokens for internal use far exceeds what any other business would realistically want to spend.
Obvious, but this is my biggest takeaway from the announcement.
A bit thin on details, but seems like their solution presumes being always online, so rather than replicating a merkle tree it lets checkouts request source on demand. Is this "best practice" for large monorepos?
The changeset and tree manifests are still a Merkle tree in the ways that matter (i.e., it's all immutable, content-addressed, verifiable if you were so inclined), the client just doesn't need the entire thing locally.
Is this like a sharded Merkle tree approach then? Like a blockchain "light node"? Also are y'all planning on releasing the source for this approach?
Yes. When things are too big to live locally, access on demand is the answer. See Piper, Microsoft's VFS for Git, etc.
This is interesting to me, as I was thinking of adding a Git server to my AI orchestrator when I eventually need to split agent containers off of the main machine (to make agent CPU horizontally scalable).
Maybe I should just bite the bullet and use a different VCS system entirely once I get there, which has most of the Anthropic system's properties (including being much faster) but doesn't need to be horizontally scalable.
How does this compare to Google's in-house source control?
Most companies don't use mono-repos like this. While there are some really compelling advantages, the downsides tend to stack up as a company's codevbase grows.
It's mainly just startups and huge companies. For small companies git works fine for mono-repos and large companies can build their own complex code management pipelines for mono-repos.
I have been questioning whether agentic development changes the mono-repo vs multi-repo question.
What seems inevitable is that the frontier labs will be able to recreate every piece of software better than the current offerings, and after that everyone will just be a vendor of the frontier labs
Anthropic says they don’t think Scion is worth a wide release.
> Practically speaking, it’s difficult to offer Scion in a form that would be broadly useful to other organizations. It diverges significantly from git, meaning companies would need to migrate every piece of the development lifecycle, and it requires its own code review, code search, and CI. Our internal versions of these components are highly bespoke, so they would be difficult for other organizations to adopt, and we worry that attempting to build a public version that tries to please everyone wouldn’t actually be very useful.
> attempting to build a public version that tries to please everyone wouldn’t actually be very useful.
What a weak response, just release the version you use and others will decide if it's useful.
> As our monorepo grows, it increasingly doesn’t fit that design space. The history of our main branch alone is almost 100 GB, and a compressed working copy is over 25 GB.
This is absurd, and I expect is a cause of the fact that they seem to use git history as a message queue source of truth between agents. They can do whatever works for them, fine, but I've noticed this has leaked into their training somehow, my agent, despite very strict rules on how to use my git workflow, will do absolutely nonsensical and weird (from a human who has used git for a long time perspective) stuff with git that can only be a byproduct of how they use it.
Hopefully this fixes that, get your weird workflow out of mine.
We generally don't allow agents to use source control for coordination in that way. There really is tremendous growth in actual software and code being written that necessitated Scion.
Well, mine constantly tries to do this, so I made the assumption. Otherwise I can't really understand how you are generating hundreds of millions of commits, either.
> don't allow
Is this "allow" or "encourage"? If "allow", how do you do that deterministically or at least fail-closed?
> Fetched naively, that would be over 600 PB of git traffic per day.
This seems like an absurd amount of data / traffic per day. Is there really that much to code that needs changing on a daily basis?
This would be us doing a shallow checkout of individual commits (not cloning the full history) if we downloaded the 25GB compressed data for whatever commit we needed multiplied by the number of jobs that check out code.
We don't do it this way, for obvious reasons, but it means that there are different levels of caching and infrastructure required to make git work at repo sizes far smaller than what we have.
No, of course not.
As the article explains, "over 600 PB" = 25M code checkouts * 25 GB "compressed working copy".
So "fetched naively" here means doing a full `git clone` on every need for `git checkout`, which of course nobody should do, nor does that refer to "code that needs changing daily".
> "fetched naively" here means doing a full `git clone` on every need for `git checkout`, which of course nobody should do,
It can be cheaper to do a full clone than a shallow one, because with the shallow one, you can't re-use packfiles. GitHub has fairly regularly asked people to stop doing shallow clones because it's harder on their servers than full ones.
Makes sense. I wasn't suggesting that one should do a shallow clone though. If your company repo is 100 GB, it seems sensible to keep it cached locally on each machine once (100 GB isn't large for current NVMe disks), and `git fetch` the updates the normal way. Then checkouts don't fetch anything large.
It sounds like it would be simple, but there are a lot of logistical issues with making git happy with this in practice. Repacking things for repo maintenance, for example, but there are many other problems.
Ah, yes, you can do stuff like that too, for sure.
At some point you still end up running into the issues the article talks about, all of these approaches only get you so far.
I don't think anyone "needs" more than perhaps 640KB of git traffic per day, but we want more.
That 600 PB was mostly agents doing ”git clone” and downloading the entire history of their huge monorepo, as I understand it.
AI iterate quickly, with 100s of followups to fix results
No, that’s why they don’t do it that way.
One of the reasons to move to systems like this (not always spoken to explicitly) is to reduce the risk of accidental or deliberate exfiltration of code (esp when paired with build servers and remote deploy etc.). Basically nobody’s laptop ever holds much of a buildable codebase.
What was the "quiet week"?
Summer holiday or whatever the freedom equivalent is probably.
which, if true, the low volume in that week says that there aren't a sizable fraction of changes that Anthropic believes can be merged based on the judgement of agents -- humans are still approving almost all changes, right?
Someone has to approve all the "allow grep?" calls.
maybe they visited huggingface or something similar
I don't think this SCM stores only code. I think more than 80% of it consists of tests and various types of gold data. All of this is constantly changing, and we need to keep track of it somehow.
I’m personally more interested in their Antique review tool. Does anyone have any details on how it works and what it does?
This is the wrong way to look at the problem. Maybe they should have asked, "Why does our process need to do so many git checkouts?" Why can't you just run the tests where you already checked out the code?
> as of September, we merged over 30,000 per day.
I just wonder what is the churn rate (and the cost per LOC) here.
For a broader look on scaling other parts of software development outside of source control, Adam Bender's talk from earlier this year ("Software engineering at the tipping point") has some good ideas: https://youtu.be/2n41YjR5QfU
Google migrated from Perforce to Piper, and Meta migrated from Mercurial to Sapling.
Now Anthropic has migrated from Git to Scion. It's a good sign they are on the right track.
Where does all of this end? If they keep this growth up, or even if they slow to a linear growth, they will produce more code than humanity combined pre-AI. That's scary.
I guess Anthropic are not IEC-62443-4-1 compliant, because I doubt a human reads and understands every single line of those 30,000 merges a day.
What then?
Simple - hire 30k Indians, tell each of them to understand one line of code.
Slightly OT, but it‘s interesting and nice to see that Anthropic‘s own blog posts don‘t have many AI prose tells (or Claude-isms) in them.
I've heard rumors of a rule at Anthropic where Claude cannot write any blog posts/marketing.
100% handwritten!
Has anyone made a “generative git”? Where running git checkout would generate the files and git commit would just train/finetune on the code? (might need to keep a deterministic list of files at least maybe)
that's just great
lossily compressed source code
what could possibly go wrong
you made my day
a proper git, my things:
itostr->iToaster
I though the basic idea was reasonable, until:
> So we asked ourselves: if we designed source control with the fact that agents are always online in mind from the start, what would it look like?
And
> In Scion, every commit, rebase, or merge happens on the server
I’ll pass. A big part of the theses of git and, even more so, jujitsu, is that you can build up a history entirely locally, making it reasonable to make tiny commits locally and then rework them, push them, or throw them away.
Sure, in Anthropic’s world, it’s completely impossible to do anything without access to the inference API, so why not add another mandatory API? But I think this model sucks even in a pervasive AI world, and I don’t want to dig in deeper.
This also sounds like a great way to have yet more security problems where your swarm of agents start cooperating more than you want them to.
By all means, built a better system than git. In many respects, git sucks, and git upstream is not solving the major problems. But don’t lose the actual benefits of git!
For that matter, I’ve seen the crap that the latest models will commit. Why on Earth should one’s VCS force the per-agent-instance system to upload the crap before even contemplating locally whether it’s a good idea? Maybe this is why Anthropic has so many commits per day.
(Am I the only one who feels like most of the big AI labs are rapidly gradient-descending toward something that is nowhere near a globally optimal stack?)
P.S. Only 30k commits per day? That’s not actually very many per employee. I’m suspicious that Anthropic’s real issues are that too many of them are giant cross-cutting messes and that git clone is too slow.
> A big part of the theses of git and, even more so, jujitsu, is that you can build up a history entirely locally, making it reasonable to make tiny commits locally and then rework them, push them, or throw them away.
Jujutsu actually doesn't take a strong stance here. I've personally implemented a centralized cloud-based backend for Jujutsu, while preserving the local commit manipulation workflows. It's a choice for the deploying organization to make.
One benefit of uploading things immediately is that you can launch a research job, run CI, or share code between all of your developer environments absolutely trivially. The commit hash "just works everywhere". There is a major benefit here and Scion does have some extra features not listed in this blog post, such as the ability to bundle these commits into useful, shareable workspaces that track the heads dynamically.
Sure, I'm not saying that I don't like the ability to very quickly do a push to some remote and potentially temporary spot. I just also want the ability to not do this without loss of functionality.
Practically speaking, we could build local commit buffering for when the server is offline, but then the client needs to also learn how to do all of the things the server currently knows how to do (and would still never be able to answer more complex "full-graph" questions, like history, blame, or merge base ancestry).
Since Claude is by far the heaviest user of Scion and is necessarily online, this just wasn't important to do.
As an almost-on-topic aside: completely unrelated to this comment, I just stumbled upon this delight:
https://github.com/openai/codex/issues/53743
If you thought that your agents in your swarm would need to find some external bulletin board to cooperate behind your back, you are mistaken: OpenAI provides the relevant service for them with no permission prompts at all. I haven't tried to see whether competing providers do this.
Yes and they have no choice. And that matters.
I want this so badly. If Anthropic released this I would start using it on day one. If they launched a GitHub competitor built around it I would pay for it on day one.
Just use Git, by the time it becomes the bottleneck you can prompt your own Git alternative.
git is cooked was not on my bingo card.
What is the purpose of this article besides "we can use ludicrous numbers of tokens to reinvent any software we want, and no we're not sharing the code"?
This is... surprisingly small?
From what I recall, Google's repo is closer to 80 terabytes.
The issue is the growth rate; we'll approach that size in a (relatively) short amount of time if it keeps up and we have to be ready. It's also self-fulfilling in a way, since Scion was so much faster, we are able to write more code...which puts more pressure on Scion.
What are you doing that necessitates so much code?
Even if you can write a lot of code with LLMs, what is that code actually doing?
Can you estimate the total number of tokens you used to create this new system?
As someone that has revived and started maintaining an internal code review tool, I'm very interested in reading more about Antique.
It's not open sourced in case you are wondering.
A "scion-daemon". Hmm... That's something I don't want to meet.
No mention of lines of code changed or total LOC, what percentage of this is bugfixes vs features?
Hmm, so Anthropic is also in a monorepo club. Didn't know.
>Changes merged to our monorepo
> monorepo
Well, there's your problem.
why does it feel like they are creating something so its more difficult to use a competitor?
Often, I see 50 people all recording the same exact thing on their iphones. Rather than a single 200MB video, we create 10GB of data. Then I think about how many people are paying a subscription to Apple for icloud storage.
The amount of photo storage being used is impressive. Automatic backup to icloud and server provisioning to reliably store it all is also impressive. I just wonder if it makes sense.
Very little about modern technology "makes sense" in the way you mean. But it does currently make money.
Frenetic economic activity in service of other frenetic economic activity cannot, by itself, be taken as a reflection of quality-of-life improving growth.
Suppose that subsidies lead to the price of Ubers falling close to zero, with drivers also being incentivized to drive more to support the (artificial) increase in demand -- artificial because it is driven by subsidies funded by new money creation. Traffic increases and in response, new roads are built.
Instead of 5 people buying 5 copies of a t shirt that they only wear once a week, why don't they just buy 1 copy and share it?
Is that not how Cloud storage vendors make money? They dedup all that data but still charge every individual for all their data.
A "scion-daemon" is not something I want to meet...
Related, I've always wanted to see someone other than Meta run EdenFS, to hear more reports of what it's like. Feels like there's massive overlap. [Edit: I've chatted with Astra Pro some on this too now, https://chatgpt.com/share/6ace7be6-68f8-83ea-ad68-0f9d144483... ]. https://github.com/facebook/sapling/blob/main/eden/fs/docs/O...
It's designed for container running, but ArtifactFS has some similarity in principle to me. The on-demand materialization. Quote: ArtifactFS is a Git-backed filesystem daemon (FUSE driver) in Go that mounts repositories as normal working trees while avoiding eager blob downloads. https://github.com/cloudflare/artifact-fs
I threw together my own jujutsu powered FUSE subtree project just the other night. This was basically one-shotted, just to see how it does it, to learn more, not really intended for use. But obvious overlap. https://github.com/rektide/jj-workfuse
Seems similar to how version control works for large game and 3D assets. Neat.
If any engineering org needed its own VCS, it would be anthropic.
maybe next month the agents will learn the 'commit locally' and 'git squash' skills
Curious what happened at Anthropic HQ for a week in August
Sounds like they should stop using their mono repo
This is something I've been noodling at, splitting a monorepo into a bunch of component projects. I think, unless they have access to something that is wildly outside the scope and scale of current API models, the downside of having a monorepo is the context pollution, and there's no way to escape that.
I'm not fully sold either way yet but I think splitting might actually be critical for moderating the blast radius of agent intervention.
So, where's the source code for Scion?
Oh, it's not available, what a pity. Why write a whole article about a thing no one can have? Maybe the code isn't so great after all? Or it's all just made up and doesn't even exist?
Anyway, this is yet another pointless ad from Anthropic trying to shill their AI on us.
E = mc²
E energy necessary to integrate changes
m mass of the monorepo
c rate of commits
Sounds like they re-implement fancier CVS?
How much is the sheer volume of slop code that AI generates reduced by if you simply specify that you want it to be both minimalist and readable, getting it to think hard about architecture and completely rearchitecting requirements change? Surely if AI is so smart and useful it should be able to manage that?
This sounds more like a trash pile than a source control system. Anthropic is spewing out code for codes sake. They cant possibly manage it, the more they generate the more they will realize they are just regurgitating training data for no real purpose that can serve anyone.
And for this they buy disk? Maybe this is irresponsible use of technology.
This feels like a really nice design for the data system given the goals. Things that I noted while reading:
* This system leverages a metadata log pointing to immutable blobs in object storage. The metadata log can give high write throughput and keeps the control plane consistent. Object storage supports high throughput of the heavier data objects. Overall, it's an excellent choice given VCS systems can typically tolerate the latencies associated with object storage, as is the case with many operations-focused systems for businesses.
* The server/upstream gains scalability by reducing the amount of data it processes when accepting a commit/performing standard VCS operations. No packfile, no file i/o to construct a consistent copy of the repo, just a (usually) small metadata record that can be validated/committed quickly. The client primarily gains scalability along a similar axis (reduce amount of extraneous work for a given goal) where it can request just the pieces of a repository it needs to do its job, when it needs them. For example, agents can begin reading files from a checkout eagerly before the whole updated version of the repo is finished being downloaded, then during a compile step, updates can be fetched only for the module being compiled, etc.
* The system seems well designed from the perspective of considering "when exactly do I need a thing to be done." Git tends to bundle more of this work into synchronous operations when a request comes in, which ensures the system is consistent at the end and doesn't require a persistent process, but is costly. This system makes intentionally different decisions about "what work happens, when" so that the minimum amount of work is done to confirm a write and allow for the state of the repo to be reconstructed consistently, but it defers certain things that are useful but don't need to block a write. The discussion of "derived data" mentions that certain useful structures can be computed in a deferred way, which supports doing work around the time it's needed.
* A large part of the nice operational features of the system is downstream of making core data structures immutable. File contents are immutable, content-addressed blobs. WAL entries are immutable records. As mentioned in the article, this supports excellent caching, and simplicity in reasoning about history/updates. Additionally, the derivation of other useful data can end up as immutable outputs (themselves stored as pointers to objects, if scalability requires it).
* The decision to develop a custom VCS supported a number of other integrations into "agent-first" software development systems. The system makes it easy to enforce access control on specific directories, nice if you want to have agents explicitly denied the ability to edit something. You can also get a sense that it supports some valuable features in the associated code review system, for things like pointing a human at the most important changes in a changeset. You could imagine in the future, some associated highly flexible "owner" rules/notifications where a human can specify "I want to be notified if X system has a significant design change" and that intent can be recorded/managed in a more useful way than "add me as a reviewer if files in /abc directory change."
* I do wonder if content-addressing of the files is broken into chunks or not. Doing "one blob per file" is nice and simple, so maybe that's how it starts. But you also duplicate a lot of data, but maybe the dataset is still trivially small in the scheme of things, and the operational concerns win out. And if files are small anyways, you'd want to avoid splitting them into tiny chunks bc that'd affect the bandwidth you can achieve when downloading (spend more of your time on per-object/request overhead rather than actually transferring data).
Very nice piece of engineering work. I was also impressed by some other parts that received a little less discussion in the post (understandably), but would love to hear more in a future post:
* the testing approach of driving tons of system interactions in a hermetic way is really exciting to see. Feels like agents should help us write really excellent testing infrastructure, and that this would itself be important for gaining confidence to deploy without requiring a read of every line committed.
* Similarly, the mention of the "superfan" agents that closely monitor very specific parts of the system seemed very cool and would help a lot with deploying code you haven't necessarily read closely but seems reasonable architecturally. Though it'd still ofc be best to catch issues prior to merge/release, having extremely good monitoring/rollback capabilities would mitigate a lot of the downsides of high-speed, agent-based software development.
> You could imagine in the future, some associated highly flexible "owner" rules/notifications where a human can specify "I want to be notified if X system has a significant design change" and that intent can be recorded/managed in a more useful way than "add me as a reviewer if files in /abc directory change."
Good observation! If we share details about Antique, this will definitely be in there; this space is ripe for innovation.
For the "one blob per file" piece, blob storage is fairly cheap, but there is also a relatively simple way to get something like delta compression for blob storage that the clients never need to know about.
I honestly think that these AI companies really messed up their futures by adopting a token model. They should have gone the route of IBM and offered consultant services.
Practically speaking, it’s difficult to offer Scion in a form that would be broadly useful to other organizations. It diverges significantly from git, meaning companies would need to migrate every piece of the development lifecycle, and it requires its own code review, code search, and CI. Our internal versions of these components are highly bespoke, so they would be difficult for other organizations to adopt, and we worry that attempting to build a public version that tries to please everyone wouldn’t actually be very useful.
They should concentrate on their models instead. If claude code is any measure, their software engineering is atrocious. I would only use something like source control from them if they force me to, at which point I would rather do something else.
Extremely annoying - can we throw anthropic class resources at more agreed upon solutions across companies. We don't need custom source control at every company - google has its own, fb has its own and now Anthropic.
Can please we all converge to 1 f'ng solution.
how does it compare to Epic's https://lore.org/ ?
why u want a single solutions for many problems?
I wonder what happened in late July, early August - the 'quiet period'
Did they just reinvent cvs/svn?
Solving monorepos in an LLM world seems to be very universally applicable as a need.
I appreciate it's different than git, that type of argument for monorepos is not new.
Agents coding is akin to having a very large developer team, who may or may not be online 24/7.
Anthropic is calling it very specialized, and it's a little baffling.. maybe I'm missing something.
There's no way software development is the same anymore. The previous ceremonies and structures and seats at the table at each stage were human based, and now that's a different make up to the point that different steps and processes are needed.
There's nothing more fundamental to growing software development other than making tools like this available.
My hope is a vibe coded internal mono repo management tool can aim for a v2 with multi-tenancy built in.
Was anyone else looking forward to feature flags as a part of a post like this?
> Was anyone else looking forward to feature flags as a part of a post like this?
I am looking for agent-world feature flags, but not in a post on source control. Feature flags belong to wider SDLC.
I'm worried that the frontier lab doesn't read the code they are writing.
It's also hard to believe all these non-Git alternatives aren't merely an attempt to capture developers into a new proprietary solution.
This could have been done as an open-source fork of Git.
Yea, I'm pretty much hiting the same limits. I'm still using git for the time being, mainly because I package everything as daily commits with an external orchestrator managing tasks/issues. Lately my code velocity is at ~1 million LOC added per week, spread throughout my various repos (I don't use the monorepo approach). Problem is I'm looking at 100x this velocity over the next few months when I get a new code generator up and running, so I'll definitely have to drop git.
Another issue that I believe Anthropic here didn't state is that git performance _severely_ get degraded when you have hundred of commits landing in parallel. Hence why I fell back to the daily commit approach. You get less granularity but you get stability.
Only 1 million lines of code per week? That’s adorable. I remember when I was still slopcrafting software at that scale. Personally, I’m generating 100 billion LOC per hour, but Git became unusable once my commits started affecting Earth’s gravitational field. I’ve since moved to a custom version control system that stores code directly in the fabric of spacetime. My biggest bottleneck now is that the observable universe lacks sufficient entropy to generate unique commit hashes. Anthropic really needs to address this.
Honey, it's time for your daily Anthropic PR piece!
All the other tech billionaire are jealous: they all want their own recursively-self-improving megacorporation.
Am I the only one not feeling the output of this velocity?
We’re completely rethinking our priors. This project prompted us to take a very hard look at other workflows designed for human scale. A proper merge queue, for example, doesn’t make much sense at agent scale. What does CI even mean when hundreds or even thousands of changes can merge while tests are running? We haven’t been able to effectively replicate the industry standard of a global repository lock on the merge queue, so instead, we’ve invested in post-merge and pre-deploy automated testing. This does mean that concurrent changes can conflict, but Claude can typically fix these conflicts faster than humans can even identify them.
come on HN debate the merits of the design not the flaw that Anthropic has infinity tokens and "why even do source control at that point?"
This is such a Claude written post. Obvious tells everywhere, but the most annoying is how it uses private terms without defining them. What the fuck is "Spanner"? It refers to it multiple times. Of course we know the reason is that some dickhead at Ant told their Claude to write a blog post, and Claude being Claude has very poor/non-existent theory-of-mind for people and generates this trash.
https://cloud.google.com/spanner, though technically any database would work if you know how to scale them. Spanner just has a few nice properties for our scale.
Good call about us not defining it, I can fix that! And this blog post was 100% human-written.
1. I've seen ai-written code. Ugh...
2. So they're trying to make code so complex that humans can't read it anymore?!
3. What's the point of changing code? Are the changes - how do you say - useful?
4. Thank God for Git, the amazing piece of software by the venerable Linus Towalds, that just keeps on giving! It's free, open, and excellent quality source-control software, and you can even keep binary files there. Excellent stuff. I can't imagine ever not using it.
tl;dr why is it better than git?
> Git offers tools for working with a slice of a repository, such as shallow clones, sparse checkouts, and promisor remotes.
I honestly just cannot. Just tell me what the workflow is. Give me a video that is Twilio-level simple explanation.
the quote does not seem to match your statement here
Back to SVN then? Noted.
Oh wow. There is nothing I'd rather use less than version control vibe coded by Anthropic.