Which models can actually do CAD?
PartForge is an agentic coding harness for parametric CAD. An AI agent works with you to turn a prompt, and whatever guidance follows it, into a small program that generates a 3D model. Along the way it has the documentation, a reference library of published parts, and web search. After each step of a build it gets screenshots and measurements of the thing it has made. That makes this an unusually direct way to measure how the current models handle vision, tool use and reasoning about 3D geometry at once.
This run is the hard end of the suite only: 7 models over the 26 hardest tasks, 502 attempts in all, up to three per task for each model. Each attempt is graded on whether it built, on measured geometry, and on a checklist an AI judge answers from the renders, and a person ranked every task by hand. Click any number to open the attempt behind it. The first baseline, over the whole suite from easy to hard, is still on its own page.
Quality
against
What we found
Cost and time still spread much further than quality did. Among the models that finished every task, the field runs from $0.02 to $0.42 a task, and from 1m 39s to 2m 16s.
The human ranking put Gemini 3.8 Flash first, only just ahead of Opus 5.5. It stays the default model for PartForge users. It costs about half of what Opus 5.5 does.
The two cheapest models, GPT-6 Luna and DeepSeek V4.1 Flash, cost $0.02 a task or less and land within 7 points of the top score.
Kimi K3 did not get going. On most tasks it sent edits that deleted the part's file without writing the new one, retried the same edit, and ran out of steps, so few of its attempts ever built. The faster Kimi K3 variant did the same, and we stopped it partway through to save cost, which is why this run is marked as stopped early. Neither is ranked.
Where the score and the reviewer disagree
Overall gives partial credit at every layer. This run's five spread over 8.6 points. Where the two orders below cross, the score is missing something the reviewer saw.
All models
Rank by
Overall gives partial credit at every layer, so the top of the board bunches. Strict counts only the attempts that got everything right. Gate pass is the share whose part was watertight, hole-correct and overlap-free. Hover any bar for its number. Ties break by cost, then time. In Quality, the bar marked with a person is one reviewer's ranking of the cases they ordered by hand. First place is 100%, last is 0%, ties share, and the tick marks 50%. That reviewer marked some first attempts unacceptable: DeepSeek V4.1 Flash 96%, Kimi K3 Fast 50%, Kimi K3 (Moonshot) 15%. Neither affects Overall or Strict.
These are the suite's hardest tasks: parts that have to fit a bearing, a motor or a Raspberry Pi, rebuilds from a photograph or a scanned mesh, and edits made over several turns to a part that already exists. Every one of them grades what the model built rather than what it said about it. The methodology page has the details.
Browse the tasks
Hard
608 bearing seat
Bottle neck adapter
Cable clip
Drawer divider
Extrusion 2020 end cap
Mesh add tabs
Mesh holder holes
Mesh rebuild blender handle
Mesh rebuild freecad bracket
Mesh rebuild freecad knob
Mesh rebuild scan
Mesh socket mount
Nema17 face mount
Photo cluttered real
Photo knob
Photo knob oblique
Photo lid
Photo motor bell
Photo motor bell unstated
Photo resistor
Rpi4 tray
Bracket second mount
Enclosure build up
Knob then widen
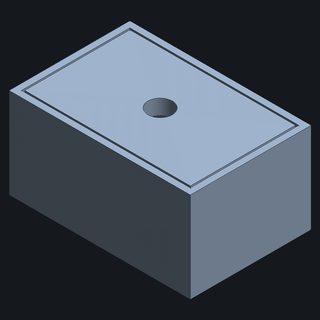
Lid fit and finger hole
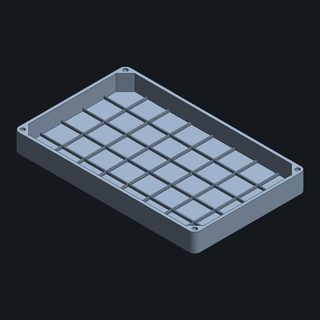
Photo lid then centred
How the score is made
Built 30%, measured geometry 50%, AI judge 20%. A failed gate zeroes geometry for that attempt. The AI judges are Opus 4.8 and GPT-5.6 Sol. Read the methodology.
Run hard-baseline-2026-09-232026-09-23commit 6edf19e0spend $212.67 + $43.09 AI judging, 15 unpricedstopped early (interrupted)Other runs: 2026-09-10T19-44-23-baseline-2026-09, 2026-09-04T20-02-10-stage2-hard-cases, 2026-09-04T19-48-31-screen-14-fixed