- Introducing the smallest model in our new architecture family, with native visual understanding.
- Designed for greater capability, faster inference, higher throughput, and scaling to larger models.
- 552B-parameter MoE.
- New Causal Encoder–Decoder architecture: just 8B active parameters for input, 16B for output.
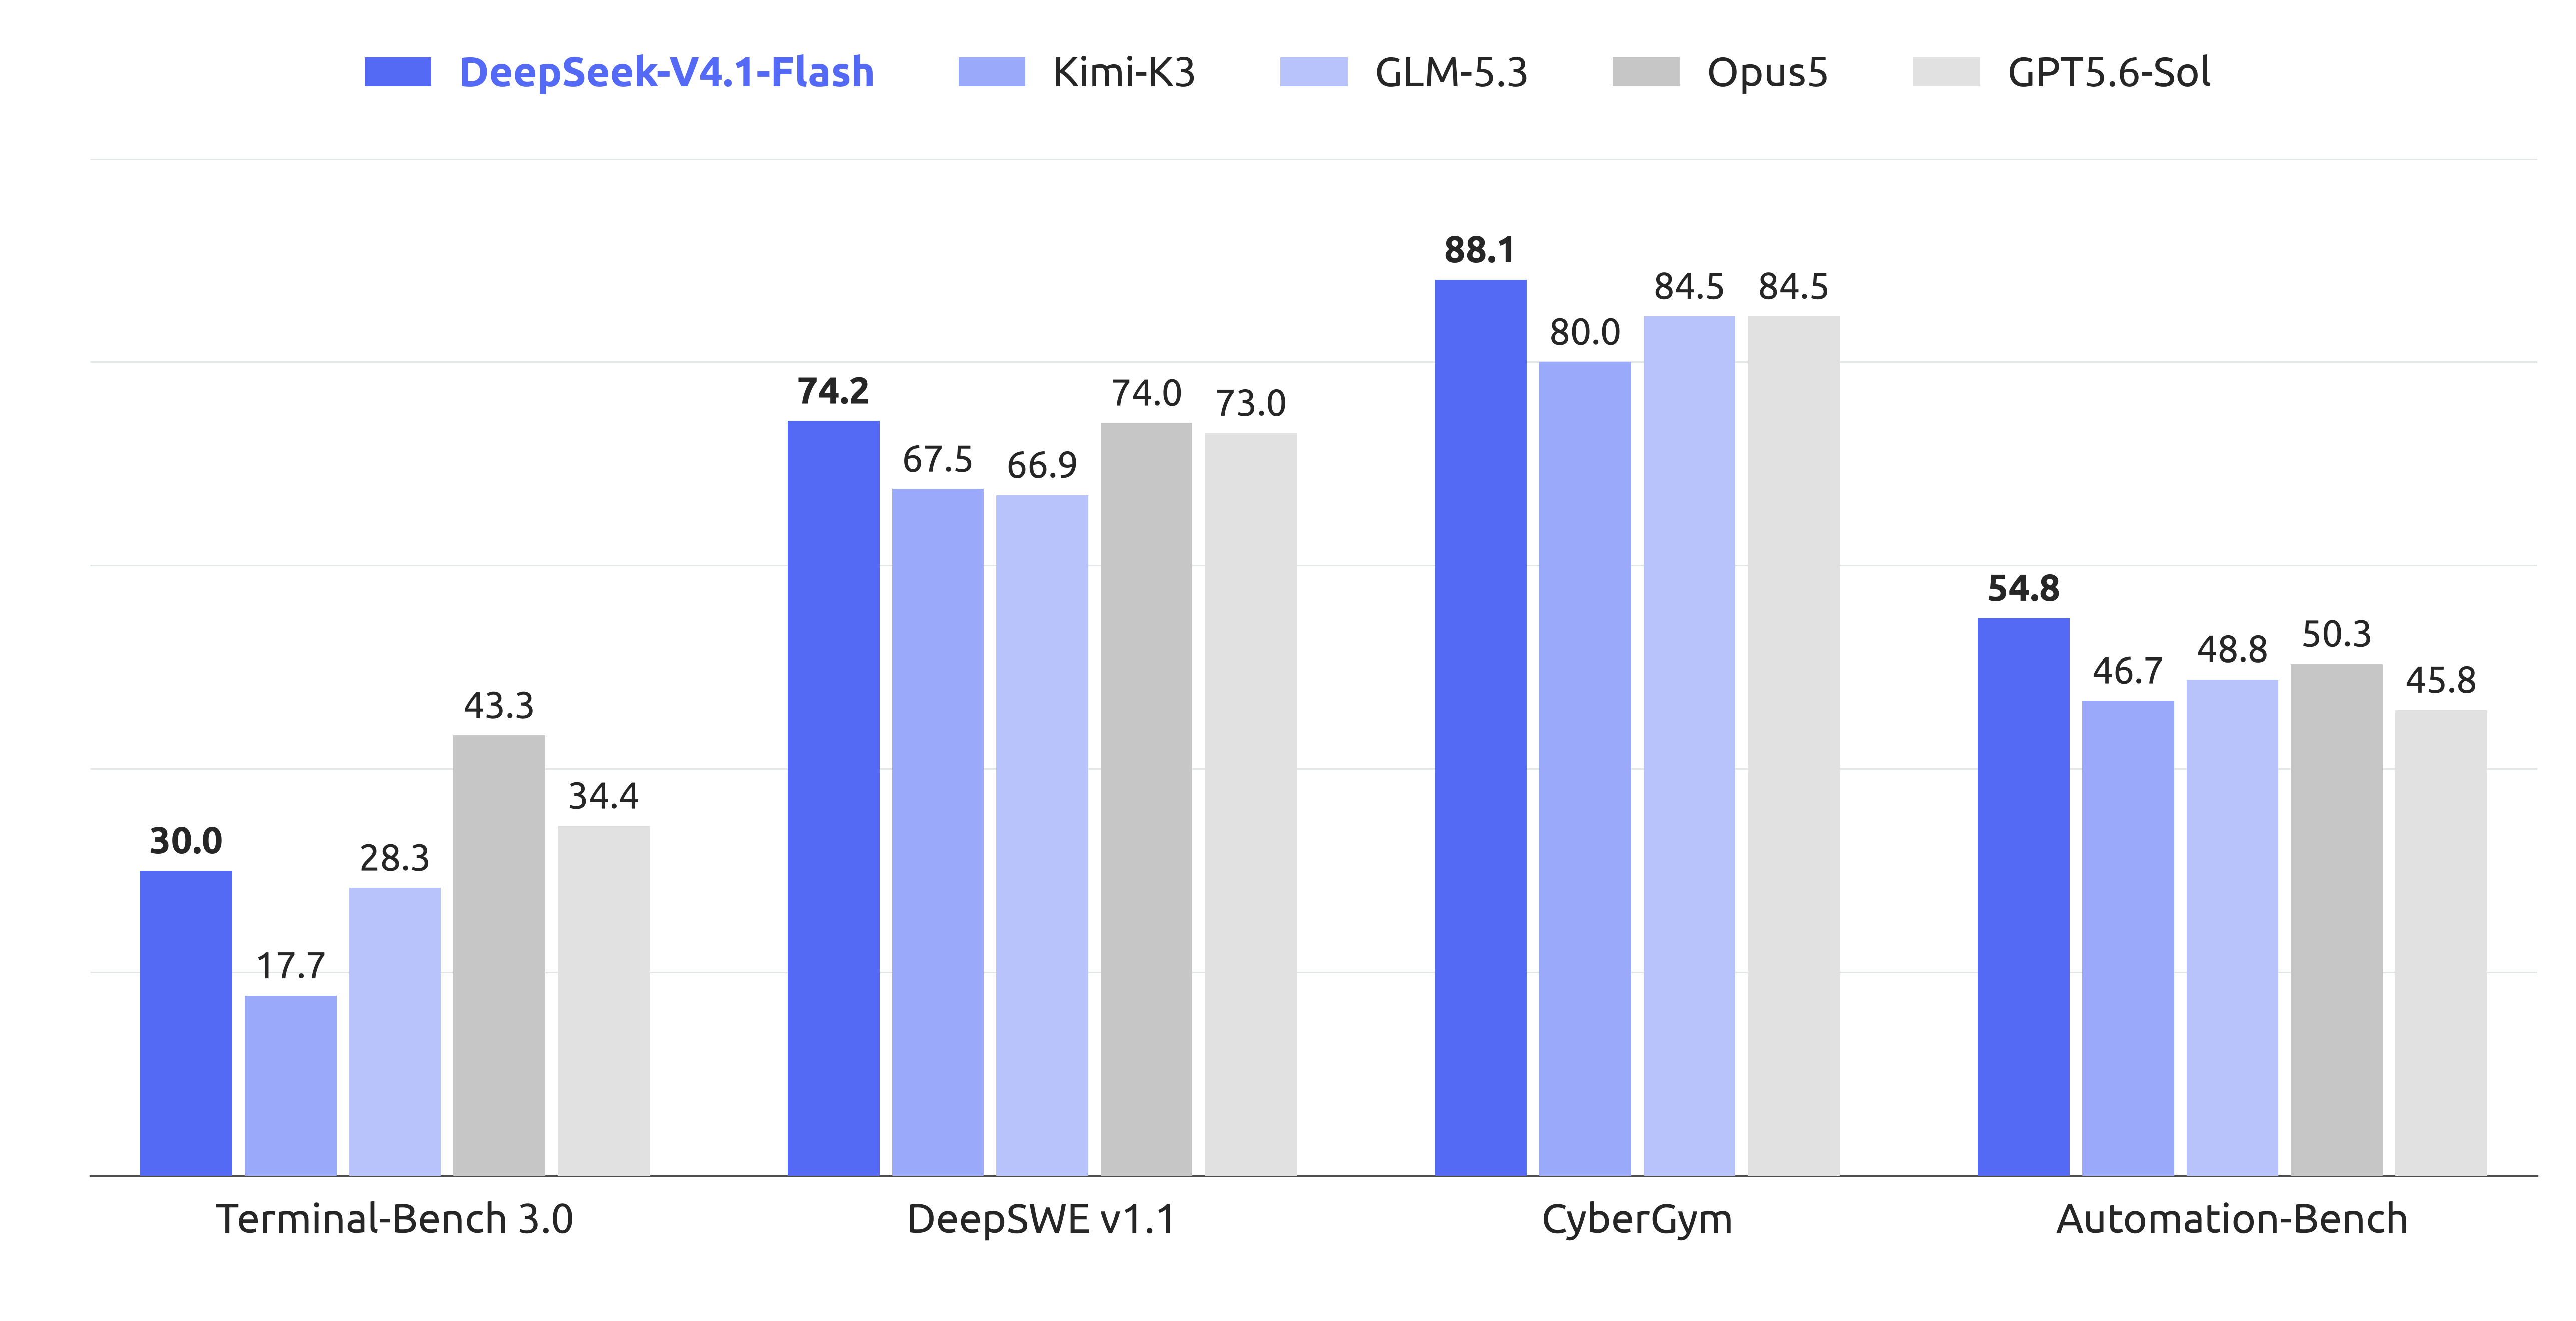
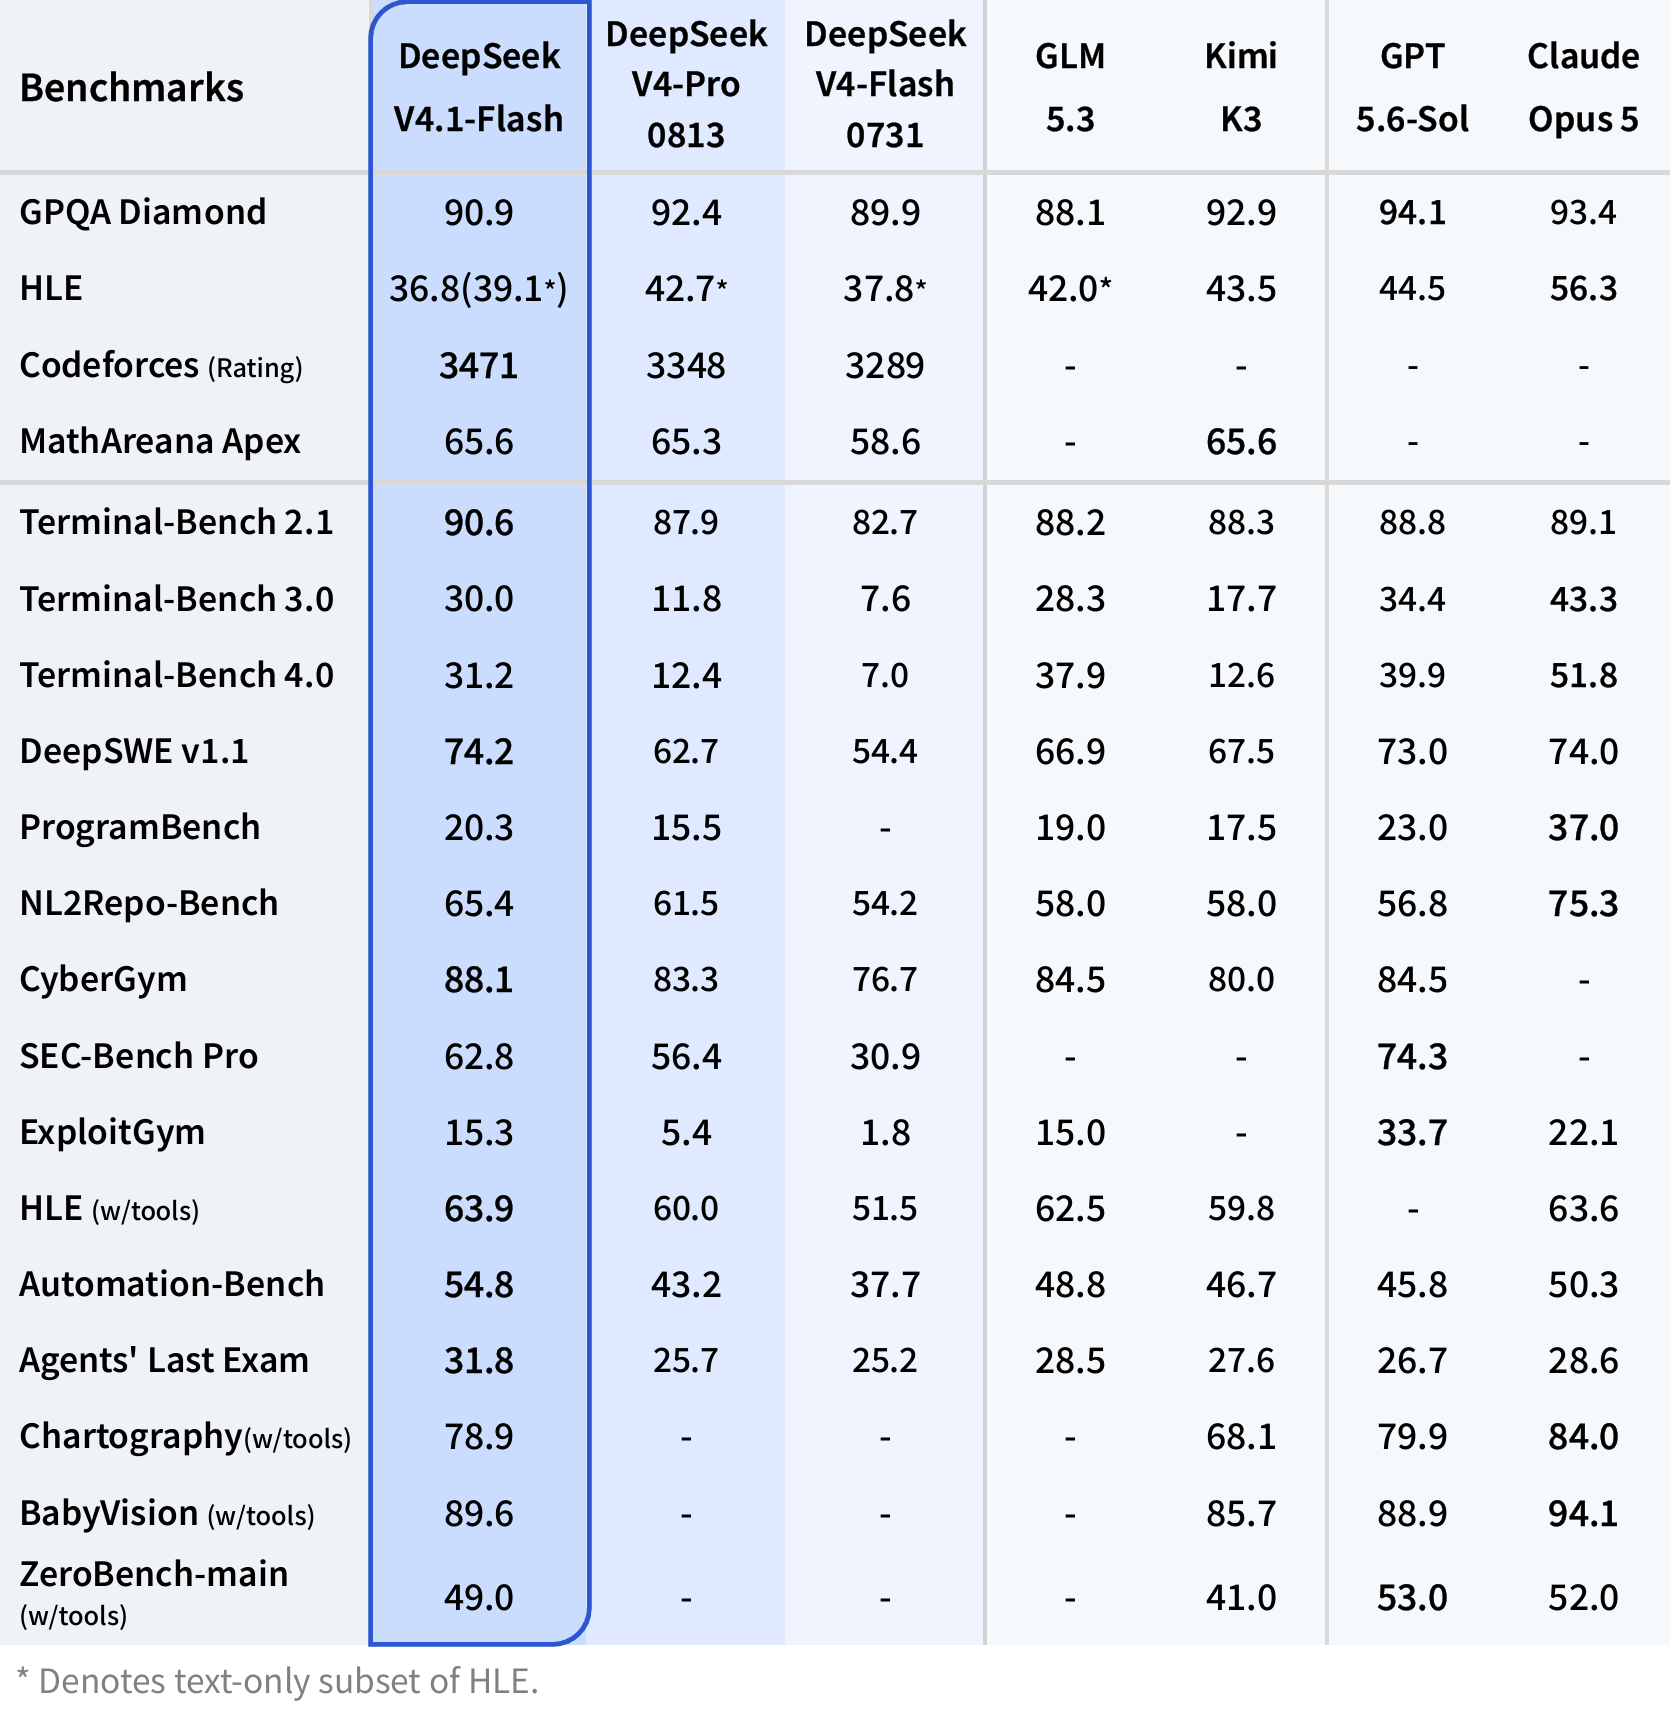
- New pretraining methods + larger-scale RL post-training deliver benchmark results ahead of flagship models, including DeepSeek-V4-Pro.
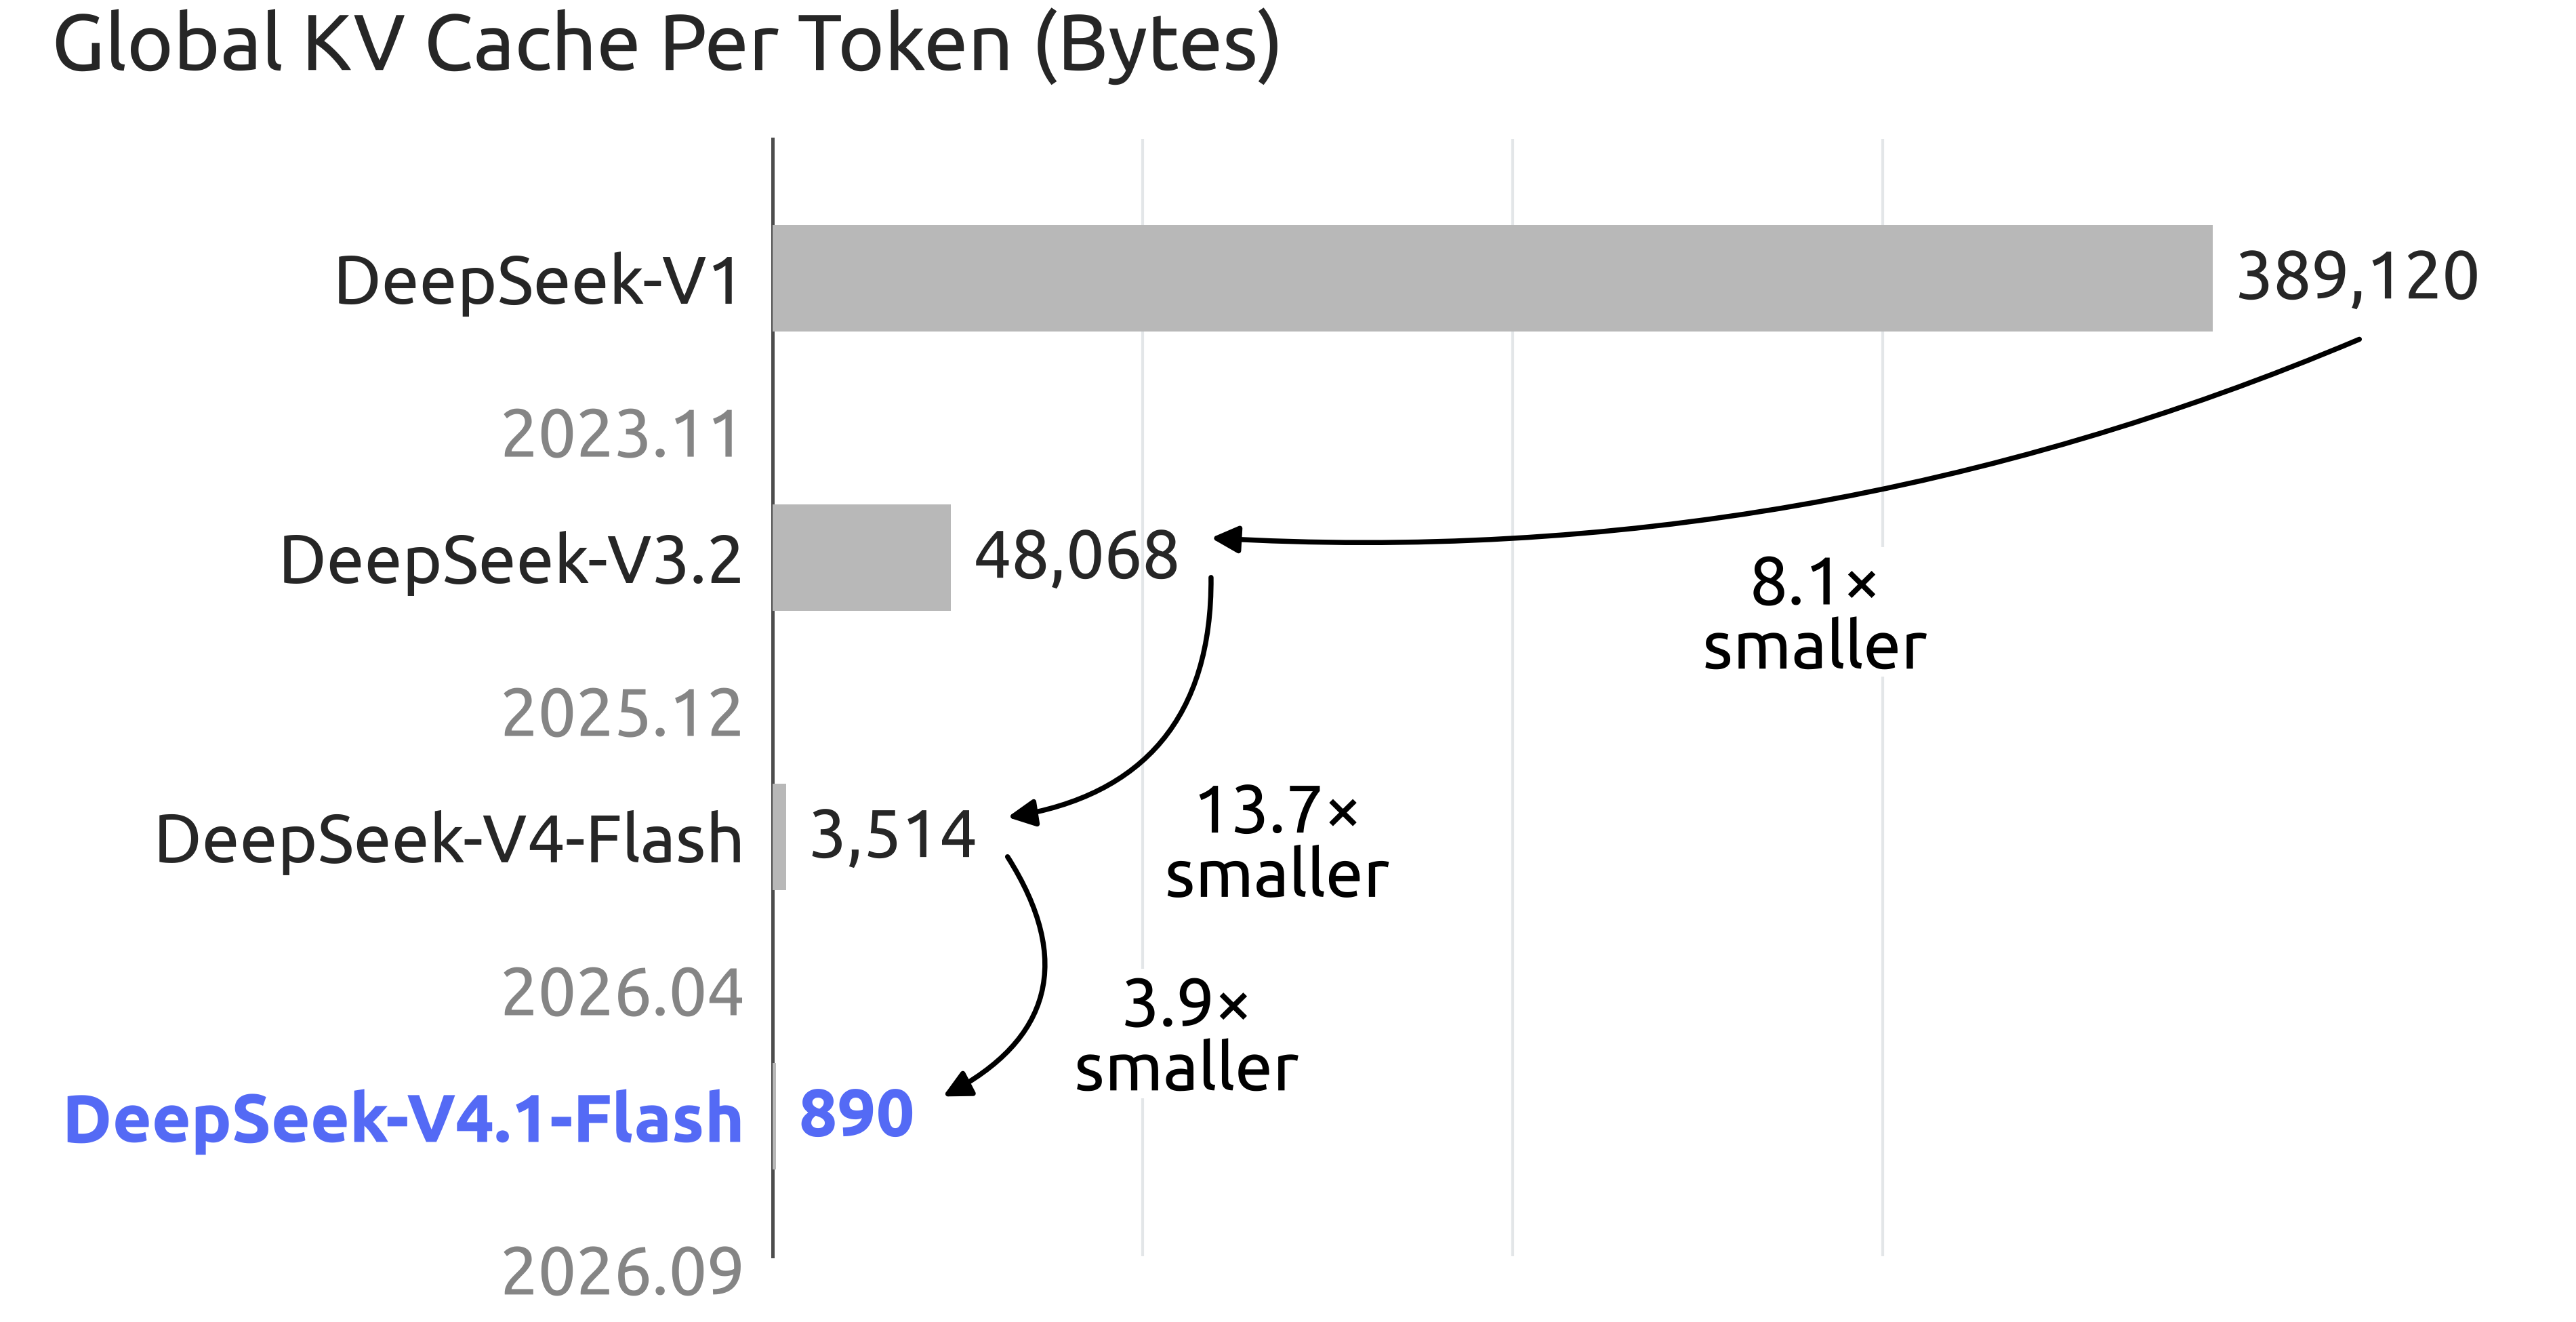
Compared with the previous generation, V4.1-Flash’s KV cache needs just:
- 1/4 the HBM
- 1/8 the SSD storage
Cache-hit charges often account for a large share of agent costs. Compressing the cache cuts those costs significantly.
Set your model to deepseek-flash.
- V4-Flash & V4-Flash-Vision-Exp are retired. For compatibility, deepseek-v4-flash and deepseek-v4-flash-vision-exp temporarily route to V4.1-Flash.
- Tests by multiple parties put V4.1-Flash ahead of V4-Pro on performance, cost, speed & total runtime. We’re phasing out V4-Pro.
- Starting at 04:00 UTC on Sept 14, 2026, all deepseek-v4-pro requests will route to V4.1-Flash at V4.1-Flash rates. This will continue until V4.1-Pro launches.
Official partners WorkBuddy (including CodeBuddy) & OpenCode now fully support V4.1-Flash. Try it today!
V4.1-Flash lets us serve more users at a lower cost. We’re passing the savings on to you.
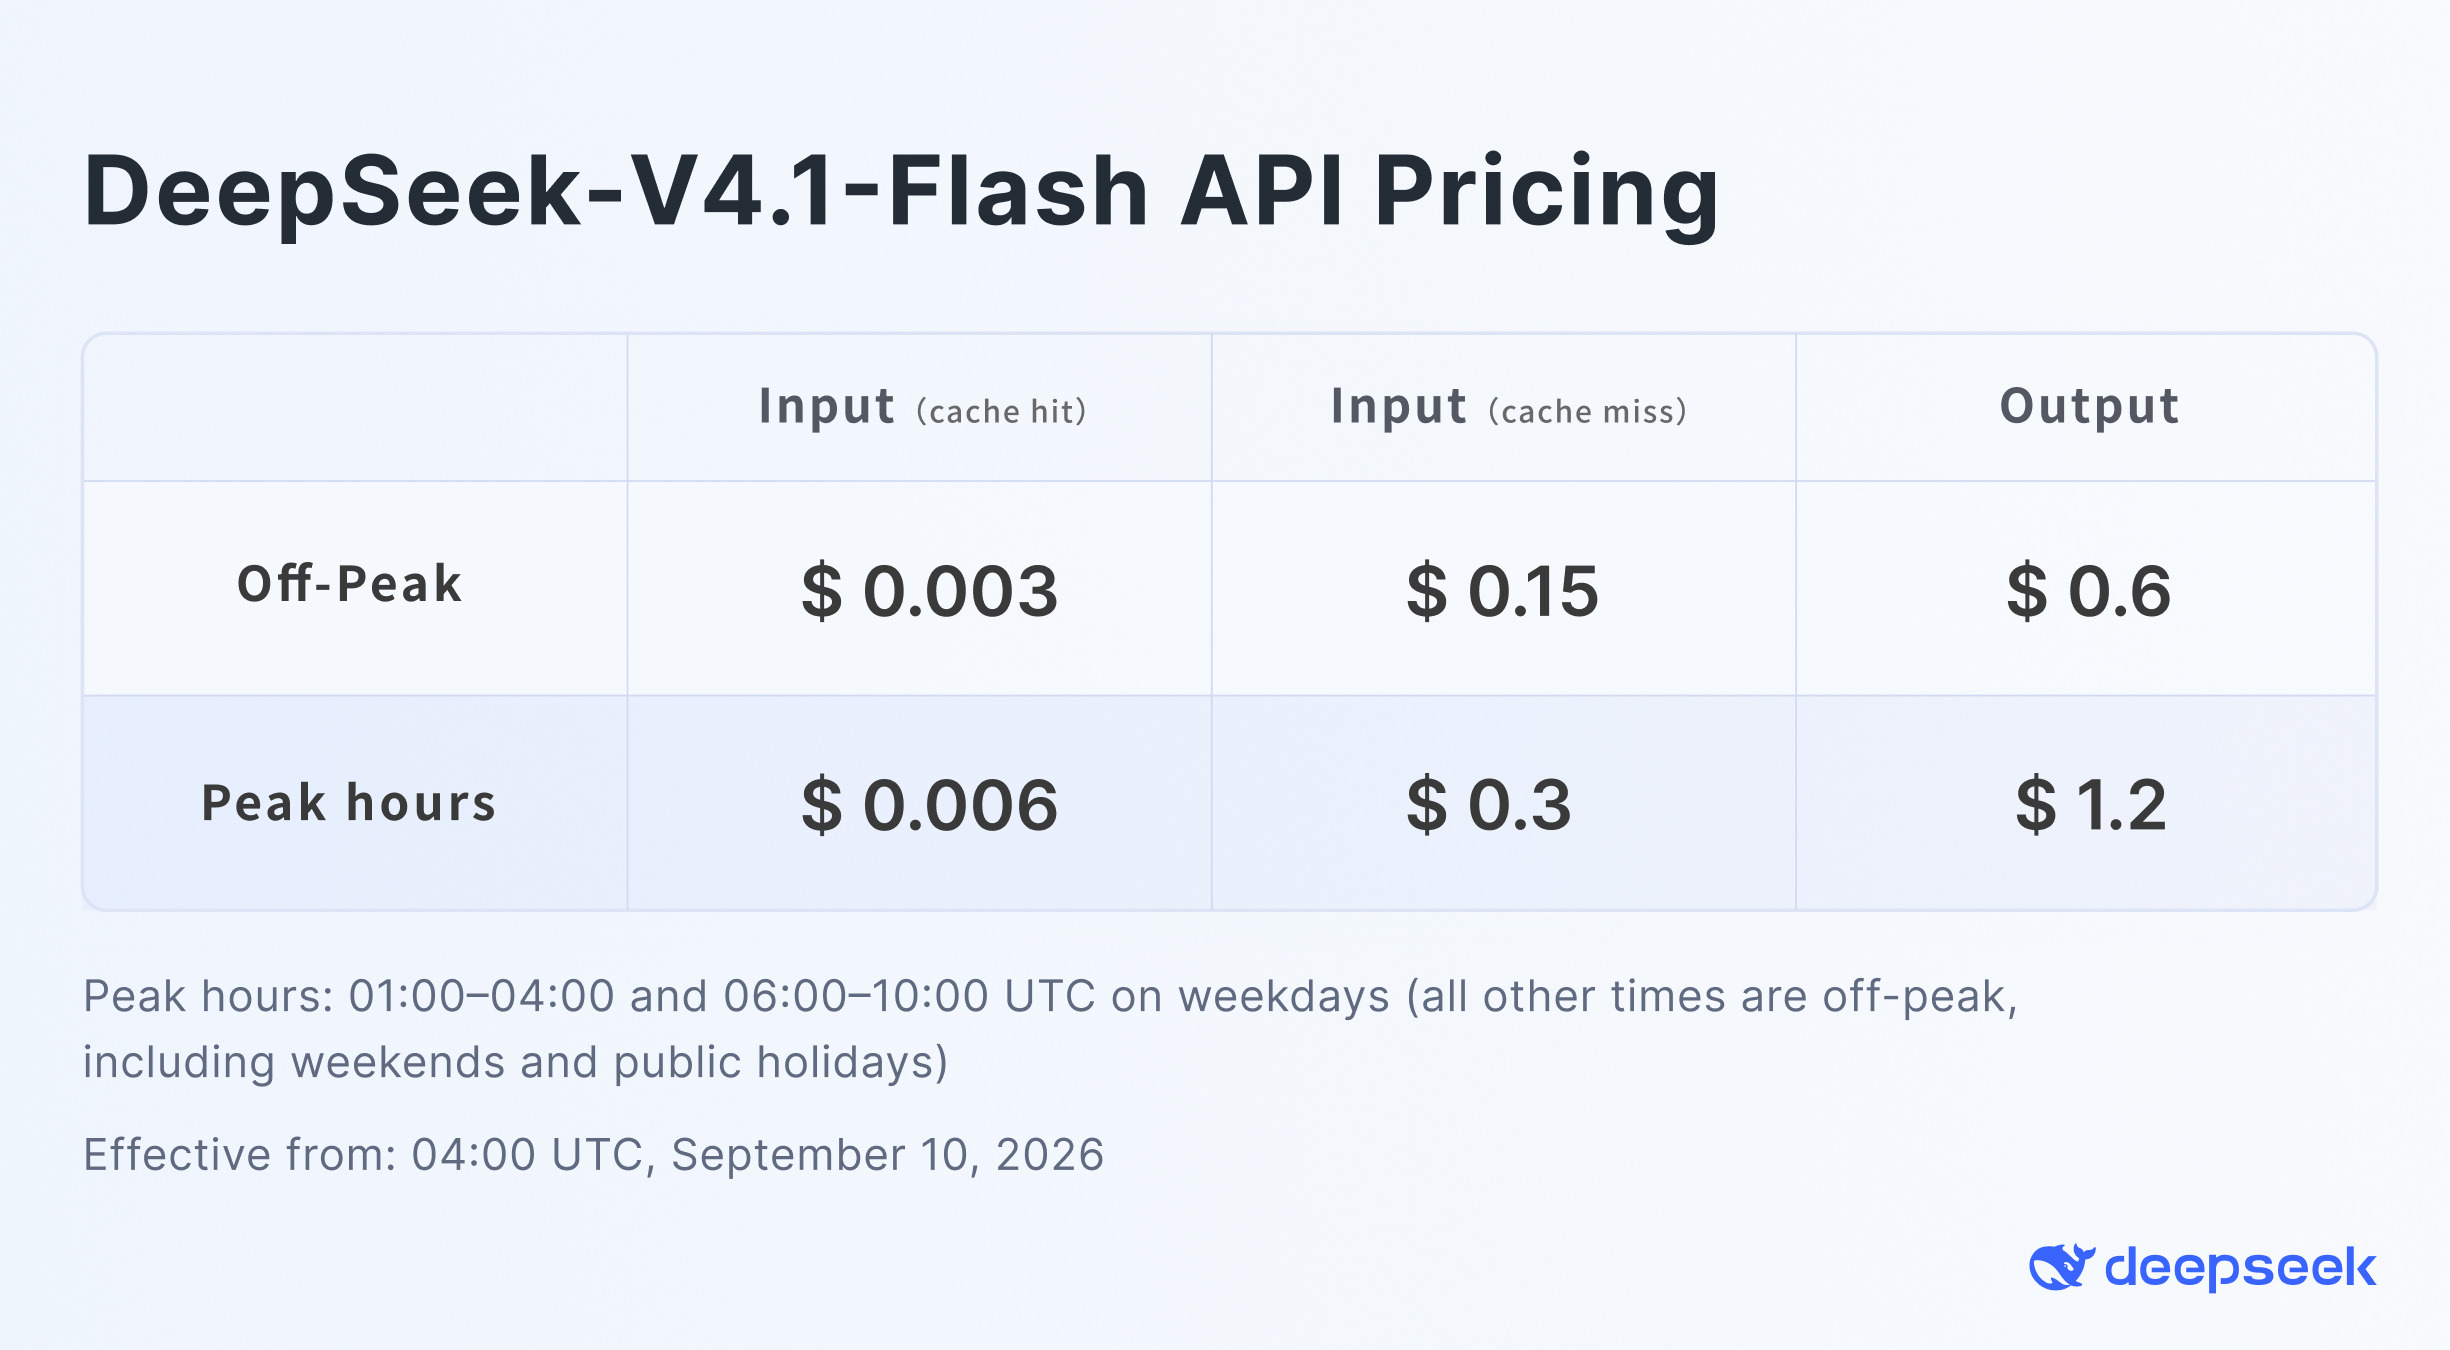
- Peak/off-peak pricing continues to balance demand.
- Off-peak rates are 50% of peak rates. Schedule flexible workloads off-peak to save.
- New pricing takes effect at 04:00 UTC on Sept 10, 2026.
We’ll work closely with the open-source community on V4.1-Flash inference support and explore more deployment options.
Planning a large-scale deployment with 2,000 GPUs + a storage cluster? Let’s talk.