Part I
Motivation & Concepts
Fundamental knowledge and core hypotheses.
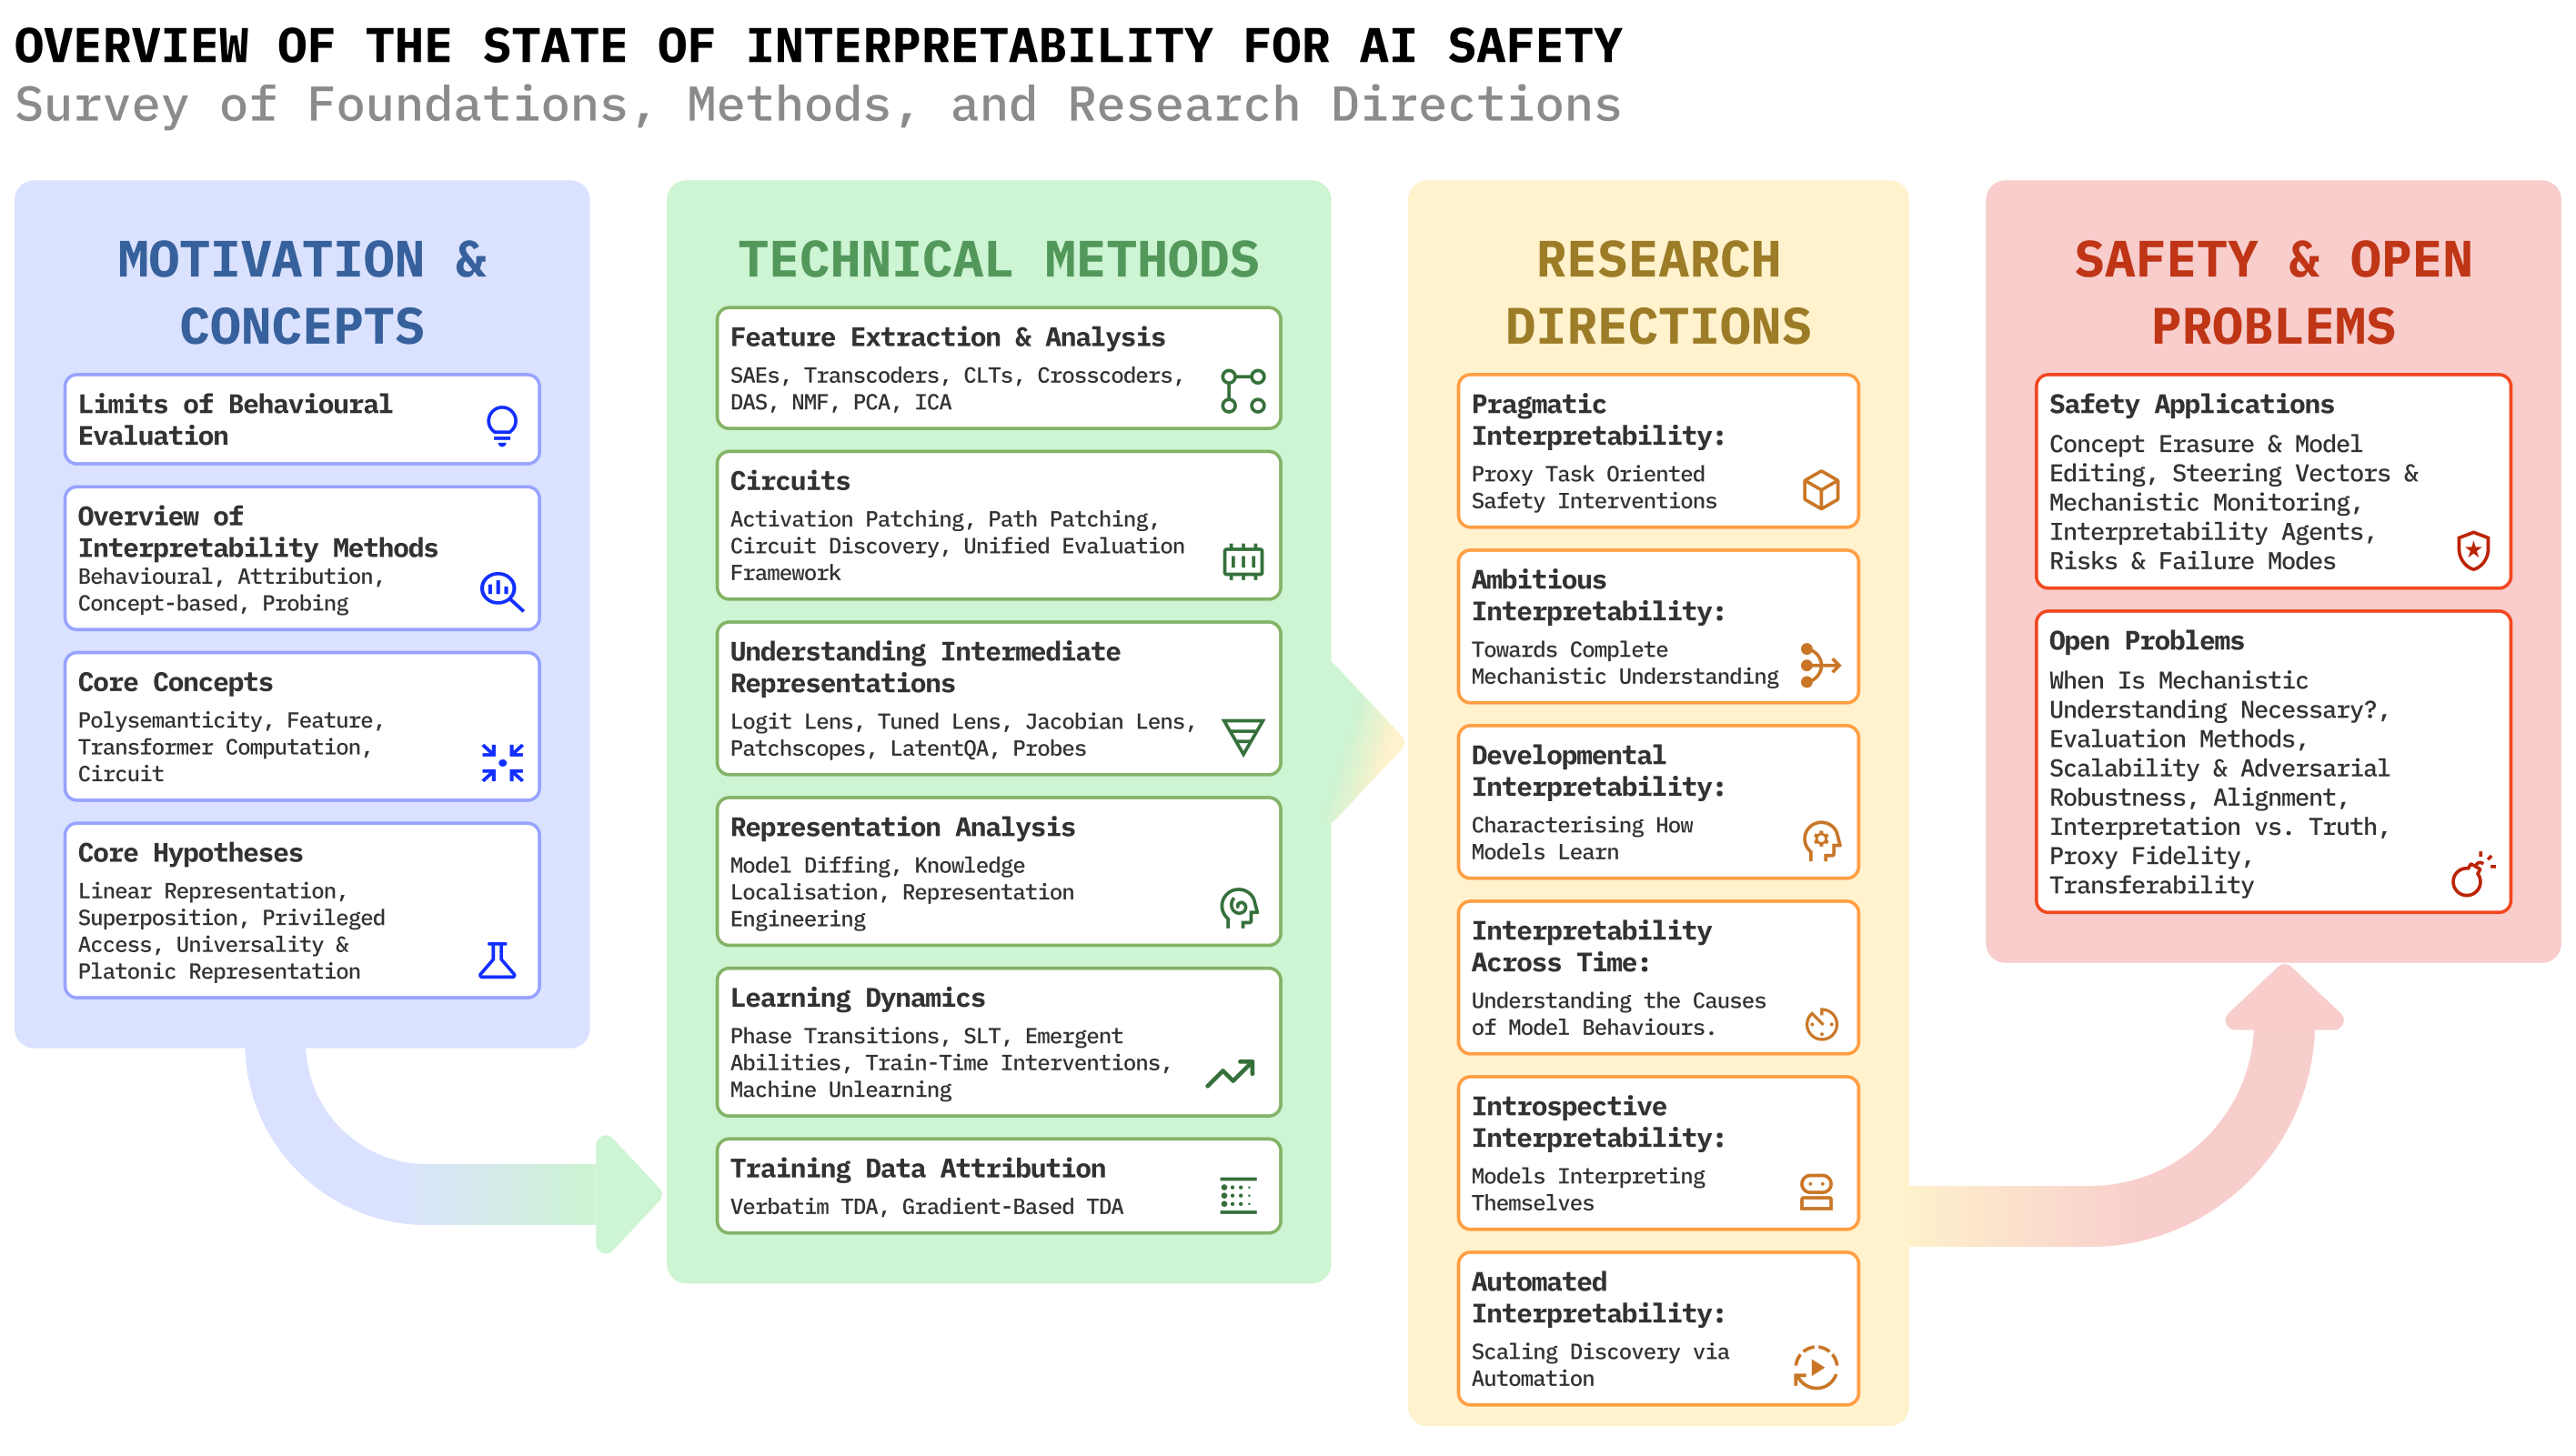
Limits of Behavioural Evaluation · Overview of Interpretability Methods · Core Concepts · Core Hypotheses
Authors
Tung-Yu Wu1,†
Hunar Batra1, Gabriele Dominici3, Florent Draye4, Yanai Elazar5, Damiano Fornasiere6, Antía García2, Abir Harrasse2, Riley Harris1, Sara Hooker7, Michael Lan2, Belinda Z. Li8,9, Aaron Maiwald1, Narmeen Fatimah Oozeer2, Naomi Saphra10, Or David Shafran11, Adi Simhi12, Robert Trager1, Shriyash Kaustubh Upadhyay2, Ziyu Yao13, Yu Zhao1,14
Shay B. Cohen14,‡, Mor Geva11,‡, Yoshua Bengio15,6,‡, Stella Biderman16,‡, Hassan Sajjad17,‡
† Core contributors. ‡ Senior advisors. Remaining authors listed alphabetically by surname.
* Correspondence to fazl@robots.ox.ac.uk
Affiliations
Abstract
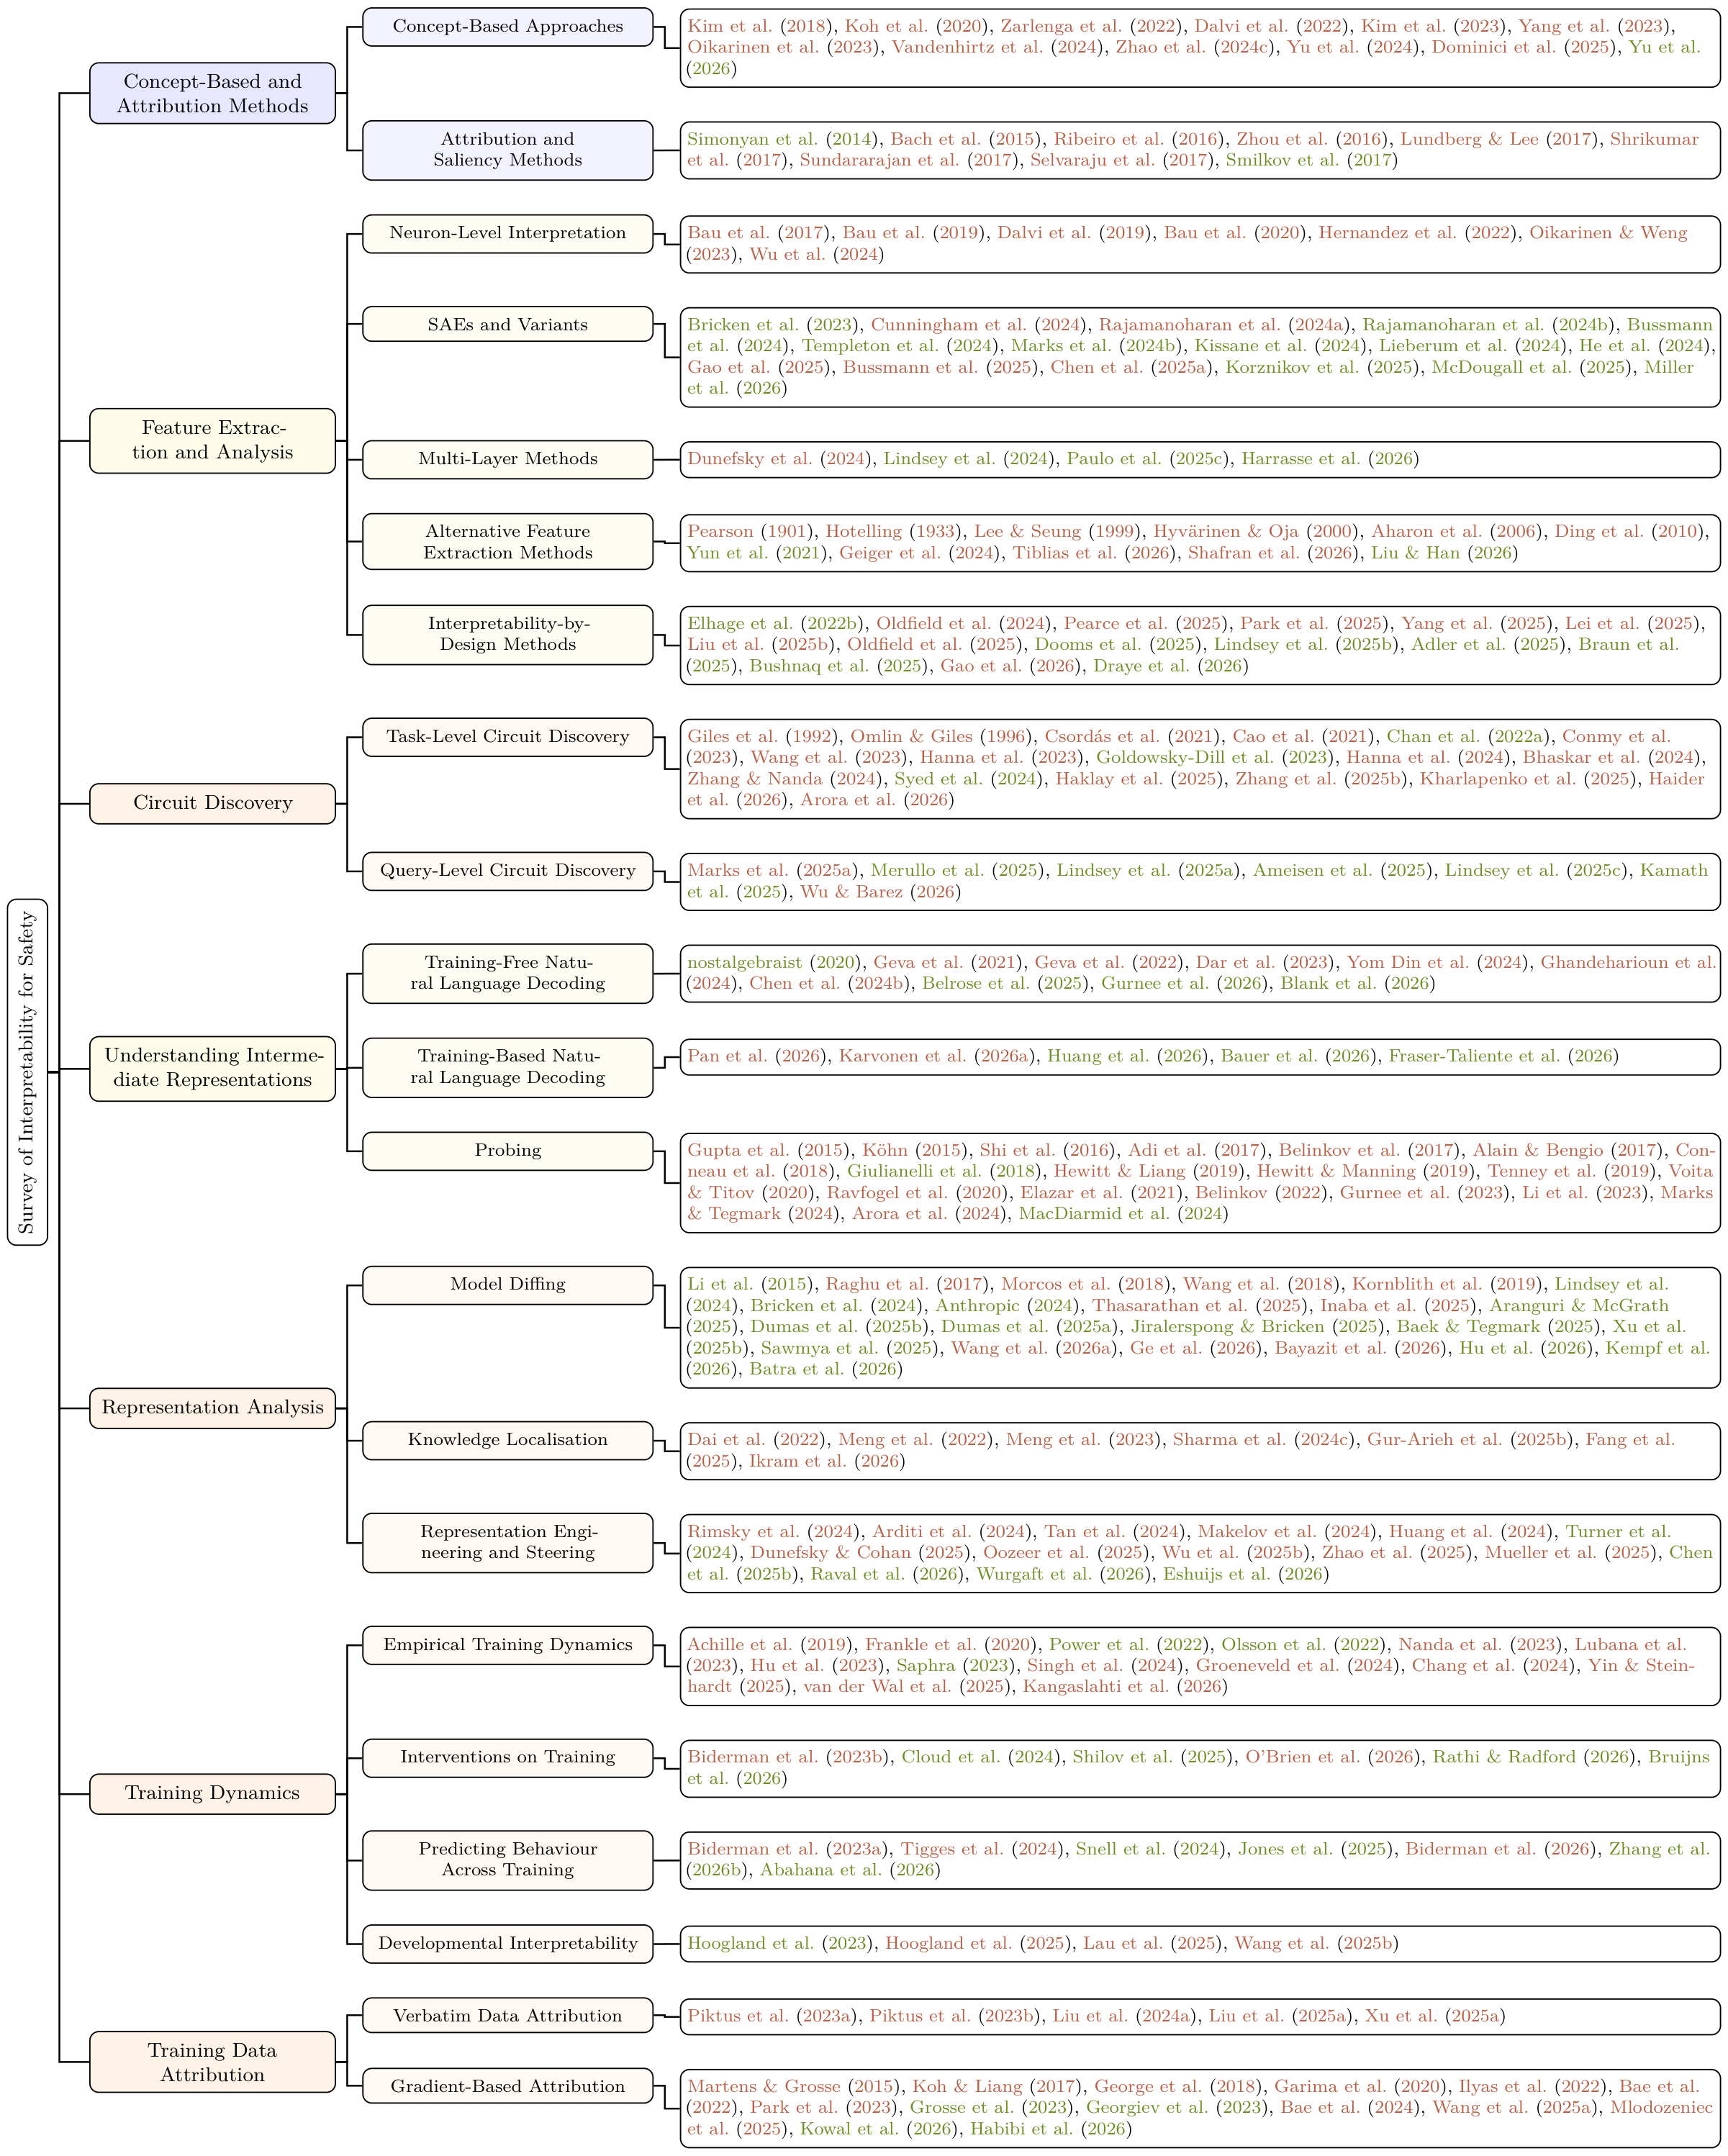
We survey interpretability for AI safety, focusing on mechanistic interpretability (MI)—the study of neural networks’ internal representations and computations to develop causal understanding and support targeted interventions. We first situate MI within the broader interpretability landscape, contrasting its mechanism-level evidence with behavioural evaluation while emphasising how behavioural, attributional, and representation-based methods can complement mechanistic analysis. We introduce core foundations for MI from first principles, including features, polysemanticity, superposition, transformer computation, and circuits, and survey methods for feature extraction and analysis, circuit discovery and causal verification, interpreting intermediate representations, training-data attribution, learning dynamics, knowledge localisation, and representation steering. We then characterise six research orientations—Pragmatic, Ambitious, Developmental, Interpretability Across Time, Introspective, and Automated Interpretability—as agendas defined by their goals, assumptions, and trade-offs rather than by exclusive method sets. Finally, we examine how mechanistic understanding can support safety interventions, including knowledge editing, steering, monitoring, and automated interpretability agents, while assessing their limitations, failure modes, open problems, and relationship to behavioural safety measures.
Part I
Fundamental knowledge and core hypotheses.
Limits of Behavioural Evaluation · Overview of Interpretability Methods · Core Concepts · Core Hypotheses
Part II
Approaches developed and used in interpretability research.
Feature Extraction & Analysis · Circuits · Understanding Intermediate Representations · Representation Analysis · Learning Dynamics · Training Data Attribution
Part III
Six research orientations, characterised by their goals, assumptions, and trade-offs.
Pragmatic Interpretability · Ambitious Interpretability · Developmental Interpretability · Interpretability Across Time · Introspective Interpretability · Automated Interpretability
Part IV
Deployment-oriented interventions and the critical challenges that remain.
Safety Applications · Open Problems
Figure
Read
The handbook The full survey, by chapter.
Compare
Methods explorer The methods in the survey, side by side.
Judge
Evaluation framework Five dimensions for evaluating interpretability claims.
Orient
Research orientations Six research agendas and their trade-offs.
Apply
Safety and open problems Safety applications and open problems.
Run
Experiments Superposition, sparse autoencoders and activation patching.
Code
Notebooks 19 companion notebooks.
Taxonomy
Citation
arXiv: 2611.08438 · alphaXiv
@misc{barez2026understandingaiinsidestate,
      title={Understanding AI from the Inside: The State of Mechanistic Interpretability for AI Safety},
      author={Fazl Barez and Tung-Yu Wu and Hunar Batra and Gabriele Dominici and Florent Draye and Yanai Elazar and Damiano Fornasiere and Antía García and Abir Harrasse and Riley Harris and Sara Hooker and Michael Lan and Belinda Z. Li and Aaron Maiwald and Narmeen Fatimah Oozeer and Naomi Saphra and Or David Shafran and Adi Simhi and Robert Trager and Shriyash Kaustubh Upadhyay and Ziyu Yao and Yu Zhao and Shay B. Cohen and Mor Geva and Yoshua Bengio and Stella Biderman and Hassan Sajjad},
      year={2026},
      eprint={2611.08438},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2611.08438},
}