Contents
Hash functions map data of arbitrary length to fixed-size values. The goal is to ensure that distinct inputs map to distinct outputs, except with very small probability over the randomness of a secret key used by the hash function. This property ensures we can build fast hash tables where every data point doesn’t collide in the same bucket.1
Hashing needs to be fast. xxHash boasts 60 GB/s, or basically as fast as you can read memory. Such bulk hashing is useful for file synchronisation or data integrity checking. Many popular hashes like komihash, a5hash, HighwayHash, SpookyHash, aHash, and t1ha2 are willing to trade quality, at least for adversarial inputs, for more speed.
This used to be fine. Many use cases of hashes are low risk, and it’s not worth it for attackers to do expensive cryptanalysis for inputs that make the hashes collide much more often than average. Still, most hashes try to be somewhat robust, to prevent accidentally quadratic slowdowns in algorithms and DoS attacks.
The best hashes give proofs that any pair of inputs collide with low probability. This is something unique in a world of cryptography that nobody can prove is actually secure. Let’s say a hash is b-bit universal if inputs of length L collide with probability at most L · 2−b for all L. Sometimes the dependency on L is worse, but it’s (provably) never better.2 The question becomes: What is the fastest possible hash that’s b-bit universal for some desired b?
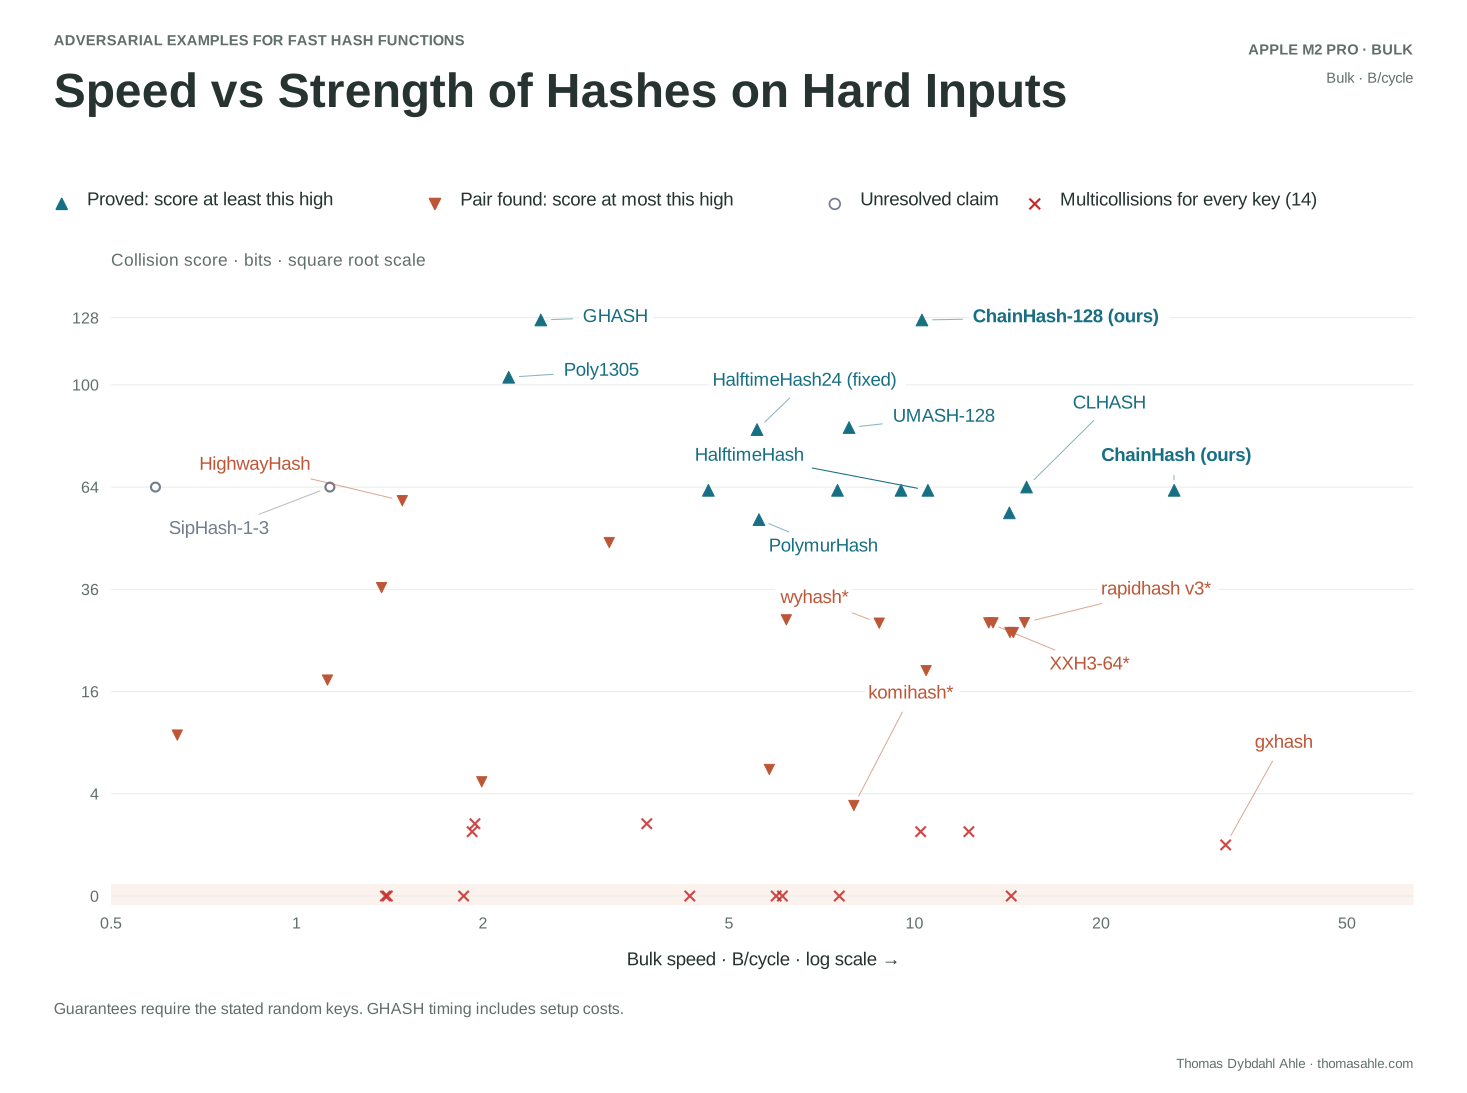
I was able to use Claude Fable to analyse a broad selection of popular hashes from SMhasher—a large project to empirically test statistical properties of hashes. It found that most of them have inputs on which they perform terribly—at least 20 bits below expectation. A few hashes have published proofs, and Fable was able to find mistakes in some and verify others in Lean. Click on any dot in the chart to read the full analysis.
Collision score bounds versus bulk speed. Speed is logarithmic. Score uses square-root spacing to give low scores more room; tick labels show the original bit values. Solid teal circles are proved lower guarantees; hollow circles are unresolved claims. Rust diamonds are witness upper caps; crosses mark every-seed pairs. Labels identify selected landmarks; every plotted variant is available in the hash selector.
Tab to a point and use arrow keys, Home or End to move between points. Enter or Space opens its profile. Escape closes it. Tap a point or its label on touch screens.
Select a hash, or tap a point or label.
Figure 1. Fast implementations can have very different collision guarantees. Solid dots show what a proof guarantees; rust marks show limits exposed by specific pairs. The guarantee and the speed measurement may use different key setups—open a profile for those assumptions.
Full data table · Data and provenance · Timing reproduction · Hash profiles
How to read the bounds and benchmarks
On the speed axis, equal distances represent equal ratios: moving from 1 to 2 bytes per cycle takes the same space as moving from 10 to 20. The vertical axis uses square-root spacing to give low collision scores more room. Zero stays visible, and all tick labels and profile values show the original scores in bits. The score is itself logarithmic in the collision bound; see its definition.
Solid teal circles give proved minimum scores. Hollow circles show unproved claims. Rust diamonds cap the score using a specific pair of distinct messages that collide; crosses identify pairs that collide for every seed. An asterisk means the cap uses a sampled rate. Finding no worse pair does not prove that none exists, so these caps are not a ranking of safety. A cross can sit above zero because the score adjusts for message length. All plotted variants are available in the selector, including the four HalftimeHash styles, which each return 64 bits.
The separate historical 32-byte pair A gave 9, 12, 11 and 11 collisions per 230 keys in wyhash, rapidhash v1, rapidhash v3 and XXH3-64. The selected XXH3-64 pair has a different measured rate: about 2^-21.58 of secrets (6868 / 5·2^32, pooled over two independent programs). Search effort was unequal; these witness caps do not rank hashes. Current pair and count provenance.
Speed is measured on 256 KiB messages, regardless of the length of the colliding pair. “B/cycle” means bytes processed per reported timer cycle; larger is faster. The M2, Xeon and EPYC timers use different cycle conventions (a calibrated clock on M2, TSC ticks at 2.9 GHz on Xeon and 2.6 GHz on EPYC), so compare hashes on the same host. The AMD EPYC 9R14 (Zen 4, 16 cores) tab reruns every timed row with the public timing reproduction: GCC 11.5 at -O3 -march=native, pinned to CPUs 8–15 at nice 10, taking the higher bulk and the lower short-input result of two complete passes, as on the Xeon. Its cores boost to 3.66 GHz, so there 1 B/cycle is 2.6 GB/s (records). The separate short-input measurements use 1–31 bytes. Foldhash uses a verified port with control measurements. GHASH is timed through OpenSSL’s GMAC interface, including setup costs. The benchmark protocol records the timers, repeated runs and calibration details.
Both published UMASH headline bounds are now proved by different routes: the implemented mod-8p accumulator and the C fingerprint’s two independent multipliers. The solid points show 56.18 and 83.99 bits (about 84 on L ≤ 246 words), for ideal full keys, a fixed seed and full C outputs. Key derivation, per-call seeds and masked outputs are outside these theorems; the paper’s 162/q projection step remains unvalidated. The four 64-bit HalftimeHash styles have a corrected 63-bit bound under the stated execution assumptions and length limits. The original advanced 24-byte function was refuted; HalftimeHash24 is plotted with its repaired encoder. ChainHash is one 64-bit function on all three hosts: 28.25 B/cycle on Xeon, 30.15 on M2 and 35.09 on EPYC, with a machine-checked 63.0-bit guarantee from 64 uniformly random key bytes. ChainHash-128 is the 128-bit function, again one function on all three hosts: 14.90 B/cycle on Xeon, 16.85 on M2 and 19.32 on EPYC, with a machine-checked 127-bit guarantee from 128 random key bytes. SipHash-1-3 and SipHash-2-4 are plotted as unresolved claims at their 64-bit output width. This audit supplies neither a proof nor a counterexample for these SipHash bounds. The cited 2014 analysis reports collision characteristics of 2-167 for SipHash-1-x and 2-236.3 for SipHash-2-4 (Dobraunig, Mendel and Schläffer, 2014), and our own search sees nothing above 2-26.4 per pair. Some historical collision examples have no matching timing, so they are absent from the chart. See the proof notes for the distinctions.
The main takeaways:
- AI changes the threat model: Software that used to be secure mostly from obscurity is now easy to break. If you can get provably correct software, take it.
- Provable hashes are just as fast as heuristic hashes. On Intel Xeon and AMD EPYC the fastest hash measured has a proof, and on Apple M2 Pro a proven hash is second only to gxhash, which has key-free collisions.
- Proofs of correctness are good, but verified Lean proofs are better. Not everything published is audited equally well, and we found multiple gaps, some of which could be fixed, and others that required code changes.
All the findings were disclosed upstream to maintainers before the publication of this blog post. You can read the maintainers’ replies in the discussions for xxHash, komihash, MuseAir, and foldhash. The consenus was that only true multicollision attacks, where a large set of inputs all collide with high probability are worth fixing. Universal hashing protects against that, but in principle a hash could be robust to multicollisions and not be universal.
That's a fair position, in particular since changing the hash is hard to do backwards compatibly. However, for this blog post we focus on provable guarantees, and the discovered collisions prove that the heuristic hashes are not just universal hashes that haven't been proven correct yet. And we also did find flooding-grade key-free multicollisions for many hashes.3
Hopefully this work will inspire research into even faster provable hashes. Many of the “exploits” used similar bad patterns repeated across many hash families. Hopefully the knee-jerk reaction is not just switching everything to “cryptographically secure” hashes like SHA or using AES native instructions. As we have shown, provably secure hashes are plentiful and fast.
If anyone has issues with the above presentation, or would like me to add/update/remove any particular hash, please contact me on Twitter.
Below follows an appendix with the in-depth analysis of each hash. Be warned that it contains AI slop, and I can’t guarantee everything is correct. I only trust the concrete examples found and measured.