— 1. The Hardy-Littlewood maximal inequality —
We work in Euclidean space  with Lebesgue measure; we write
 instead of
 for the Lebesgue measure of a set
 . For any
 and
 let
 denote the open ball of radius
 centred at
 . Thus for instance
 . For any
 , we use
 to denote the dilate of
 around its centre by
 .
For any , we define the averaging operators  on for any locally integrable
 by

It is not hard to see that these averages are well-defined, and are even continuous functions, for locally integrable .
One can view as an averaging operator

From Schur’s test or Young’s inequality (or Minkowski’s inequality) we know that these are contractions on every  ,
 :

Thus the averages  are uniformly bounded in size as varies. The fundamental Hardy-Littlewood maximal inequality asserts, roughly speaking, that they are also uniformly bounded in shape:
Proposition 1 (Hardy-Littlewood maximal inequality) We have the the strong-type  inequality

for all  and any
 , and also the weak-type
 inequality

for any  .
The sublinear operator

is known as the Hardy-Littlewood maximal operator. It is easy to see that the above proposition is equivalent to the assertion that the Hardy-Littlewood maximal operator is weak-type and strong-type for all . Note that it is not strong-type ; indeed, if is any non-trivial function, then we easily verify the pointwise bound  , which ensures that
 is not in
 . (Here we use the “Japanese bracket” notation
 , as a smoothed out version of the absolute value function
 .)
Exercise 2 Explain why  is not of strong or weak type
 for any
 .
As this proposition is so fundamental we shall give several proofs of it.
— 2. First proof —
We begin with the classical proof, starting with some standard qualitative reductions. Firstly we may easily reduce to being non-negative. A monotone convergence argument also lets us restrict to functions which are bounded and have compact support. (At this point one may object that might not be measurable, but one can use dominated convergence to restrict to be (say) rational, at which point measurability is clear.) Also, is continuous in , so we may restrict to a countable dense set (such as the positive rationals); another monotone convergence argument then lets us restrict to a finite set. Of course, our bounds need to be uniform in this set, as well as being uniform in the boundedness and support of .
It is obvious that is bounded on  (indeed, it is a contraction on this space). So it suffices by Marcinkiewicz interpolation to prove the weak-type inequality; by homogeneity (and the preceding reductions) it thus suffices to show that

for any non-negative bounded compactly supported , where we are implicitly restricting to a finite set.
Let us denote the set on the left-hand side by ; our hypotheses on and easily ensure that is a compact set (alternatively, one can work with the uncountable sup  , but instead replace by an arbitrary compact subset
 of itself, and then take suprema in at the end, noting that Lebesgue measure is a
 -finite Radon measure). By construction, we thus see that for any
 there exists a radius
 such that is locally large compared to the ball
 :

On the other hand, what we want to show is that is globally large compared to :

Since the compact set is covered by the balls , and hence by finitely many of these balls, things look quite promising. However, there is one remaining issue, which is that these balls could overlap quite heavily, preventing us from summing (1) to get (2). Fortunately there is a very simple algorithm which extracts out from any collection of overlapping balls, a collection of non-overlapping balls which manages to capture a significant fraction of the original collection in measure:
Lemma 3 (Wiener’s Vitali-type covering lemma) Let  be a finite collection of balls. Then there is a subcollection
 of disjoint balls such that

Proof: We can order in decreasing order of size. Now we select the disjoint balls  by the greedy algorithm, picking the largest balls we can at each stage. Namely, for
 we choose
 to be the first ball which is disjoint from all previously selected balls
 (thus for instance
 must equal
 ), until we run out of balls. Clearly this gives us a family of disjoint balls. Now observe from construction that each ball
 in the original collection is either a ball in the subcollection, or else intersects a ball in the subcollection of equal or larger radius. In either case we see from the triangle inequality that is contained in
 . In other words,

and so

and the claim follows. 
From the covering lemma it is easy to conclude (2). Indeed, since is covered by finitely many of the balls , the covering lemma gives us finitely many disjoint balls  ,
 such that

and then on summing (1) we get (2) (with an explicit constant of  ).
Remark 4 Under mild assumptions one can generalise the covering lemma to infinite families of balls without difficulty. One can also replace balls by similar objects, such as cubes; the main property that one needs is that if two such objects overlap, then the smaller one is contained in some dilate of the larger. This is a fairly general property, and for instance holds for metric balls on a measure space with some doubling property  , but it fails for very thin or eccentric sets such as long tubes, rectangles, annuli, etc. Indeed, understanding the maximal operator for these more geometrically complicated objects is still a major challenge in harmonic analysis, leading to important conjectures such as the Kakeya conjecture, which remains open in higher dimensions despite recent progress.
Exercise 5 (Baby Besicovitch covering lemma) Let  be a collection of intervals on the real line. Show that there exist a subcollection
 such that
 , and such that every point
 belongs to at most
 of the intervals
 . What is the best explicit bound for you can get?
Exercise 6 Show that if  is supported on
 , then

Exercise 7 For any locally integrable  , let
 denote the rectangular maximal function

where  ranges over all rectangles with sides parallel to the coordinate axes which contain . Show that
 is bounded on
 for all . (Hint: prove by induction, controlling the
 -dimensional rectangular maximal function by the
 -dimensional “horizontal” rectangular maximal function, applied to a one-dimensional “vertical” maximal function. A certain amount of application of the Fubini-Tonelli theorem may be needed.) Show by example that is not of weak-type in dimensions
 .
Exercise 8 Let  ,
 , and let be locally integrable on .
Exercise 9 Let , and let  be a ball such that
 at every point of . Show that
 at every point of
 .
— 3. Second proof —
Let us now give a slightly different proof of the above inequality, replacing balls by the slightly simpler structure of dyadic cubes.
Definition 10 (Dyadic cube) A dyadic cube in of generation  is a set of the form
![\displaystyle Q = Q_{n,k} = 2^n (k + [0,1)^d) = \{ 2^n (k+x): x \in [0,1)^d \}](https://s0.wp.com/latex.php?latex=%5Cdisplaystyle++Q+%3D+Q_%7Bn%2Ck%7D+%3D+2%5En+%28k+%2B+%5B0%2C1%29%5Ed%29+%3D+%5C%7B+2%5En+%28k%2Bx%29%3A+x+%5Cin+%5B0%2C1%29%5Ed+%5C%7D&bg=ffffff&fg=000000&s=0&c=20201002)
where is an integer and  .
The crucial property of dyadic cubes is the nesting property: if two dyadic cubes overlap, then one must contain the other. This leads to
Lemma 11 (Dyadic Vitali-type covering lemma) Let  be a finite collection of dyadic cubes. Then there is a subcollection
 of disjoint cubes such that

Proof: Take the  to be the maximal dyadic cubes in – the cubes which are not contained in any other cubes in this collection. The nesting property then ensures that they are disjoint and cover all of between them.
If we then define the dyadic maximal function

where  ranges over the dyadic cubes which contain , then the same argument as before then gives the dyadic Hardy-Littlewood maximal inequality

(with no constant loss whatsoever!) which then leads via Marcinkiewicz interpolation to

for .
We can rewrite the dyadic maximal inequality in another way. Let  be the -algebra generated by the dyadic cubes of generation , then

where is the unique dyadic cube of generation which contains . The dyadic Hardy-Littlewood maximal inequality is then equivalent to the assertion that

and thus

for .
Observe that if  , then there is a ball centred at which contains of comparable volume:
 . Because of this, one easily obtains the pointwise inequality

and so the dyadic inequality follows (up to constants) from the non-dyadic one. The converse pointwise inequality is not true (test it with  and
 , for instance). However, a slightly modification of this inequality is true, thanks to the
 -translation trick that dates back to de la Vallée Poussin, though later rediscovered by harmonic analysts such as Okikiolu. We first explain this trick in the context of the unit interval .
Lemma 12 Let  be a (non-dyadic) interval. Then there exists an interval
 which is either a dyadic interval, or a dyadic interval translated by , such that
 and
 .
The only significance of is that its binary digit expansion oscillates between  and . Note that the claim is false without the shifts; consider for instance the interval
 for some very small
 , which straddles a certain “discontinuity” in the standard dyadic mesh. The point is that the dyadic mesh and the -translate of the dyadic mesh do not share any discontinuities.
Exercise 13 Prove the above lemma.
For intervals larger than , a shift by is not enough; consider for instance what happens to the interval  . Instead, we have to shift by
 , which of course does not make sense as a real number. However, it does make sense in some formal
 -adic sense (as the doubly infinite binary string
 ) which is good enough to define shifted dyadic meshes.
Definition 14 (Dyadic meshes) We define  to be the collection of all dyadic intervals in
 . We define
 to be the collection of all intervals of the form
 , where
 is a dyadic interval at some generation and
 is any integer greater than or equal to (note that the exact choice of is irrelevant). If
 , we let
 be the collection of cubes formed by the Cartesian product of intervals from
 .
By modifying the above lemma one then quickly deduces
Lemma 15 Let  be a ball. Then there exists
 and a shifted dyadic cube
 such that
 and
 .
This in turn leads to the pointwise inequality bounding the dyadic maximal function by the ordinary one:

where  is the shifted dyadic maximal function

A routine modification of the proof of the dyadic maximal inequality (or translating this inequality by  and taking limits as
 ) shows that each of the are individually of weak-type , and bounded on for . Since there are only
 many choices of
 , we can then deduce the usual Hardy-Littlewood maximal inequality from the dyadic one.
Remark 16 What is going on here is that there are two ways to view the real line . One is the “Euclidean” way, with the usual group structure and metric. The other is the “Walsh” or “dyadic” way, in which we identify with the Cantor group 
via the binary representation,  (identifying
 with
 , and ignoring the measure zero sets of terminating decimals where the binary representation is not unique). The group structure is now the one inherited from the Cantor group; in the binary representation, the Cantor-Walsh addition law
 is the same as ordinary addition
 but where we neglect to carry bits. The usual archimedean metric
 is replaced by the non-archimedean metric
 , defined by

With this metric, the dyadic intervals become the metric balls.
Exercise 17 (Hardy-Littlewood maximal inequality for filtrations) Let  be a measure space, and let be an increasing sequence of -finite -algebras in
 (thus
 for all
 ). Show that

and hence 
for all and all -measurable for which the right-hand side is finite. (Hint: use monotone convergence to reduce to finitely many . Reduce further to the case when the are countably generated (by using the level sets of the  for rational intervals). Reduce further still to the case where the are finitely generated, i.e. finite. Now adapt the dyadic argument. There are also simpler arguments which do not require all of these reductions.) This inequality is also known as Doob’s inequality, and implies in particular that
 converges pointwise a.e. to
 whenever
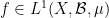 .
Exercise 18 (Relationship between dyadic and non-dyadic Hardy-Littlewood maximal inequalities) Let be locally integrable. Establish the pointwise bound 
for some  depending only on .
— 4. Third proof —
In the above arguments we obtained bounds by first proving weak bounds and then interpolating. It is natural to ask whether such bounds can be obtained directly. The answer is yes, but it is surprisingly more difficult to do so. Let us give two such approaches, a Bellman function approach and a  method approach, which are themselves powerful methods which apply to many other problems as well.
We begin with the Bellman function approach. This method works primarily for dyadic model operators, such as  , though it can also work for very geometric operators as well (using geometric averaging operators such as heat kernels in place of the dyadic averaging operators). For simplicity let us just work in one dimension (though it is possible to use rearrangement and space-filling curves to deduce the higher-dimensional case from the one-dimensional case), and consider the task of establishing

for some fixed (such as  ).
The idea is to work by induction on scales – in other words, to induct on the number of generations. To do this we need a “base case”, so we perform some qualitative reductions. Fix  (the case
 being trivial). By a monotone convergence argument we may restrict attention only to those intervals of length larger than
 , so long as our estimates are uniform in . By rescaling (replacing
 by
 ) we can reduce to the case
 . Let us write
 for the dyadic maximal function restricted to intervals of length at least . By a monotone convergence argument (there is a slight problem because we cannot represent as the monotone limit of dyadic intervals; however we can do this for
 and
 separately, and then add up, noting that the dyadic maximal function is localised to each of these half-lines, e.g. if is supported on then so is
 ) we can also assume that is supported on a dyadic interval of some length
 , and also we may restrict to that interval. We can also take to be non-negative. Our task is now to show that there exists a constant
 such that

whenever  . (We make the constant explicit here because of the induction that we shall shortly use.) Of course the point is that is independent of , , and .
We make a small but useful remark: once and are both restricted to , the only dyadic intervals which are relevant in the definition of are those which are contained in (including itself). Intervals which are disjoint from play no role, and intervals which contain give a worse average than that arising from itself.
The idea is to prove this by induction on the generation of . Our first approach will not quite work, but a subtle modification of it will.
When  the claim is trivial (as long as
 ), because for a dyadic interval of generation and
 we have

Now let  , and let us see whether we can deduce the case from the
 case without causing any deterioration in the constant . (Using various applications of the triangle inequality it is not hard to get from to , replacing with something worse like
 , but this is not going to iterate into something independent of .)
Let us split the dyadic interval of generation into two “children”  of generation (
 and stand for left and right). This also causes a split
 . By induction hypothesis we have

and we also trivially have

Now if we were lucky enough to have the pointwise estimates

and similarly for  , then we could simply average the two induction hypotheses and be done. However, this is not quite the case: the correct relationship between the maximal function of and of
 is that

and similarly when  . This causes a problem. If we estimate the max by a sum and use triangle type inequalities, we will eventually get a bound such as (4) but with replaced by
 , which is not acceptable for iteration purposes. So we have to somehow keep the max with the constant
 with us in the induction argument. This eventually forces us to change the induction hypothesis (4), replacing the left-hand side
 by the more general
 for some arbitrary
 . Given our knowledge that max and addition are comparable up to constants, we know that (4) is equivalent to the estimate

up to changes in the constant . But perhaps this estimate has a better chance of being proven by induction. The key recursive inequality is now that

and similarly for  . One can try the induction strategy again, but one sees that the inability to efficiently control in terms of
 and
 is a serious problem. (Hölder’s inequality of course gives bounded by
 , but this turns out to be insufficient.) Because of this, we have no choice but to also throw in the average
 into the induction hypothesis somehow.
Let us formalise this as follows. Given any parameters  , let
 denote the cost function

where is understood to be nonnegative and supported on a dyadic interval of generation . Note that Hölder’s inequality shows that  when
 , since in this case the supremum is over an empty set. Our task is thus to show that

uniformly in and in  . As we said earlier, the parameter is not obviously necessary yet, but will become so when we try to perform the induction, as it tracks a certain finer property of the function which needs to be managed in order to prevent the constants from blowing up. The base case when
 is again trivial; the issue is to pass from fine scales to coarse scales without destroying the boundedness of implicit constant.
Now the recursive inequality can be turned into an inequality for  . Suppose that attains the supremum (or comes within an epsilon of it). We have

for some  . Similarly

for some  . Then we have

for  , and similarly for ; by construction we thus have

Taking suprema, we obtain the recursive inequality

(In fact, this is an equality – why?) On the other hand,  can be computed directly as

when  , and
 otherwise. In principle, this gives us a complete description of , which should allow one to determine the truth or falsity of (5). Note that we have reduced the problem from one involving an unknown function (which has infinitely many degrees of freedom) to one involving just three scalar parameters , except that we have a different cost function at every scale. However, suppose that we can devise a Bellman function
 with the property that

for all , and such that  obeys the inequality

whenever and . Then an induction will show that

for all (and note that the implied constants here are uniform in ), thus proving (5).
Thus the whole task is reduced to a freshman calculus problem, namely to find a function of three variables obeying the bounds (6) and (7). The difficulty of course, is to find the function; verifying the properties is then routine. This “hunt for a Bellman function” is surprisingly subtle, and requires one to choose a surprisingly non-trivial choice of .
The condition (7) resembles a concavity condition, and so it is natural to try to find choices which are concave in some of the variables. An initial candidate is the function  , which certainly obeys (7) and the upper bound of (6) (and which, in fact, ultimately corresponds to the original estimate (4) before we threw in the other parameters
 ); unfortunately it does not obey the lower bound in (6), in the case where is large compared with and
 . So we need to tweak this function somewhat. The first step is to improve the concavity by exploiting the fact that the function only needs to be non-trivial on the region . One can exploit this by using the candidate function
 (say). This still obeys (7), but now with a bit of a gain when
 is large due to the strict concavity of
 . (One cannot play similar games with the
 parameter as the upper and lower bounds in (6) force linear-type behaviour in .) But we still have not fixed the problem that is not as large as
 when is large. The solution is to use the Bellman function

where is a concave function which is positive for small and is equal to  for
 (say). Thus we have
 when
 , but becomes as large as
 or so when exceeds
 . This lets us verify both sides of (6), so one only needs to verify (7). If
 then the claim follows from the concavity of
 (which does not depend on ); when
 the claim follows from the concavity of in the variable and in the variable.
Remark 19 Bellman function methods are in principle the sharpest and most powerful technique to prove estimates. However they are restricted to dyadic settings (or very geometric continuous settings), and are very delicate due to the need to establish very subtle concavity properties.
— 5. Fourth proof —
Finally, we present the “ approach” to the Hardy-Littlewood maximal inequality. This approach works for both the dyadic and non-dyadic maximal functions, but is restricted to establishing  boundedness (this is a fundamental limitation of the method, that at least one of the spaces involved has to be a Hilbert space). The basic idea is rather than prove a boundedness result directly on the maximal operator (i.e. an estimate of the form
 ), we prove an estimate on the square of this operator (roughly speaking, we prove an estimate of the form
 ). This is an example of a powerful strategy to understand an operator by raising it to a higher power, and hoping to exploit some self-cancellation. Note that we do not have to cancel the entire power (which would roughly speaking correspond to proving a bound of the form
 ); any nontrivial cancellation at all is exploitable.
Let us work with the non-dyadic maximal function, thus we wish to show that

for all non-negative . As before we may restrict to range in a finite set  , provided our bounds are independent of the choice of . Note that because each is already bounded on , the maximal operator is now already bounded with some finite operator norm. Let denote the optimal such norm, thus is the best constant for which

We know is finite; our objective is to obtain the bound  . We will do this by controlling in a nontrivial way in terms of itself, and in particular by controlling the “square” of the maximal operator by the maximal operator.
Observe that (8) is equivalent to the uniform linearised estimate

for all measurable functions  .
Let us fix the function . Then we can define the linear operator  by

We can thus interpret as the largest operator norm of the :

To compute this operator norm we make the following observation.
Lemma 20 ( identity) Let  be a continuous map from a Hilbert space to a normed vector space, and let
 be its adjoint. Then

Proof: The first identity is just duality. Then we have

which gives the lower bound in the second identity. For the upper bound, observe that for any  that

taking square roots gives the upper bound as desired.
In light of this identity we know that

Now let us take a look at what  is. Observe that is an integral operator with kernel

Thus the adjoint is given by

and then is given by

Note that the  integral can be computed fairly easily. First we observe that the integral vanishes unless
 , and in the latter case it enjoys a bound of
 . Also,
 and
 . Putting this together we see that

It is natural to split this integral into the regions  and
 , leading to the bound

Comparing this with the formulae for and  , we obtain the interesting pointwise inequality

where  is the function
 , of course. On the other hand, a scaling argument gives

and hence we conclude from the triangle inequality that

taking suprema in we conclude that  , and hence (since is known to be finite)
 , and the claim follows.
The Hardy-Littlewood maximal function directly bounds averages on balls and cubes, but it also controls several other types of averages as well. For instance, we have the pointwise inequality

for any locally integrable , any , and any  ; this can be achieved by dividing the integral into dyadic shells
 for
 , as well as the ball
 , and we leave the computation to the reader.
The proof of the Hardy-Littlewood maximal inequality extends to the more general setting of spaces of homogeneous type (which is similar, but different from, the notion of a homogeneous space). These are measure spaces with a metric , such that the open balls are measurable with positive finite measure, and that one has the doubling property

for any  . Then the Vitali-type covering lemma extends without difficulty to this setting and yields the maximal inequality

and hence

for any .
In particular we obtain the discrete inequality

(which we need in our applications to ergodic theory below), while on the torus  with the usual Lebesgue measure we have

for (which we will need for our applications to complex analysis).
Remark 21 One could try playing with  instead of here, but that turns out to not work very well. The problem is that the linearised maximal operator is only well-behaved in one variable, and the method manages to play the two well-behaved variables against each other; going the other way one achieves no obvious cancellation.
— 6. Some consequences of the maximal inequality —
The Hardy-Littlewood maximal inequality is the underlying quantitative estimate which powers many qualitative pointwise convergence results. A basic example is
Theorem 22 (Lebesgue differentiation theorem) Let be locally integrable. Then we have the pointwise convergence 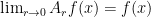 for almost every . In fact we have the stronger estimate

for almost every .
Before we prove the theorem, let us make some remarks. Firstly, from the identity

and the triangle inequality it is clear that the second estimate implies the first. Secondly, observe that is continuous at if and only if the worst-case local fluctuation goes to zero

Thus the differentiation theorem is asserting that locally integrable functions are almost everywhere continuous on the average, in that the average-case local fluctuation goes to zero. This is a manifestation of one of Littlewood’s three principles, namely that measurable functions are almost continuous. If is such that (12) holds, we say that is a Lebesgue point of , thus for locally integrable , almost every point is a Lebesgue point.
Proof: It suffices to establish the result for constrained to a large ball  , where
 is arbitrary. The claim is obvious if vanishes on
 , so by linearity we may assume that is supported on ; in particular now lies in
 . Thus it suffices to establish the claim when .
By the preceding discussion we already know that the claim is true for the continuous compactly supported functions  , which is a dense subclass of . To pass from the dense subclass to the full class we use the Hardy-Littlewood maximal inequality now lets us reduce matters to verifying the claim on a dense subset of . To see this, suppose that we already have proven the claim on a dense class. Then, given any we can write as the limit in
 of a sequence
 in this dense class; by refining these sequence to make the convergence sufficiently fast (e.g.
 ) and using Markov’s inequality and the Borel–Cantelli lemma, we can also ensure that converges to pointwise almost everywhere. Now from the Hardy-Littlewood maximal inequality, we know that
 converges to zero, thus
 converges to zero in measure. By the triangle inequality this implies that
 converges in measure also. Thus (again passing to a rapidly converging subsequence as necessary) we see that
 converges to zero for almost every . This uniform-in- convergence lets one deduce the convergence of from the convergence of
 .
Finally, by taking a dense class such as the Schwartz class (or even the continuous functions in ) we easily verify the convergence.
Remark 23 Because the proof used a density argument, it offers no quantitative rate for the speed of convergence. Indeed the convergence can be arbitrarily slow; this is ultimately due to the implicit hypothesis that is measurable, which is itself a qualitative assumption that offers no explicit bounds. More quantitative versions of measurability, e.g. quantifying the extent to which a measurable set can be approximated by elementary sets, can lead to more explicit bounds.
Consider for instance the function  defined by
 when
 and the integer part of
 is even, and
 otherwise, where is a large integer. Then we see that for ,
 will stay close to
 for quite a while (basically for all
 ), and only at scales
 or less will it begin to “decide” to converge to either or . Modifying this type of example (e.g. by a “Weierstrass example” formed by summing together a geometrically decaying series of such oscillating functions, with going to infinity), one can concoct functions whose convergence of to is arbitrarily slow. (One can obtain quantitative rates by enforcing regularity conditions on the function, which essentially compactifies the space of functions that one is working with; we will see some examples of this later.)
Exercise 24 Let be a locally integrable function on . Call a point a Lebesgue point if there exists a number such that  . Show that almost every point is a Lebesgue point, and that is equal to almost everywhere.
Exercise 25 (Heat kernels) For any  and any for some , define the heat kernel
 by

Show that if and , then converges both pointwise and in norm to as  .
Now let us explore applications to ergodic theory. In particular we wish to investigate limits of the form

for various functions and various “shift operators”  .
Let us first look at an abstract setting, in which is a unitary operator on a Hilbert space.
Theorem 26 (Von Neumann ergodic theorem) Let  be a unitary operator on a Hilbert space. Then for any
 , the limit
 exists in the strong
 topology.
Proof: Let us first argue formally. We have

Formally, we have the geometric series formula

which looks like it converges to zero, unless  fails to be invertible; but on the other hand when

 is just , which of course converges to the identity. So we seem to have covered two extreme cases.
Now let us make the above argument rigorous. If is -invariant, thus  , then
 and it is clear that
 converges to . If on the other hand is a -difference,
 for some
 , then we verify the telescoping identity
 . Since unitary operators preserve the norm, we thus see from the triangle inequality that converges to zero. Also, since the averaging operators
 are uniformly bounded in (by the triangle inequality), we see that any strong limit of -differences also has the property that exists and equals zero.
To summarise so far, we have two closed subspaces of for which we know convergence. The first is  , the invariant space of ; here the limit converges to the identity. The other is
 , the closure of the -differences; here the limit conveges to zero. These two spaces turn out to be orthogonal complements. To see this, first observe that they are orthogonal: if , then
 by unitarity, and hence is orthogonal to every -difference
 and hence by continuity of inner product is orthogonal to . To show orthogonal complement, it then suffices to show that any vector orthogonal to is invariant. But then is orthogonal to
 :

We rewrite the left-hand side as

and on conjugating and subtracting we conclude that

and thus  as claimed.
Note that the above argument in fact shows the stronger claim that converges to the orthogonal projection of to  .
Now we move to a more specialised setting, that of a measure-preserving system.
Definition 27 (Measure-preserving system) A measure-preserving system  is a probability space (thus
 ) together with a bi-measurable bijection
 (thus and
 are both measurable) such that is measure-preserving, thus
 for all
 .
Example 28 (Circle shift) Let  be the standard circle with the usual Borel -algebra and Lebesgue measure, and let
 for some
 , which may be either rational or irrational.
Remark 29 Many of the results here hold under more relaxed assumptions on , but we will not attempt to optimise the hypotheses here.
The shift on the base space  ,
 , induces a shift on sets ,
 , and then also induces a map on measurable functions
 by
 . The use of is natural since it ensures that
 and
 .
Proposition 30 (Mean ergodic theorem) Let  be a measure-preserving system, and let
 for some . Then the sequence
 converges strongly in
 .
Proof: The operator is an isometry on , and so by the triangle inequality the averaging operators are uniformly bounded in . Thus it suffices to prove the claim for a dense subclass of ; we shall pick  . In this class, which is embedded into the Hilbert space
 , we already know from the von Neumann ergodic theorem (and the fact that is a unitary operator on ) that the averages are convergent in norm. But they are also uniformly bounded in . So the claim follows from the log-convexity of norms (for
 ) or by Hölder’s inequality and the finite measure of (for
 ).
Exercise 31 Show by example that the mean ergodic theorem fails for  and for .
Now we study the pointwise convergence problem. The key quantitative estimate needed is the following analogue of the Hardy-Littlewood maximal inequality.
Theorem 32 (Hardy-Littlewood maximal inequality for measure-preserving systems) Let be a measure-preserving system. Then we have 
and 
for all .
Proof: The claim is trivial when , so once again the task is to prove the pointwise estimate. By monotone convergence it suffices to show that

uniformly in  .
The idea is to lift up to a space where can be modeled by the integer shift  , at which point we can apply (10). Fix
 , and let
 be the finite set
 , endowed with the discrete -algebra and uniform measure, so that
 is a probability space. Inside this space we have
 , where
 . We define the function
 by

From (10) we have

for all  ; writing out what the
 norm means, and integrating in using Fubini’s theorem, we conclude

The right-hand side is just  . As for the left-hand side, observe that

and so on writing out the  norm we see that the left-hand side is comparable to

and the claim follows.
Remark 33 Note how a maximal inequality for the integers was “transferred” to a maximal inequality on arbitrary measure preserving systems. There are several abstract transference principles which generalise this type of phenomenon. In particular, the above argument is in fact a special case of the Calderón transference principle.
Now we can present the analogue of the Lebesgue differentiation theorem for measure-preserving systems.
Proposition 34 (Pointwise ergodic theorem) Let be a measure-preserving system, and let  . Then the sequence converges pointwise almost everywhere.
Proof: By repeating the argument in the Lebesgue differentiation theorem more or less verbatim (using the above maximal inequality in place of the Hardy-Littlewood inequality) it suffices to verify the claim for a dense subclass of  , such as . Since the norm controls the norm, it suffices to do so for a dense subclass of .
Now we repeat the proof of the von Neumann ergodic theorem. For the invariant part  of , the pointwise convergence is obvious. Also, for functions of the form with
 , the convergence is also obvious. But these functions are clearly dense in
 and hence in
 . Since this space and are orthogonal complements of , we thus have demonstrated convergence of a dense subclass of and thus of , as desired.
Remark 35 Notice how the strategy of establishing convergence splits into two independent parts – obtaining convergence on a dense subclass, and then establishing some harmonic analysis estimate to pass to the general case. This is not the only way to achieve convergence results. Later on we shall see a variation-norm approach which relies purely on harmonic analysis estimates to obtain convergence (foregoing the dense subclass). In the opposite direction, there are more dynamical approaches (which we do not cover here) which forego the harmonic analysis component of the argument, relying instead on analysing the dynamics of the measure-preserving system by other means (such as measure-theoretic or topological means). It is not fully understood to what extent these different techniques complement each other.
Exercise 36 Let be a measure-preserving system. Let  be the elements of which are -invariant (up to sets of measure zero, of course). Show that for any
 and , the averages converge in norm and pointwise almost everywhere to
 . In particular, when is ergodic (thus the only invariant sets have zero measure or full measure), conclude that converges pointwise and in norm to
 .
Exercise 37 (Poincare recurrence theorem) Let be a measure-preserving system, and let  be non-negative with
 . Show that
 for infinitely many .
By combining the Lebesgue differentiation theorem with the Radon-Nikodym theorem, one easily obtains
Theorem 38 (One-dimensional Radamacher differentiation theorem) If is Lipschitz, then it is differentiable almost everywhere, its derivative lies in  , and we have the fundamental theorem of calculus
 for all
 .
Proof: We may reduce to the case when is real. The Riemann-Stietjes measure  is easily seen to be absolutely continuous with respect to Lebesgue measure, and is thus of the form
 for some locally integrable
 , thus
 by the Radon-Nikodym theorem. The Lebesgue differentiation theorem then shows that
 exists and is equal to at every Lebesgue point of (see Q7), and the claim follows. (The boundedness of
 is clear from the Lipschitz nature of .)
Remark 39 There are other ways to prove this theorem that do not require Radon-Nikodym differentiation, which we shall encounter later.
This one-dimensional theorem implies a multi-dimensional analogue:
Theorem 40 (Radamacher differentiation theorem) If is Lipschitz, then is differentiable almost everywhere, thus for almost every there exists a vector  such that

Proof: For simplicity of notation we take  , although the general case is similar. Theorem 38 (and Fubini’s theorem) shows that the partial derivatives
 ,
 exist almost everywhere and are bounded. This gives us a candidate gradient
 defined almost everywhere. The remaining challenge is to show total differentiability. In other words, for any , we need to show that for almost every , we have

whenever  is sufficiently small depending on . Note that the control of the partial derivatives only achieve this when
 is a multiple of
 or
 .
Fix . We will need to make things slightly more quantitative. For any and  , let
 denote the set


Then the almost everywhere existence of  implies that the are measurable and increase to
 as
 (neglecting sets of measure zero). In particular, almost every point lies in infinitely many of the . Because of this, we know that almost every point is a horizontal and vertical Lebesgue point of and of
 for infinitely many . (We say that
 is a horizontal Lebesgue point of
 if
 as
 , and similarly define a vertical Lebesgue point of .) In particular, for almost every point there is an such that one lies in , and is a horizontal and vertical Lebesgue point of and of for . From this it is not hard to show (13) for a large density set of near (say of density
 ), basically by decomposing
 and using the Lebesgue point properties to ensure that
 is usually close to
 ; we omit the details. The remaining exceptional values of can then be dealt with by locating a nearby non-exceptional value of and using the Lipschitz property.
Exercise 41 (Fundamental theorem of calculus) Let be locally integrable, and let  (with the usual convention that
 ). Show that is differentiable at every Lebesgue point of , and that
 almost everywhere.
— 7.  functions —
Another classical application of the Hardy-Littlewood maximal function lies in obtaining a satisfactory theory of (complex) functions on the complex disk  for . (The theory for
 is more subtle and will not be dealt with here.)
Let  be a holomorphic function. From residue calculus we have

and

when  , and so on averaging, and noting that
 is the complex conjugate of
 when
 , we obtain

or in other words, if we set  to be the function
 , we have the reproducing formula

whenever  and
 is the Poisson kernel

The kernel  is clearly non-negative; applying the above identity to
 (or computing directly) we see also that has mass :

From Young’s inequality we thus obtain that for , the norm of is increasing on circles:

(Note that the case is just the maximum principle.) In particular, the quantity

always exists. We say that is an function if is analytic on  and the norm
 is finite. It is not hard to see that
 becomes a normed vector space (and that
 whenever
 ); a little more work shows that it is in fact complete.
Exercise 42 For any and  , define the Fourier coefficient
 of by the formula

Show that 
for every  and , and that

for every holomorphic on , and . Also show that  for all
 , and that

for all  . (Note that these identities can be proven either by complex analysis methods or by Fourier analysis methods; it is instructive to prove them both ways and compare results.)
The kernel can be easily verified to obey the bounds

This is enough to obtain the pointwise estimate

where

is the Hardy-Littlewood maximal function of . From last week’s notes we conclude that for any and  , that
 converges to in
 norm, and by modifying the proof of the Lebesgue differentiation theorem we also see that it converges pointwise almost everywhere.
The definition of strongly suggests (but does not immediately prove) that if lies in , then  should converge to some sort of limit
 as
 . This is indeed the case:
Theorem 43 Let  for . Then converges both in norm and pointwise almost everywhere to a limit
 .
Remark 44 The theorem fails for  , as can be seen by explicitly computing using the function
 . When , the pointwise almost everywhere claim is still true, but the convergence is not.
Proof: Let us first demonstrate weak convergence. For any  and
 , we observe that

where  is the inner product on (here we use the fact that is real and even). Since
 converges in norm to as
 , we thus see that
 converges to a limit as . Since
 converges in
 norm to as
 , we conclude (from Hölder’s inequality and the uniform bound on
 ) that
 also converges to a limit as , thus converges weakly. But as is reflexive, the closed unit ball is also weakly closed, and we conclude that converges weakly to for some , thus

for all  . Replacing by
 and using (14) we conclude

and hence (since converges to in norm)

This is for all , thus we have

Thus converges pointwise almost everywhere and in norm to .
Exercise 45 (Fatou’s theorem) Let for some , and let be as in Theorem 43. Show that for almost every  , we have

whenever  is a sequence of points converging to
 non-tangentially in the sense that
 is uniformly bounded away from
 . (Hint: first reduce to a fixed angle of non-tangentiality (e.g. all angles less than pi/2 – 1/n), and then build an appropriate “non-tangential maximal function”, formed by taking suprema over all points in a sector with apex and this fixed angle of non-tangentiality. Use the kernel bounds to bound this maximal function by the Hardy-Littlewood maximal operator.)
— 8. The Calderón-Zygmund decomposition —
For a function on an abstract measure space, and any threshold  one has the basic decomposition

into a “good”  piece (bounded by
 ), and a “bad” piece
 (larger than , but at least of small support). If for instance , then we have the bounds

for the good piece and

for the bad piece (the last inequality being Markov’s inequality). Thus both pieces inherit the bound of the whole, but enjoy an additional useful property. This type of decomposition underlies tools such as the layer cake decompositions and the real interpolation method.
For arbitrary measure spaces with no additional structure, this type of decomposition is about the best one can do to split into “good” and “bad” parts. But if has more structure – in particular some sort of metric or dyadic structure compatible with the measure – then one can do better, in particular one can select the bad piece  to be “locally oscillating” in a certain sense. This principle, which uses the same ideas that underlie the Hardy-Littlewood maximal inequality, is formalised in the Calderón-Zygmund decomposition, a fundamental tool in the Calderón-Zygmund theory of singular integrals.
To motivate the lemma let us first give a simple one-dimensional version.
Lemma 46 (Rising sun lemma) Let  be a bounded interval, and let
 be integrable, and let
 be such that
 . Then there exist an at most countable family
 of disjoint open intervals in such that
Proof: By subtracting from we may normalise  . We may take to be half-open
 . Define
 by
 . Then is a continuous function which starts at zero and ends up positive. Define a “maximal” version
 of by
 , then
 is continuous non-decreasing which starts at zero and ends up positive. Let
 , then
 is an open subset of , thus
 for some at most countable set of intervals
 . At the endpoints of each interval we have
 , while on the interior of these intervals is necessarily constant (why?). This gives the second desired property. For the first, one observes from Q7 that at almost every point where
 , we have differentiable with
 , which implies that
 , and the claim follows.
As a corollary we have
Corollary 47 (One-dimensional rising sun lemma) Let the hypotheses be as in the above lemma. Then we have a decomposition  , where
 is bounded above by with
 , and for each
 ,
 is supported in and has mean zero. Furthermore, if and is non-negative, then
 and
 .
Proof: We set  , and set equal to outside of
 and equal to inside
 . To prove the last two claims, we have

so on summing and using the non-negativity of

from which the former claim follows. Finally, from the definition of and the triangle inequality

which is the latter claim.
The proof of the rising sun lemma relies crucially on the ordered nature of the real line. For more general spaces, such as Euclidean spaces, it is preferable to use arguments that rely instead on metric or dyadic structure. We begin with a dyadic version.
Proposition 48 (Dyadic Calderón-Zygmund decomposition) Let and . Then there exists a decomposition  , where the “good” function obeys the bounds

ranges over a disjoint family  of dyadic cubes, and each
 is supported on , has mean zero, and has the bound

Furthermore, we have the inclusions 
In particular from (3) we have  .
Proof: The arguments here will closely resemble that used to prove (3). Let us say that a cube is bad if  , and good otherwise. Call a bad cube maximal if is bad, but no cube strictly containing is bad, and let be the collection of all maximal bad cubes, thus is a collection of disjoint dyadic cubes, and we also clearly have
 on each bad cube. From the hypothesis and monotone convergence we see that all cubes with sufficiently large side-length are automatically good. Thus every bad cube is contained in a maximal bad cube.
Now let be a maximal bad cube. The parent  of (i.e. the unique dyadic cube of twice the side-length containing ) is good, hence
 . Since
 , we conclude that
 . Now set

and

All the desired properties are then easily verified, except perhaps for the claim  . This claim is clear on each separate cube ; the only difficulty is to show that is bounded by
 outside of
 . But by construction we see that if
 and
 , then is good, and
 . On the other hand, the (dyadic version of the) Lebesgue differentiation theorem shows that
 converges to for almost every as
 . Thus
 for almost every such , and we are done.
Exercise 49 Let be the -algebra generated by the cubes in , and the Borel subsets of  . Show that
 .
Note that the total bad set is given by the level set  of the dyadic maximal function. This suggests an alternate approach to the Calderón-Zygmund decomposition, in which one starts by identifying the total bad set (in this case, ), and then decomposes it into cubes or balls. A prototype decomposition of this type is
Proposition 50 (Dyadic Whitney decomposition) Let  be an open set. Then there exists a decomposition
 , where ranges over a family of disjoint dyadic cubes, and for each in this family , the parent of is not contained in .
Proof: Define to be the set of all dyadic cubes in which are maximal with respect to set inclusion; the claim follows from the nesting property. (The condition is needed to ensure that every cube is contained in a maximal cube; the open-ness is to get every point of contained in at least one cube.)
The property that is not contained in implies the bounds

In many applications we need to complement the upper bound with a non-trivial lower bound. This can be done with a little more effort:
Proposition 51 (Whitney decomposition) Let  be an open set and let
 . Then there exists a decomposition , where ranges over a family of disjoint dyadic cubes, and for each in this family , we have
 .
Proof: Let  denote those dyadic cubes in such that

It is not hard to show that these cubes cover ; indeed, given any in , all one needs to do is to locate a cube containing with diameter between  and
 . The cubes are not disjoint; however if one lets
 be those cubes in which are maximal with respect to set inclusion, then the claim follows from the nesting property.
Note that if is large, the cubes in this above decomposition have the property that nearby cubes  (in the sense that
 ) have comparable diameter, thanks to the triangle inequality


Since every cube is contained in a ball of comparable radius (with constants depending on ), we then conclude
Proposition 52 (Whitney decomposition for balls) Let be an open set and let . Then one can cover by balls such that  , and such that each point in is contained in at most balls.
These decompositions can be used to prove some minor variants of the Calderón-Zygmund decomposition, which we will not describe in detail here.