How the test works
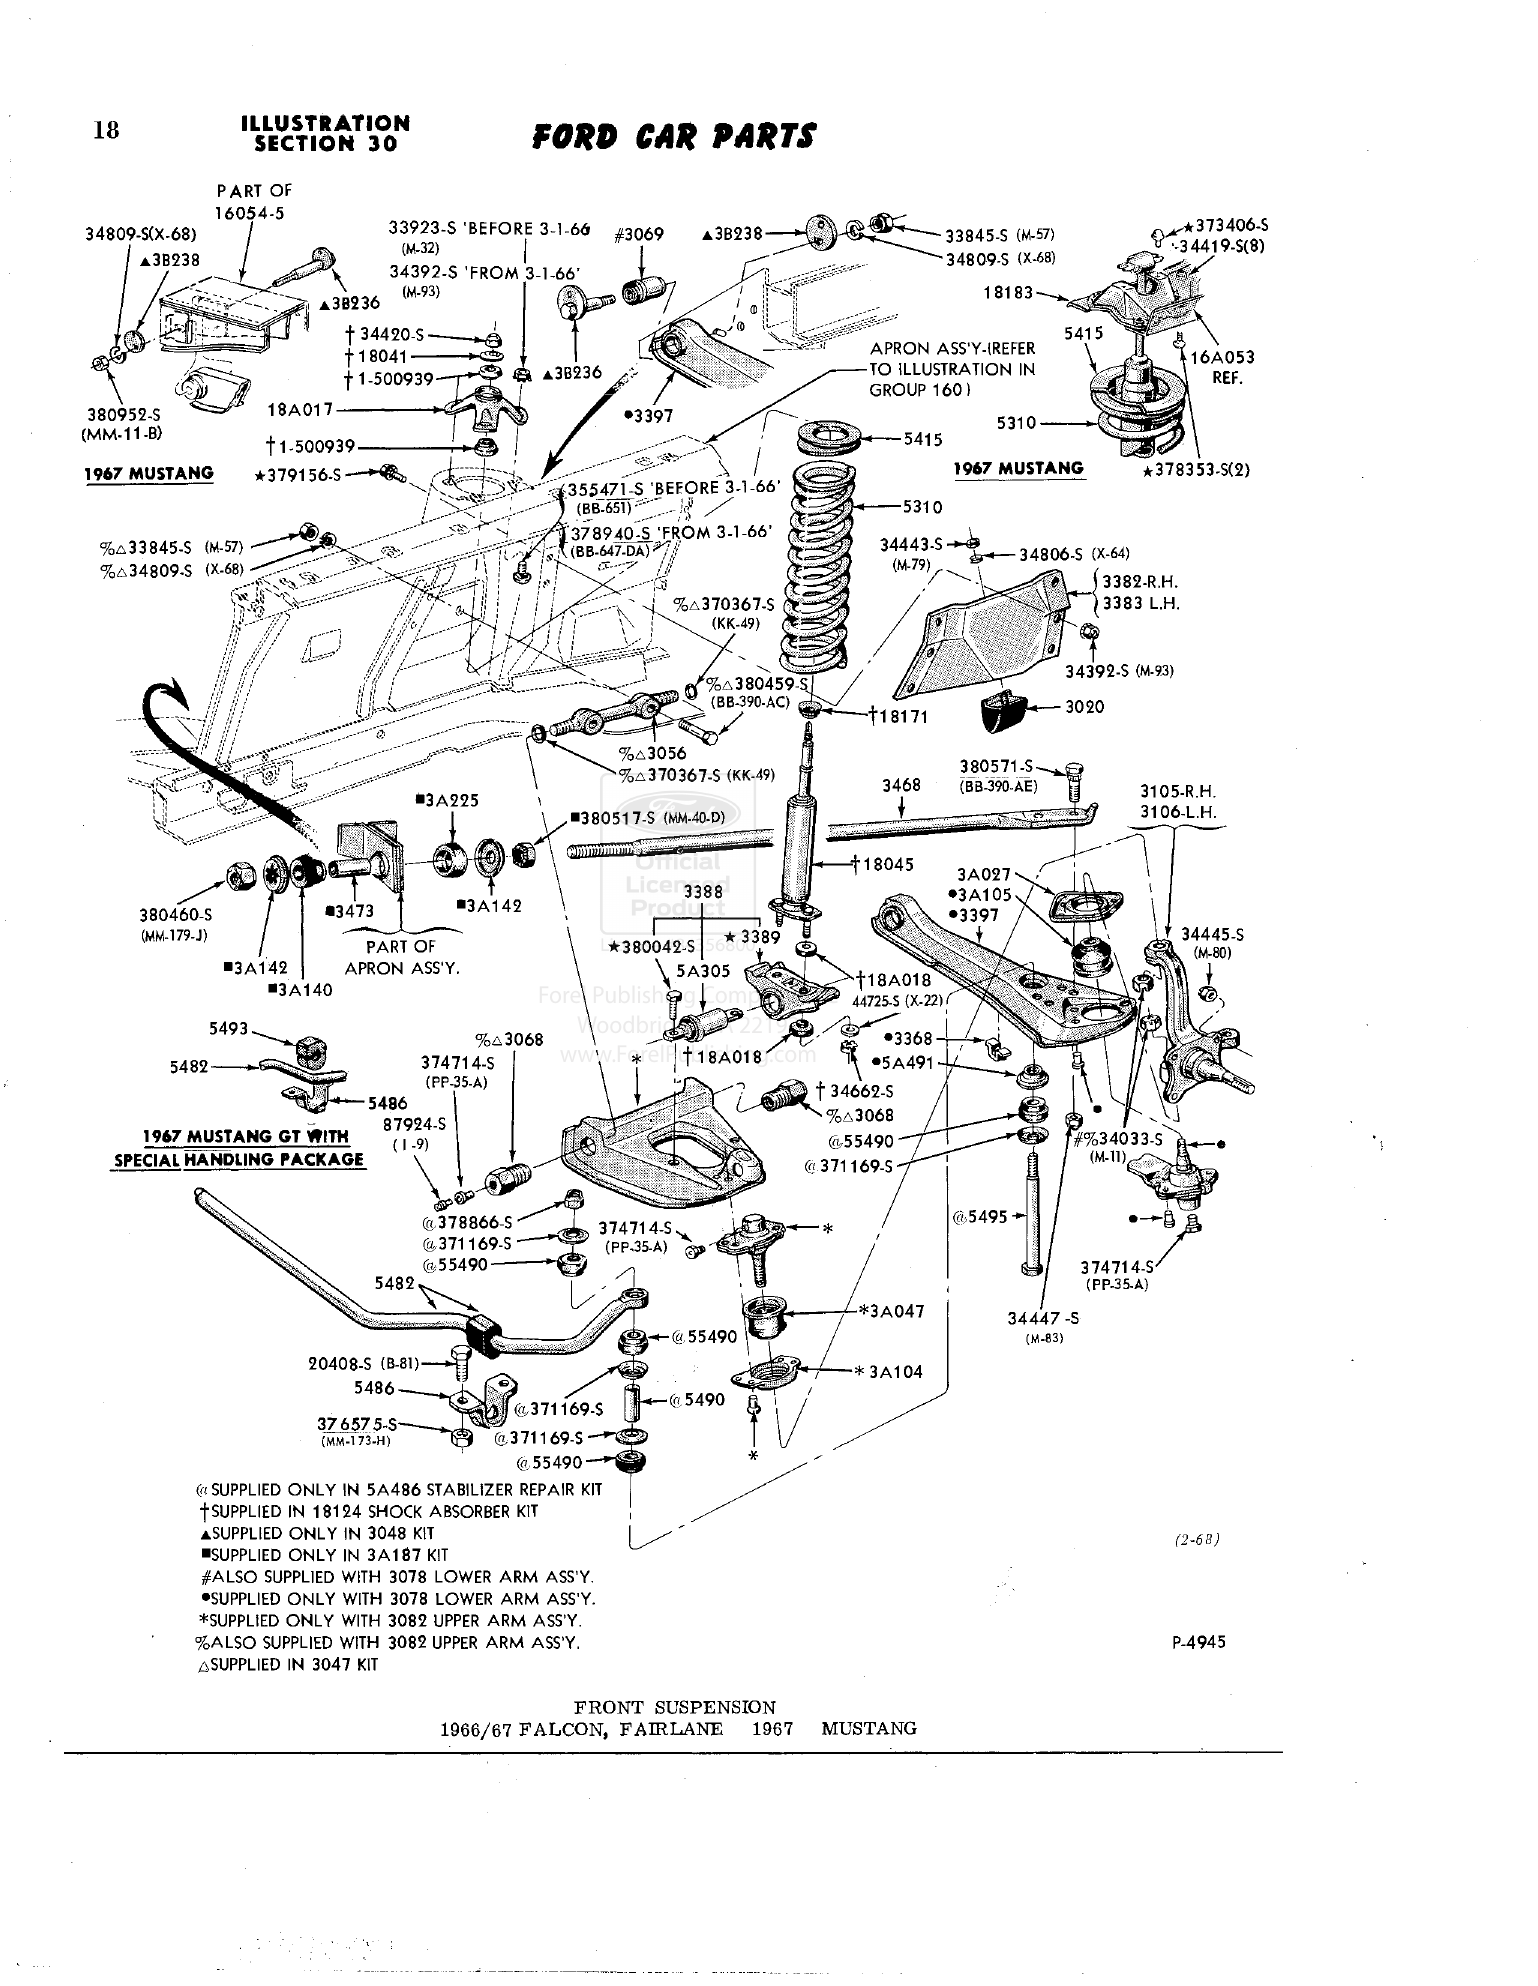
All the exercises use diagrams from the Ford 1960–68 Car Master Parts and Accessories Catalog, a 5,445-page reference Ford dealerships used to look up parts before computerized parts systems. I wrote the questions and answers myself.
To run the benchmark yourself, you’ll need your own PDF copy of the catalog. You can purchase it from Forel (product D10063).
What the model sees
A question, the relevant page images, and instructions on how to use the catalog. Images are rendered at 300 DPI, with any crops or highlights specified for that question. The PDF’s OCR text isn’t sent. None of the current questions requires looking something up in the text catalog.
Scoring
Every question has the same weight, regardless of difficulty. Part numbers, lists, and other structured answers are checked against the answer key. Free-text answers are graded against a rubric and can earn partial credit. Partial credit for incomplete lists is reported separately from the main score.
Run settings
These models were accessed through OpenRouter.
Loading run settings…
Each score uses one answer per question. Some answers are reused from earlier runs when the question, image, and settings match. The assembly date is when those results were combined, not necessarily when every answer was generated.
Error bars
Several questions share each diagram, so the confidence intervals resample whole exercises rather than treating every question as independent. With only ten exercises, the intervals are still wide. They don’t capture how answers might change on a second run, or errors made by the grader.
Failed answers
A model gets zero if it runs out of output tokens or returns no final answer. Service errors can be retried. Models with unfinished runs or unresolved grading errors aren’t listed yet. A service failure doesn’t tell us how the model would have answered.
Cost and time
Cost is what the provider reported for the saved answers, including reused ones. Grading costs are listed separately. Paid retries that weren’t recorded may be missing, so these figures won’t necessarily match the bill. Response times also depend on provider load and how much reasoning the model does.