Checkable by design
Every fact carries its reasoning, its evidence and its provenance — observed, stated by a person, or inferred. A claim you can check without asking anybody.
Reasoning, evidence and provenance on every fact
Knowl Cloud
Because it gets trusted. Knowl gives every fact your agents store a record of where it came from, a review trail, and a successor when it changes — so the answer they hand back is the current one, and you can see who settled it.
How this was built — the approaches that failed first, and the measurements that ruled each one out.
~/your-repo
$ npm install -g @dat999zx/knowl
added 1 package
$ knowl --version
5.23.1
Node 20 or newer. No API key, no vector database, no service to run alongside it.
In March an agent works out your API rate limit. 100 a minute.
In June somebody raises it to 500. The note still says 100.
An agent reads the note. It builds against 100.
Nothing announces it. You find out when something breaks.
Every fact carries its reasoning, its evidence and its provenance — observed, stated by a person, or inferred. A claim you can check without asking anybody.
Reasoning, evidence and provenance on every fact
Knowl runs in your repository and keeps its knowledge there. Your code, your embeddings and your session history are never uploaded.
Local by default, shared on purpose
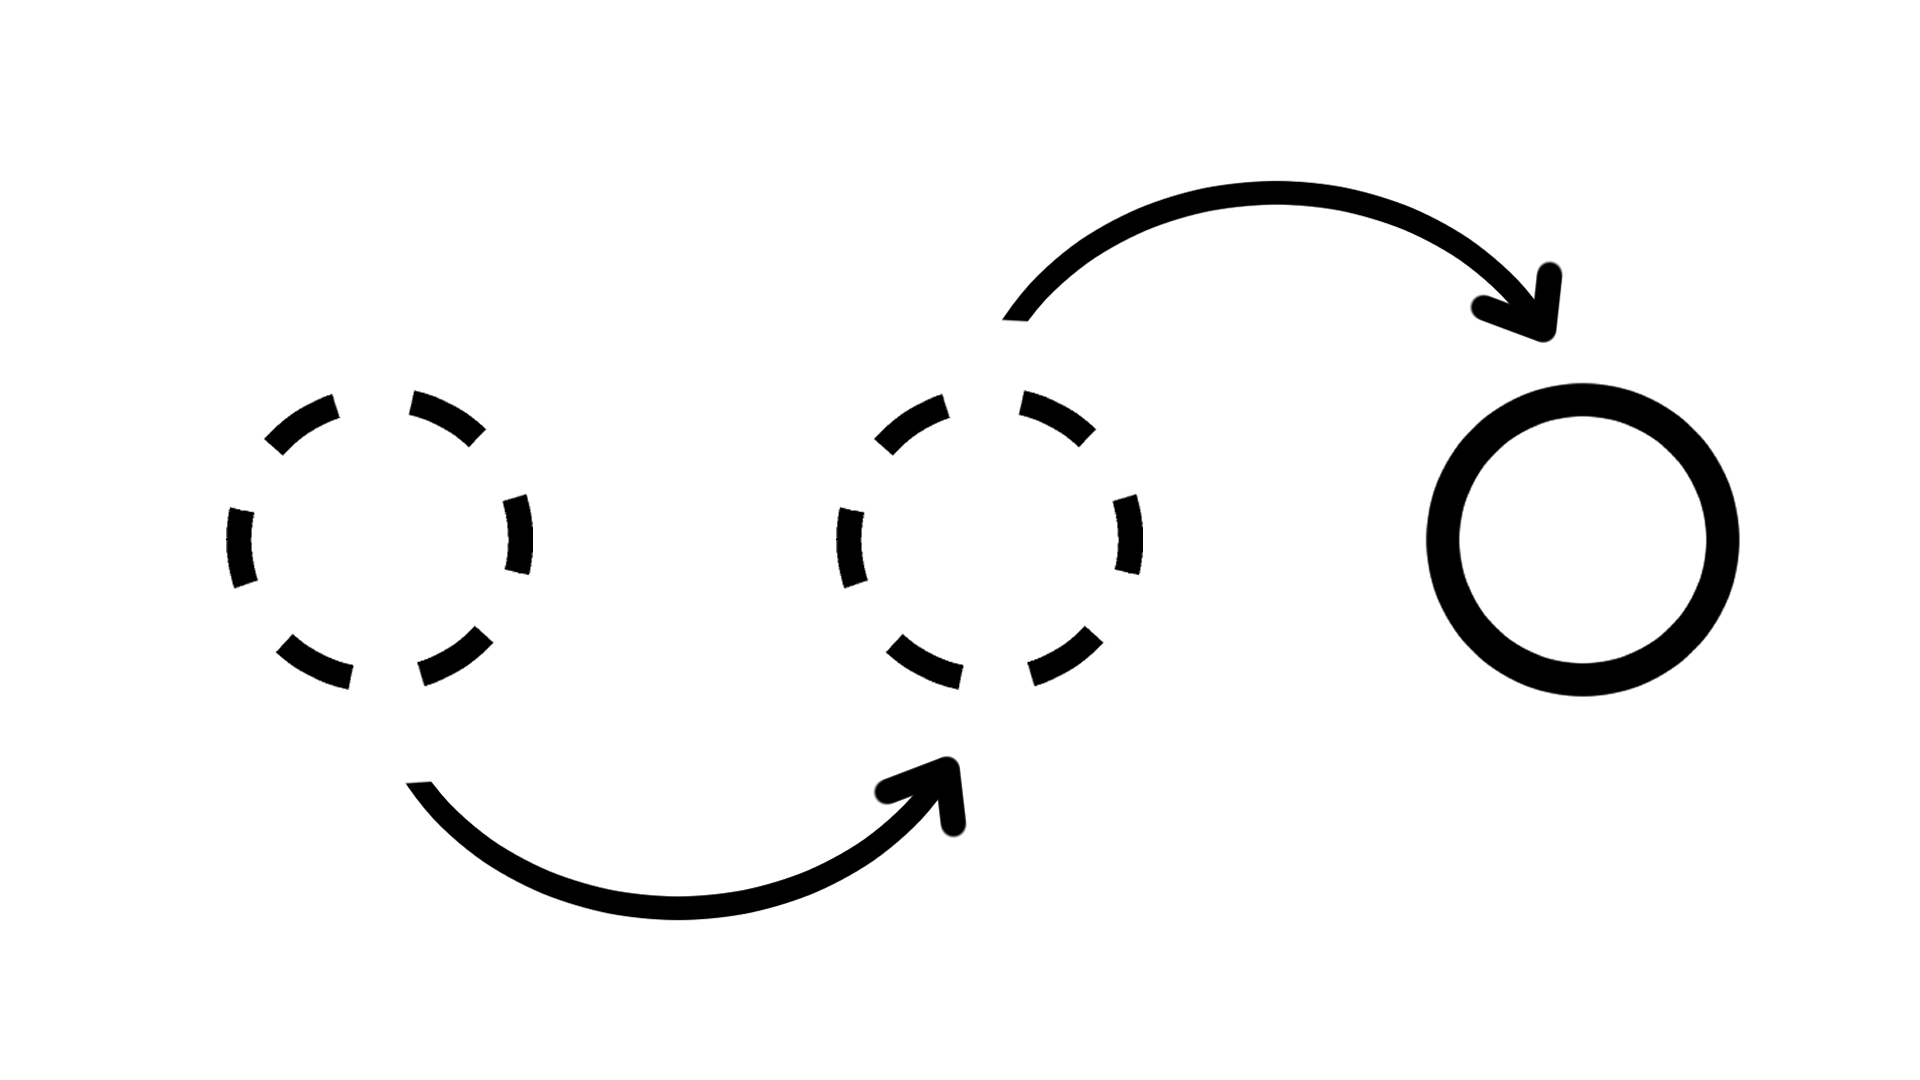
A fact records what it replaced and what replaced it. Superseded knowledge is never deleted — there is no delete verb in the product at all.
History is the feature, not a changelog
Adapters
Knowl runs as an MCP server, so anything that speaks MCP works with no adapter to write. Three of these also take lifecycle hooks, which is what lets an agent capture what it learned without being asked.
knowl init claudeMCP + hooksknowl init codexMCP + hooksknowl init cursorMCP + hooksknowl init copilotMCP + hooksknowl init openhandsMCP + hooksknowl init antigravityMCP + hooksknowl init windsurfMCP + gateknowl init clineMCP + pluginknowl acpMCP + ACPknowl acpMCP + ACPknowl acpMCP + ACPknowl acpMCP + ACPknowl init claude-desktopMCPknowl init opencodeMCPspeaks MCPbring your ownBefore / after
Most teams already have agent memory. It is a markdown file nobody trusts, and a person who remembers the rest.
CLAUDE.mdAPI rate limit: 100/min
The fact, and its successor500/min supersedes the March factThe old one stays readable. Nobody had to remember to edit anything.
Pasting context every sessionThe same explanation, every new chat
The agent already knowsAnd can show you where it learned it
Asking in Slack“does anyone remember why we…”
One workspace memoryDisagreements surface as disputes, not silence
A teammate who remembersUntil the day they don't, or they leave
A record that outlives themWith the alternatives it beat still attached
Freshness
A memory tool that only stores things goes stale silently. That rate limit, in full: what Knowl records over the four months it takes one claim to go from true to retired — every step kept, nothing overwritten, nothing deleted.
“What's our rate limit on the public API?”
100 requests a minutefactobservedapi-gateway
An agent worked this out mid-task and stored it, with the run that established it still attached.
Approved in the review queue
From here the claim carries a name, not just a timestamp — so “who decided this” still has an answer six months later.
“What's our rate limit on the public API?”
500 requests a minutesupersedes the March fact
It changed, and the answer changed with it. Nobody had to remember to go and edit anything.
The March answer is still there
Retired, not deleted. You can see that it changed, when, and what replaced it — which is the part a file full of notes can never tell you.
Proof
When a fact changes, most memory tools keep handing back the old one. On the public benchmark for exactly this, Knowl got 90 of 100 right.
90% Knowl
79% agentmemory
60% GPT-4olong-context
54%HippoRAG-v2
48%BM25
45%GPT-4o-minilong-context
29% Qwen3Embedding-4B
28% Cognee
28% MemGPT
18% Mem0
14%MIRIX
7% Zep
SubEM on MemoryAgentBench FactConsolidation-SH at 262K, scored with the benchmark’s own harness. Method, raw results, and the splits where we do worse: the full write-up.
In their words
Memory going stale is not our framing of the problem. It is written into the documentation of the agents your team already runs.
 Anthropic
“Over many sessions a memory store accumulates duplicates, contradictions, and stale entries.”
Managed Agents documentation — Dreams
OpenAI
“Memory can become stale. Agents are instructed to treat memories as guidance only.”
Agents SDK — agent memory
Greyhound Research
“The deepest flaw in current agent memory is that it mistakes retrieval for memory.”
Sanchit Vir Gogia, Chief Analyst — via InfoWorld
Quoted verbatim from published sources, read August 2026. These are observations about the problem, not endorsements of Knowl — every link goes to the page the sentence was read on.
Pricing
Queries never reach us — your agents read a replica on your own machine, so reading back is free at every tier and always will be.
Accounts are free and so is your first workspace. Anyone can be invited in and use all of it — you pay when your team outgrows what Free carries each period.