For eons, humans have made scientific discoveries, beautiful software, and explained the world to others. The vast majority of this work was left for strangers to learn from and carry forward. Using the knowledge and processes inherited from those before us, we have learnt to build intelligent machines that are now helping us make new discoveries at an ever increasing rate. When humans first learnt to leave Earth and explore space, the possibilities invited similar ambitions and similar apprehension.
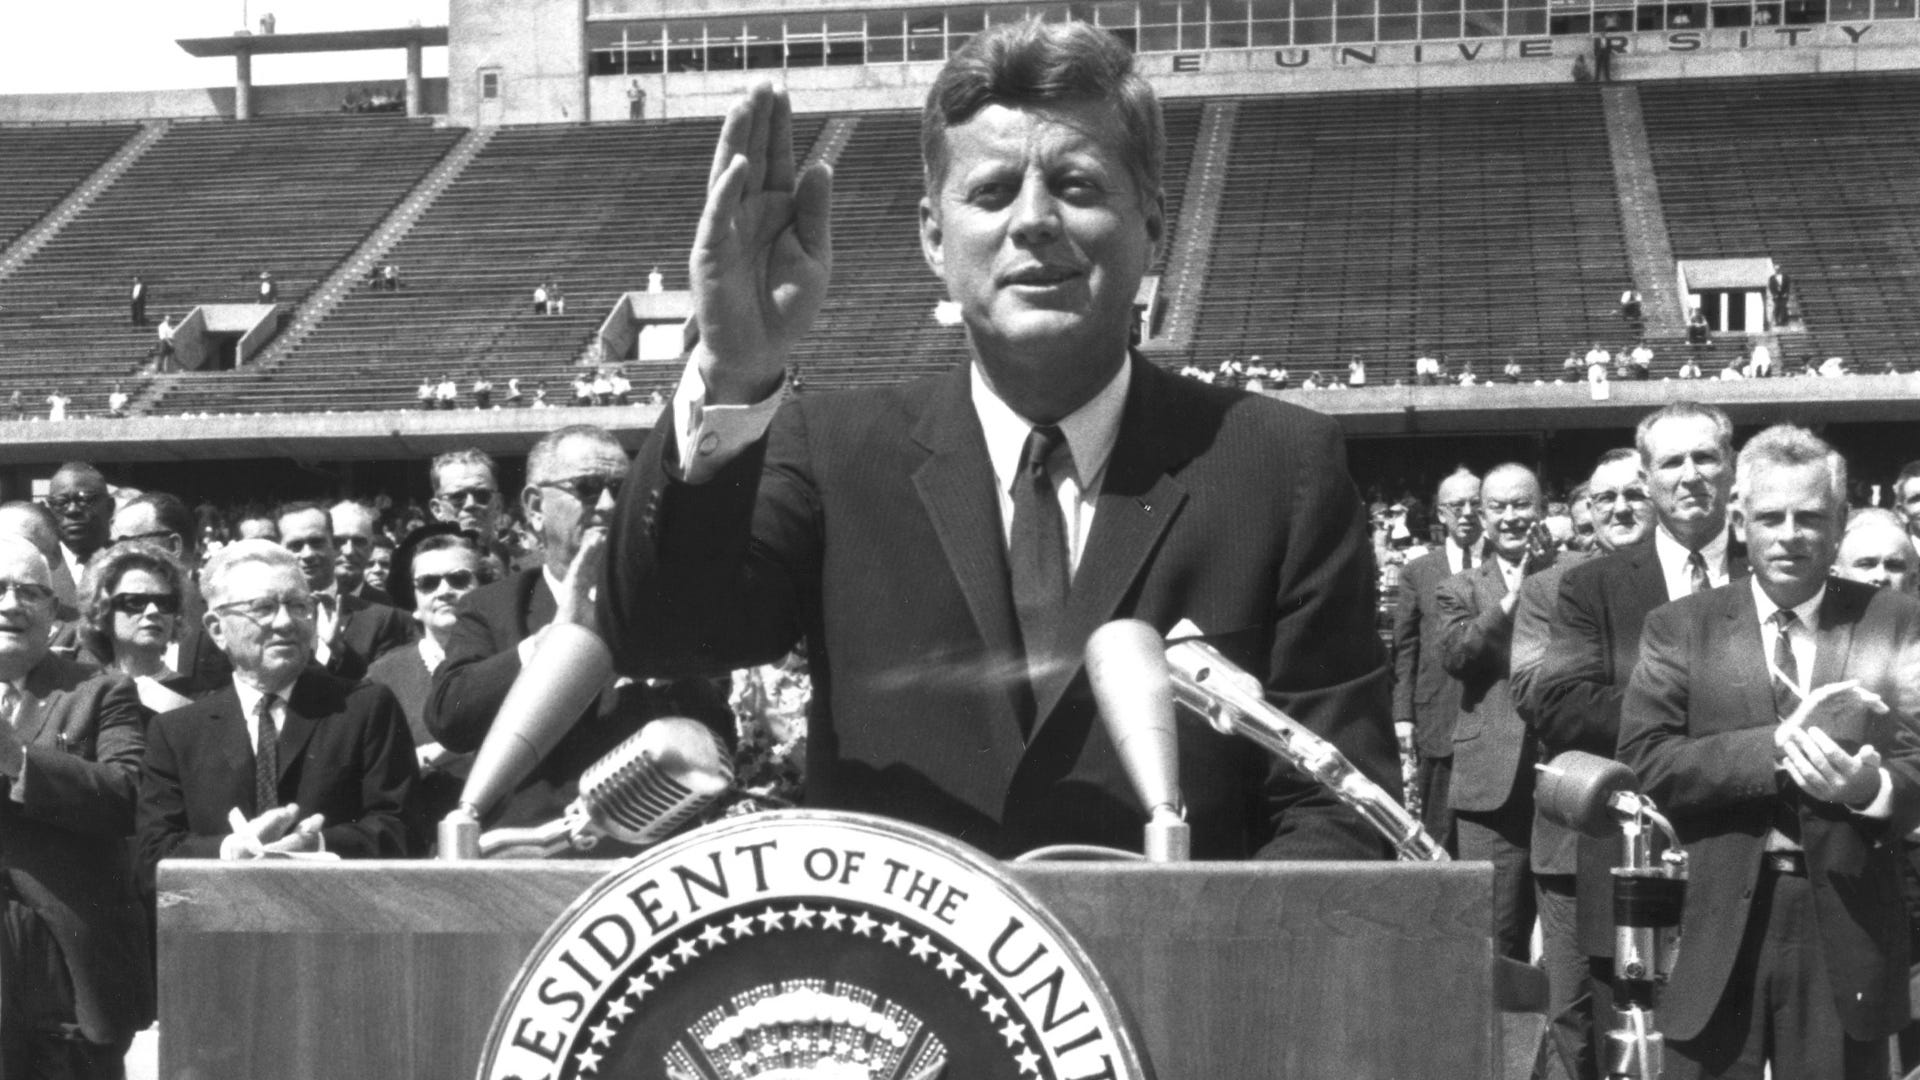
President John F. Kennedy addressed this in his “We choose to go to the Moon” speech in 1962.
This is a breathtaking pace, and such a pace cannot help but create new ills as it dispels old, new ignorance, new problems, new dangers. Surely the opening vistas of space promise high costs and hardships, as well as high reward.
So it is not surprising that some would have us stay where we are a little longer to rest, to wait. But this city of Houston, this State of Texas, this country of the United States was not built by those who waited and rested and wished to look behind them. This country was conquered by those who moved forward — and so will space.
Machine intelligence presents us with another moment where people have both ambitions and misgivings. There may definitely be well-founded reasons to proceed carefully. However, the possibility of harm cannot, on its own, settle whether an entire field should advance or who should be permitted to advance it. This is why I believe intelligence should be free. This is the only way continue expanding what we can discover while ensuring the means of discovery are within the reach of ordinary people
The accumulated knowledge of our civilization, acquired through the labor and ingenuity of generations, contributes to machine intelligence. Yet today, machine intelligence is offered back to us largely as a set of monetized proprietary services. The access to these services can be granted, priced, restricted, or withdrawn, at the whims of its owners. The means of producing our own machine intelligence, unfortunately, still remain largely beyond public reach. We should examine this arrangement before it becomes ordinary. The question to really ask is: who deserves to take part in discovery when its instruments are built from the work of millions but controlled by a few?
The free software movement established freedoms that should extend to machine intelligence. Free software gives people the freedom to run, study, modify, and share the software on which they depend. These freedoms allow someone who receives a tool to become someone who understands and improves it. Free software also allows useful work to continue after its original developer changes course or disappears. The corresponding goal for machine learning can be termed free intelligence. For machine learning models, these freedoms require access to the materials and methods needed to reproduce the entire process that produces a given model.
There are many open-weight models available today. Releasing weights is certainly an important contribution. It allows people to run a model locally, investigate its behavior, and adapt it, subject to the permissions accompanying the release. However, weights only record the outcome of training. Free intelligence requires the freedoms of free software to be extended to every part of the stack that is necessary to produce an equivalent machine learning model.
We define a model to be free when its released artifacts contain the following eight components, which can be used as a check-list.
Weights of the model accompanied by permission to run, modify, and redistribute the model.
All of the model’s pre-training and post-training data including the data’s sources of origin along with permission to use, share, and modify the data.
Code used to label, tokenize, sanitize, or otherwise process the model’s training data distributed under an open-source license
Code for the model’s architecture, pre-training and post-training algorithms including optimizer settings and configurations. All distributed under an open-source license.
The model’s rewards, reinforcement learning environments, feedback data, and any procedures used to generate synthetic data or select training examples.
Code for doing inference on the model under an open-source license.
Code for evaluating the model along with any evaluation materials necessary to test the model’s reported performance.
The model’s documentation and any other helpful information required for an independent group to reconstruct the entire process of developing, evaluating, and using the free model.
Note that the dependencies of all the distributed code also need to be open source, by transitivity. By an equivalent model, we mean a model that is obtained through the documented process with comparable behavior and performance. An equivalent model need not have numerically identical weights. We recognize that differences in hardware and nondeterministic computation can affect the result. The free model’s release should document these limitations and explain how reproduction can properly be evaluated.
Note that this is familiar ground for science. Examination, replication, and correction are central to establishing scientific claims as part of a shared body of knowledge. The science of building machine intelligence should be held to the same ambitions, especially when the systems it produces are offered as instruments for further discovery.
A model can be free, as described above, but still cost more to reproduce than most people will earn in a lifetime. The free model’s publication allows for scrutiny; however, participation remains confined to those who can afford the experiment. The freedom to build machine intelligence therefore has material conditions. It requires computing resources, time, energy, and tools that people can learn to use.
Given these socioeconomic constraints, a serious and equitable movement for free intelligence should make portability and efficiency central to its research agenda. At a minimum, there should be a broad effort to create smaller, useful free models that can be run, trained, and post-trained on ordinary and affordable consumer hardware. This is a demanding but bounded goal. It does not imply that a home computer should reproduce the largest training run. However, it does require the availability of a complete and viable path through the process of free model creation, at an accessible scale, that is capable of producing something useful.
Research that reduces the costs of free model creation needs to be viewed more from this perspective. For example, developing a more efficient method for model training can put an experiment within reach of thousands of additional researchers. Similarly, a portable implementation of a model can free a project from dependence on one hardware supplier. These are substantial achievements.
Larger experiments will still need shared infrastructure, of course. Public computing facilities, university consortia, and cooperatively managed resources can provide access beyond a given individual’s means. The availability of free intelligence allows these efforts to pursue goals independently of a model provider’s commercial priorities. They can make room for independent work, including questions without an obvious commercial return. If there is one lesson the history of science has taught us, it is that we cannot predict who will have the next useful idea.
One of the most exciting potential outcome of free intelligence is the emergence of community models. We define community models as useful and reproducible free models that are developed and maintained by communities of everyday people primarily using knowledge that community members choose to contribute. For example, a community may form around a scientific field or a profession. Note that community models need not excel at everything or push the limits of the frontier. We envision the goal of community models to be to serve purposes the community understands and has the means to evaluate.
Consider a language such as Irish Gaeilge which is poorly represented in existing systems. Speakers of Gaeilge could assemble a freely shareable collection of writing including contributed examples of everyday usage. They could develop tests that distinguish fluent expression from plausible nonsense. Teachers of Irish Gailge could help spearhead the training of a community model for learners. Everyday speakers of Gailge could correct the community model’s mistakes and decide which gaps deserve attention. The language would not have to acquire a large commercial market or have a carefully planned path to monetization before this greatly beneficial work begins.
Similar efforts could also grow around other kinds of knowledge. A community of independent car mechanics or bicycle enthusiasts may develop a model to help interpret openly licensed repair manuals and test the model’s suggestions against documented procedures. A community of educators for a school district could contribute lessons and explanations of their curriculum and then examine where a small teaching model helps students as opposed to where the model misleads them. Researchers working on a narrow but complex problem such as a cure to a rare illness could share the complete record of their experiments allowing another group to gain insights from the community model, pursue a different approach, and extend the community model either through retraining, inference-time context, or harness engineering with their results.
The crucial point here is the relationship community models create between machine intelligence and people. Community models allow the community to have the means to examine the model’s foundations, correct the model’s behavior, and use these insights to decide the future of the community model. The community can freely preserve a useful version of the model if an update caused a regression. If there are broad disagreements, different members of the community have the freedom to build alternatives from the same shared foundation model. The community therefore has a direct role in deciding what behavior its model should be trained to exhibit and how the model’s behavior should be evaluated. This would not, by itself, solve the technical problem of model alignment or remove obligations to people affected outside the community. However, it gives communities a meaningful voice in those questions.
Community stewardship of machine intelligence will certainly require care. Contributors of community models must carry a responsibility. They should understand what they are agreeing to share, particularly when a released dataset cannot reliably be recalled. Private knowledge need not become public simply because it would be useful for training, this is a decision taken through the informed consent of each community volunteer contributing that knowledge. Maintenance of community models would need resources and community maintainers may require financial and other forms of support. Participation should not depend on being able to afford unpaid work. Here, democratic forms of community leadership, clear decision-making, and the freedom to reproduce the work would help a community remain accountable to its members.
Our vision of free intelligence requires a shared effort. It will only be possible through consistent contributions and advocacy from a large number of scientists, engineers, researchers, activists, community leaders, and everyday people. However, these contributions will help determine whether the benefits of machine intelligence and its use as an increasingly powerful instrument of scientific inquiry becomes a common resource, or whether the power of machine intelligence is indefinitely wielded by a small circle of wealthy institutions.
One of the great achievements of science is that a discovery can become the starting point of someone who never met its discoverer. Machine intelligence has emerged from that long exchange. It is our responsibility to ensure that machine intelligence also extends this exchange. The people who come after us will have questions we cannot imagine. It is our duty to provide them with the freedom and the means to pursue those questions.