Kitten-TTS

New: Free Kitten-TTS 2 API available at https://platform.kittenml.com
Kitten-TTS is a series of sota open-source text-to-speech models, built by KittenML. Its flagship model, Kitten-TTS 2, is a 1.7B-parameter 1-bit TTS model with in-context voice cloning and expression control. It provides SOTA quality while being so efficient that it runs realtime on CPUs and consumer GPU's!
The library also ships our existing lightweight V0.8 models,
15M-80M parameters, which run on CPU without a GPU. Both families load through the same
KittenTTS(...) constructor.
Commercial support is available. For integration assistance, custom voices, or enterprise licensing, contact us.
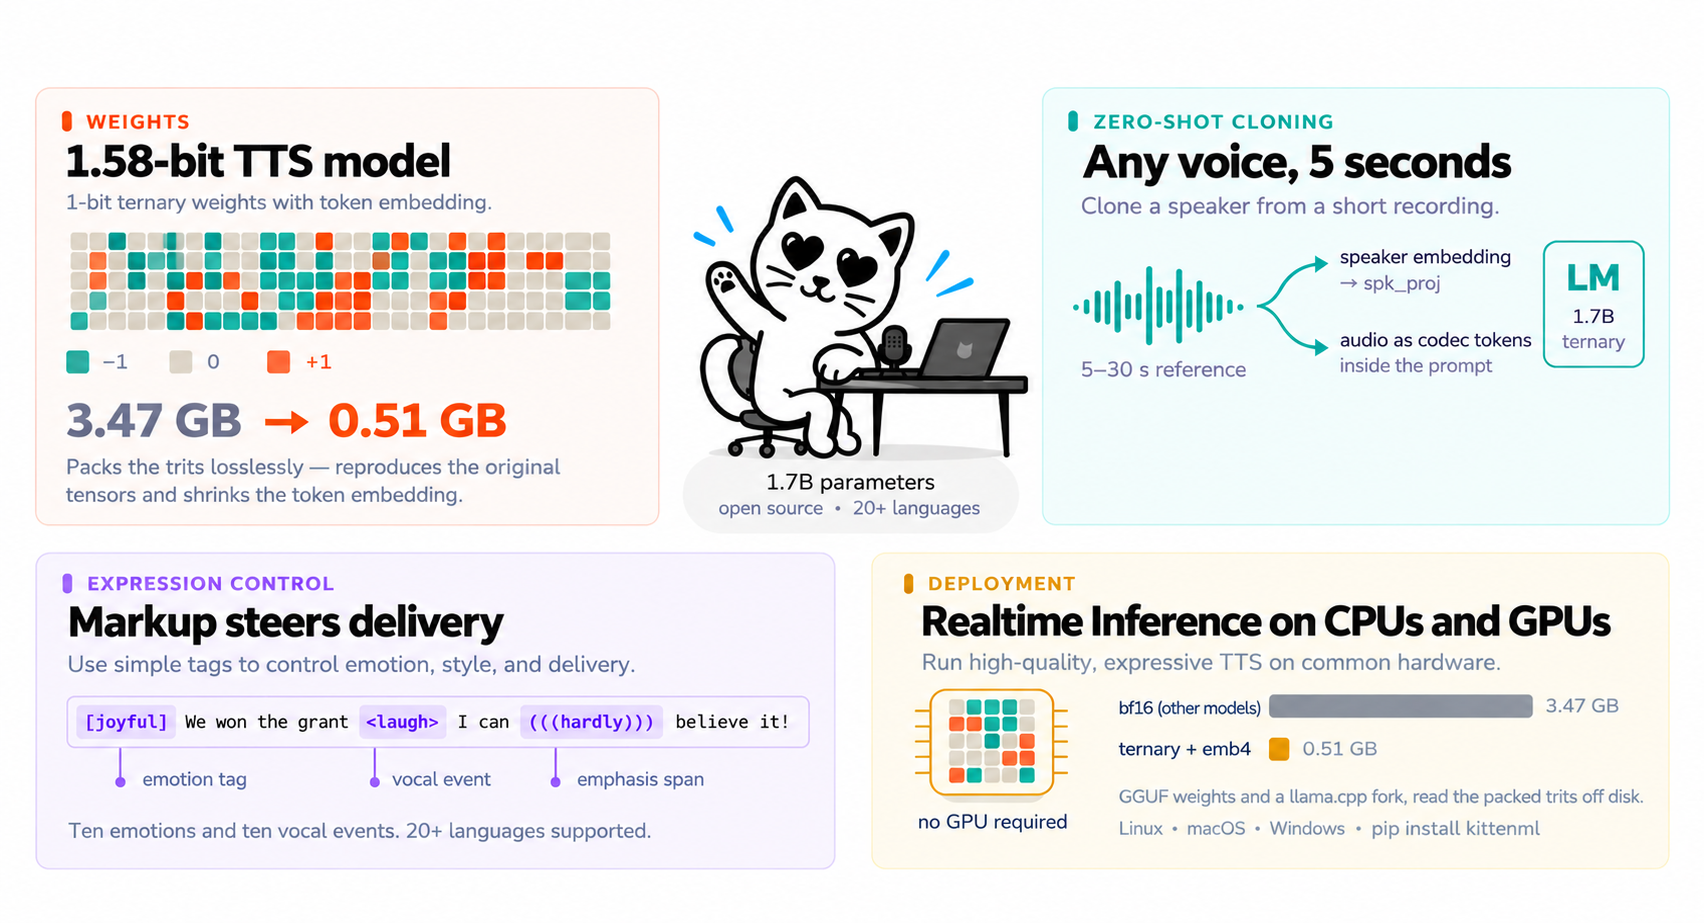
Table of Contents
- Features
- Available Models
- Demo
- Quick Start
- Voice cloning
- Expression controls
- Running on CPU
- Running on a Mac
- Running with vLLM
- Long text and streaming
- Documentation
- System Requirements
- Commercial Support
- Community and Support
- License
Features
- Voice cloning -- Clone any speaker from 5-30 seconds of audio, no fine-tuning
- 47 built-in voices -- Including the eight from KittenTTS 0.8 and nine non-English
- Multilingual -- 20 languages: English, Arabic, Chinese, French, German, Hindi, Italian, Portuguese, Russian, Spanish, Japanese, Korean, Turkish, Dutch, Swedish, Danish, Finnish, Swahili, Greek, Hebrew
- Expression control --
[emotion]tags, inline<event>tags, and(((emphasis)))spans - Decoding presets -- Trade stability against expressiveness per request
- Long-form text -- Sentence-aware chunking with seamless joins
- Text preprocessing -- Numbers, currencies, dates, units and abbreviations expanded automatically
- 24 kHz output -- High-quality audio at a standard sample rate
- Runs without a GPU
- Runs real time on a CPU -- Check Running on CPU
- Optimized C++ inference for CPU -- Our fork of llama.cpp
- Several times realtime on Apple silicon -- Check Running on a Mac
Available Models
KittenTTS 2 -- speech language model:
| Model | Parameters | Size | Voices | Download |
|---|---|---|---|---|
| kitten-tts-2 | 1.7B | 506 MiB | 47 + cloning | KittenML/kitten-tts-2 |
Lightweight ONNX -- runs on CPU, no GPU required:
| Model | Parameters | Size | Download |
|---|---|---|---|
| kitten-tts-mini | 80M | 80 MB | KittenML/kitten-tts-mini-0.8 |
| kitten-tts-micro | 40M | 41 MB | KittenML/kitten-tts-micro-0.8 |
| kitten-tts-nano | 15M | 56 MB | KittenML/kitten-tts-nano-0.8 |
| kitten-tts-nano (int8) | 15M | 25 MB | KittenML/kitten-tts-nano-0.8-int8 |
Demo
kittentts2_vid_10mb_2.mp4
Try it online
Try Kitten TTS directly in your browser on KittenML Platform.
Or run the Gradio demo locally: pip install kittenml gradio, then python gradio_demo.py.
Quick Start
Prerequisites
- Python 3.9 or later
- A CUDA GPU with roughly 8 GB free, or a CPU with about 6 GB of RAM
- About 1 GB of disk space for the model, or 506 MiB with the smaller weights
Installation
That is the whole install. KittenTTS 2 is the default model, voice cloning is included, and no Hugging Face login is needed -- every weight the model uses ships in its own repository. It also pulls the small ONNX runtime, so the lightweight models work from the same install.
Basic usage
from kittenml import KittenTTS
import soundfile as sf

m = KittenTTS("KittenML/kitten-tts-2")

audio = m.generate("Hi! umm.. how are you, I guess?  .. uh.. nice to meet you??",
                   voice="WeatherPresenterCheerful")
sf.write("output.wav", audio, m.sample_rate)
To run Kitten-TTS 2 on a CPU, please refer to Running on CPU
m.available_voices lists all 47 built-in voices, described in
voices and expression. Bella, Jasper, Luna, Bruno, Rosie, Hugo,
Kiki and Leo are the same speakers as in KittenTTS 0.8, so code written against the ONNX models
keeps working.
The weights come in two sizes. The default is 947 MiB and lossless; weights="emb4" is 506 MiB
because it quantises the token embedding, which costs a little quality. Only the one you ask for
is downloaded.
m = KittenTTS("KittenML/kitten-tts-2", weights="emb4") # half the download
# Trade stability against expressiveness
audio = m.generate("Hello, world.", voice="Matthew", preset="expressive")

# Save directly to a file
m.generate_to_file("Hello, world.", "output.wav", voice="Bruno")
Voice cloning
Pass reference= instead of voice= — same method, the recording just replaces the built-in
speaker. Give it 5-30 seconds of a single speaker. The transcript is part of the prompt, but you
do not have to type it; Whisper fills it in when omitted.
audio = m.generate("This is my own voice, cloned.", reference="my_voice.wav")

# Supplying the transcript skips the Whisper pass
audio = m.generate("This is my own voice.", reference="my_voice.wav",
                   reference_text="what is actually said in the clip")
The reference feeds the model by two independent routes -- a speaker embedding through the model's projection head, and the clip itself as codec tokens in the prompt -- so identity survives even when one route is weak.
Measured on the built-in voices: a generated clip scores 0.49-0.72 speaker similarity against its own reference and 0.01-0.18 against the other 37, and cloning an unseen recording scores 0.81 against that recording.
Expression controls
Beta. Emotion control steers delivery rather than guaranteeing it, and the effect varies by voice and by sentence.
audio = m.generate(
    "[joyful] We actually won the grant <laugh> I can (((hardly))) believe it!",
    voice="Kiki",
    preset="expressive",
)
A leading [emotion] tag, inline <event> tags and (((emphasis))) spans reach the model as
markup rather than being spoken, and automatically enable its expression conditioning. Ten
emotions and ten vocal events are recognised -- see
voices and expression for the full lists and what is not
covered.
Running on CPU
Kitten-TTS 2 runs on CPU out of the box — device is auto-detected — but the fastest way is
kitten-tts-2-cpp, our llama.cpp fork. It reads
the GGUF weights in the model repository's cpp/ directory. You can use the Python bindings too:
pip install kitten_tts_cpp
from kitten_tts_cpp import KittenTTS

model = KittenTTS("KittenML/kitten-tts-2", decoder="student_w4", threads=8)
model.generate_to_file("One day, a little girl named Lily found a needle in her room.", "hello.wav", voice="Bruno")
print(model.last_report)  # Generation timings and token IDs.
Kitten-TTS 2 C++ is in beta. Please report any issues you encounter.
Running on a Mac
On an Apple-silicon Mac, install the optional MLX backend and select it:
pip install "kittenml[mlx]"from kittenml import KittenTTS m = KittenTTS("KittenML/kitten-tts-2", backend="mlx") m.generate_to_file("One day, a little girl named Lily found a needle in her room.", "hello.wav", voice="Bruno")
See the MLX guide for benchmarks and the full details.
Running with vLLM
For GPU inference with vLLM on Linux and an NVIDIA CUDA GPU with compute capability 8.0 or newer (Ampere or later, for bfloat16), install the optional backend. GPUs with compute capability 7.5 can use a float16 fallback that is supported but not the optimal path (vLLM guide).
pip install "kittenml[vllm]"Select backend="vllm":
from kittenml import KittenTTS

def main():
    m = KittenTTS("KittenML/kitten-tts-2", backend="vllm",
                  vllm_options={"quantization": "w4a16"})
    m.generate_to_file("Hello there.", "output.wav", voice="Bruno")
    print("Saved output.wav")

if __name__ == "__main__":
    main()
Keep the main guard when running a script: vLLM starts a worker process. The same
voices, decoders, weight choices and generation arguments apply. The example
uses 4-bit language-model weights ("quantization": "w4a16"): the same weights, exactly, in about
2 GB less GPU memory, and faster for single requests. Leave out vllm_options to run in bf16; see
4-bit weights. See the
vLLM guide for memory settings and benchmarks.
Long text and streaming
Long input is split on sentence boundaries and synthesized chunk by chunk, then joined with silence trimming and short edge fades so the seams are inaudible. This is automatic: the model is reliable on short inputs but truncates or drifts into repetition when asked for a whole script in one pass.
To start playing before the whole thing is ready, stream it:
for chunk in m.generate_stream(long_text, voice="Luna"):
    play(chunk)          # each chunk is a numpy array at m.sample_rate
It takes the same arguments as generate, so reference= streams a cloned voice too.
Streaming is chunk-level, not token-level: a chunk is generated and vocoded in full before it is yielded, so the first chunk still costs its own generation time. On an A100, a 936-character passage yielded its first 21 s of audio after 17 s and finished 54 s of audio in 42 s of wall clock -- so playback keeps ahead of generation, but there is a real initial delay.
Two consequences worth knowing:
- Short text does not stream. Input that fits in one chunk (under roughly 380 characters,
and short trailing pieces get merged into their neighbour) yields exactly one chunk, so
generate_streambehaves likegenerate. - Chunks are yielded raw.
generatepost-processes the seams -- trimming each segment's edge silence, adding short fades and one consistent pause -- which a streaming caller cannot do without waiting for the next chunk. Concatenating streamed chunks directly gives slightly rougher joins thangenerateon the same text.
Documentation
| API reference | Every argument to generate, streaming, and the advanced knobs |
| Voices and expression | The 47 voices, emotion and vocal-event tags, the ten languages |
| Decoders | How audio is decoded, and the smaller quantised decoders |
| Text normalization | How written text becomes spoken text |
| Architecture | What the model is, package layout, vendored components |
| Docker | Run a basic OpenAI-compatible speech API, with voice cloning, in a container |
| Lightweight ONNX models | The CPU models, 15M-80M parameters, and their API |
| MLX on Apple silicon | The optional Mac GPU backend, and why it is faster |
System Requirements
KittenTTS 2
- Operating system: Linux, Windows or Mac
- Python: 3.9 or later
A virtual environment (conda, venv, or similar) is recommended to avoid dependency conflicts.
Commercial Support
We offer commercial support for teams integrating Kitten TTS into their products. This includes integration assistance, custom voice development, and enterprise licensing.
Contact us or email info@stellonlabs.com to discuss your requirements.
Community and Support
- Discord: Join the community
- Website: kittenml.com
- Custom support: Request form
- Email: info@stellonlabs.com
- Issues: GitHub Issues
License
This project is licensed under the Apache License 2.0. That covers the code in this repository.
The models are licensed separately and their terms may differ. Each model repository carries its own licensing, so check the one you intend to use before relying on it — do not assume the code's license extends to the weights.
KittenTTS 2 is released under the Stellon Labs Community License