pqless_
Browse Parquet files a screenful at a time, like less. Opens huge and very wide files instantly.
Only reads what you see
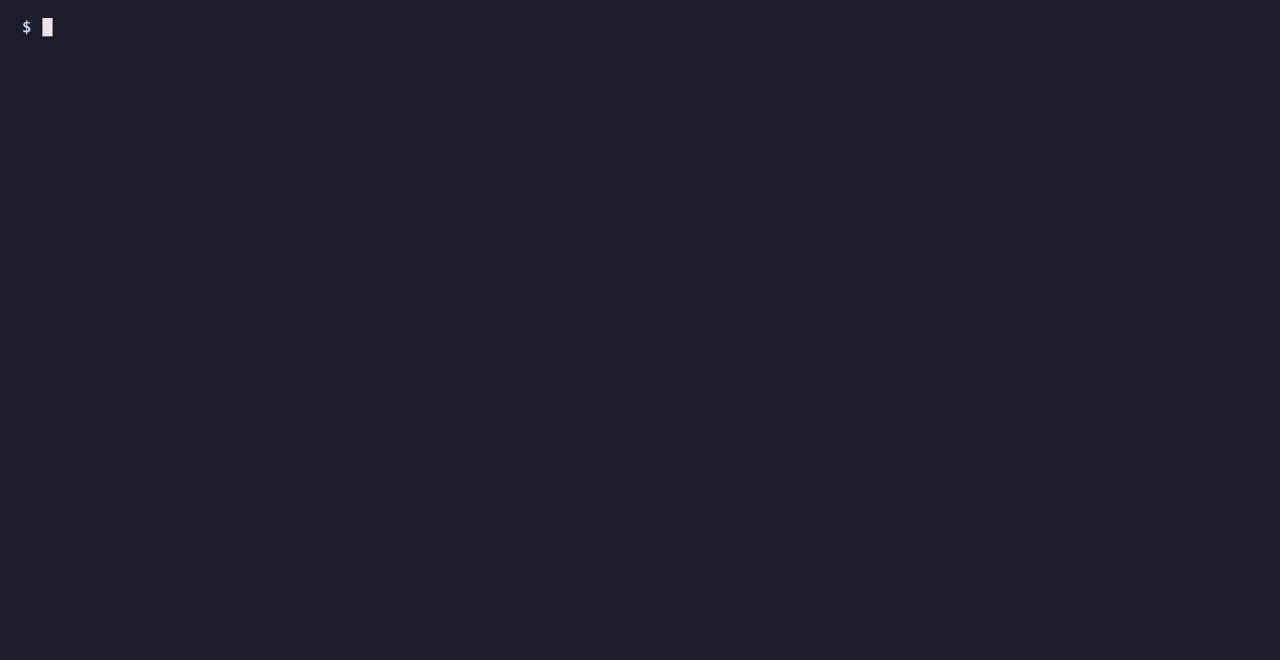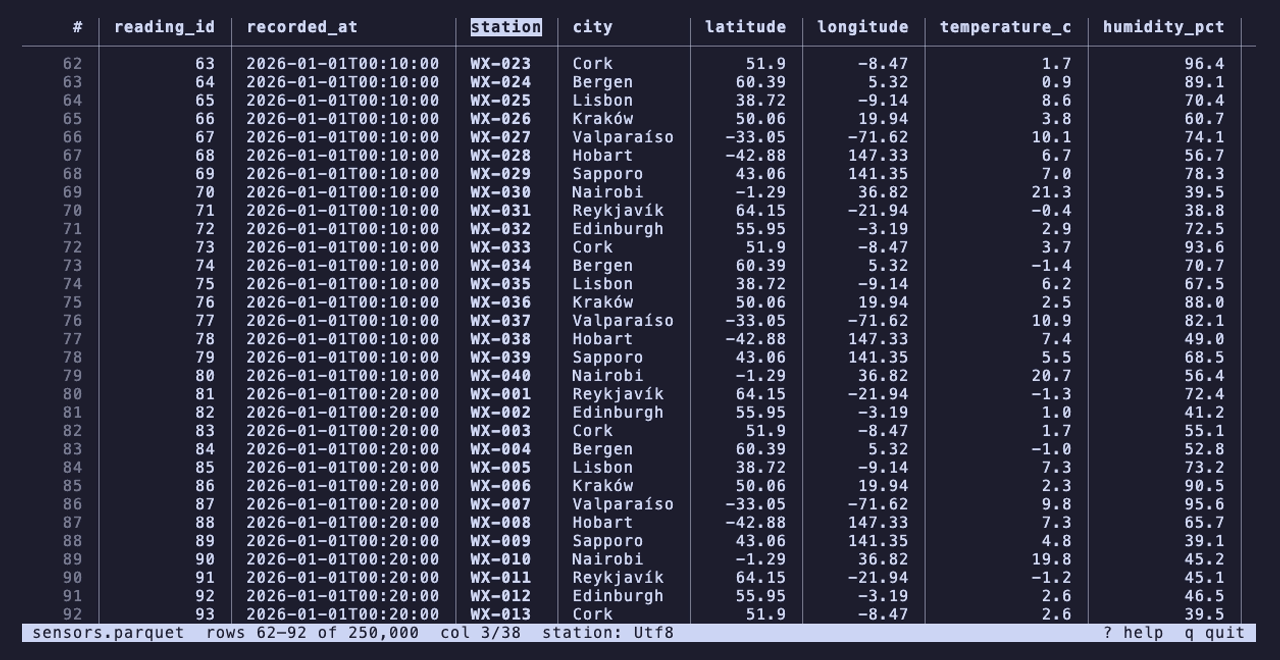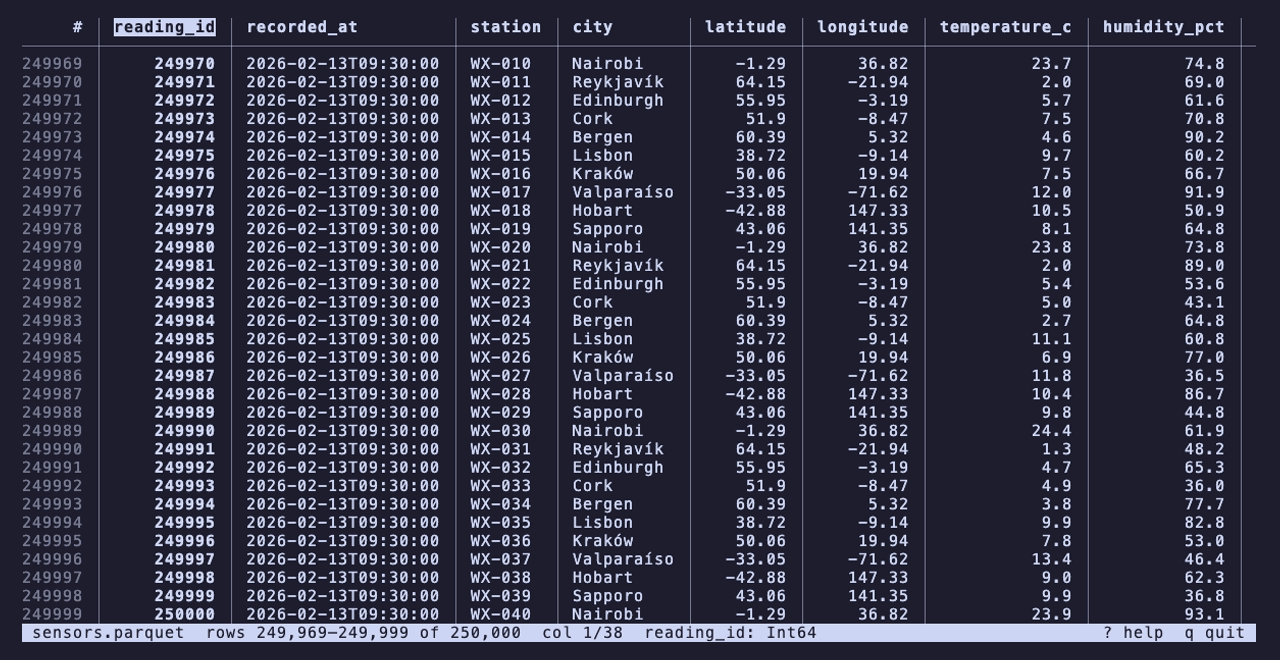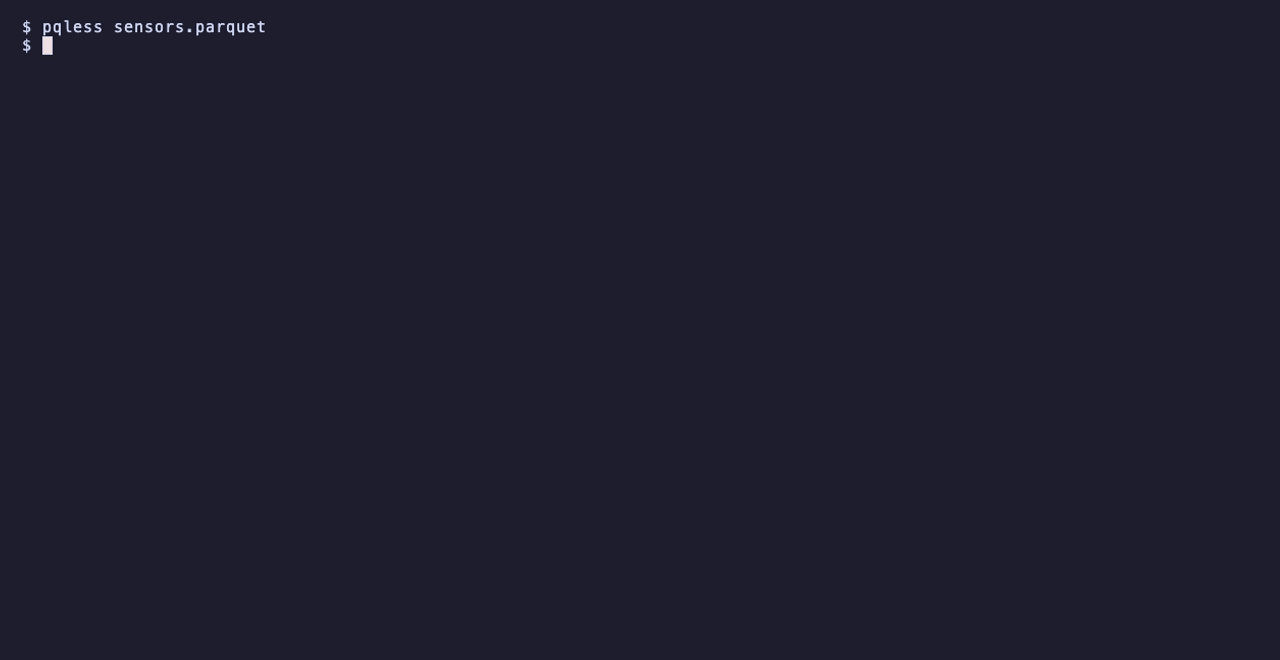
Parquet stores each column separately, so pqless decodes just the rows and columns on screen. The first page of a multi-gigabyte file with tens of thousands of columns appears in a fraction of a second.
Built for wide data
Move a column cursor sideways and new columns load as they scroll into view. The header stays pinned, and the status bar shows each column's full name and type.
Feels like less
Space, b, g, G, j/k and number prefixes work as you'd expect. Piped output prints a plain-text table, so | grep and | head work too.
How it compares
Time until the first screen of rows appears, and peak memory. Median of 3 runs on an Apple M2 Pro.
On everyday and tall files the fast tools are all effectively instant. Wide files are where reading only the visible columns pays off. VisiData and tabiew load the whole file up front so they can sort, filter and query it, which pqless doesn't do. Files, method and how to reproduce.
Install
Homebrew (macOS, Linux)
brew install danodonovan/tap/pqless
Install script (macOS, Linux; x86_64, arm64)
curl --proto '=https' --tlsv1.2 -LsSf https://github.com/danodonovan/pqless/releases/latest/download/pqless-installer.sh | sh
From source (Rust 1.88+)
cargo install --git https://github.com/danodonovan/pqless
Then run pqless data.parquet and press ? for keys.
Keys
| j ↓ Enter | down a row |
| k ↑ y | up a row |
| space f PgDn | down a page |
| b PgUp | up a page |
| d / u | down / up half a page |
| g Home | first row |
| G End | last row |
| N g | go to row N |
| l → / h ← | next / previous column |
| $ / 0 | last / first column |
| N + key | repeat a move N times |
| ? | show / hide help |
| q Esc | quit |