We know how AI works. We just don't have any readily accessible account in the surface-level terms that we would like.

There are so many things about computing that are interesting . . . which we miss while bogged down in AI muck. Among the many misnomers, misstatements, and anthropomorphized mischaracterizations, we find this: We don’t even know how generative AI works! This misleading wave toward the ineffable appears regularly in the popular press. For a recent occurrence, we read, in an article by Peter Denning: “[large language models] are ‘black boxes,’ meaning we have no idea what is going on inside. When we look inside, we cannot make sense of what we see—a huge neural network with millions of nodes and billions of weighted connections. The network gives no clue why it delivered an output, or how to correct it if an output is in error.”1 Okay, some of these statements come from venerable experts, and we know what they mean. But others don’t.
This literal claim of ignorance is absurd. We know exactly how it works. It’s a computer program. We just don’t have any readily accessible account in the surface-level terms that we would like. Machine learning just draws a line from input to output. That line does not pass through the set of holistic features, identifiable attributes, and causal relationships we want to use.
We know how payroll computation works: the program multiplies hours times pay rate. We could do that by hand! We know how address search works: the program compares the query to each database entry until it matches, then outputs the address field. But when we see a chatbot producing the word “delve” after the phrase “for greater understanding, we should,” we go all giddy. Yet we understand these things: Parsing into tokens and probability assignments in real numbers is followed by cycles of matrix multiplication, subtraction, sorting, and more arithmetic, involving incorporation of vast contexts that adjust the magnitude of elements’ effects. Based on the huge corpora sampled, the word ‘delve” follows the given string of tokens with high probability. We could do that by hand! (Given the span of a lifetime, only in theory, which is still significant.) In other words, the achievement in reasoning is quantitative, not qualitative.
When we go to a casino (not that we do), we see the croupier spin the roulette wheel one way and toss the ball the other way, where it goes around and around, until the deflectors slow it down enough so that it settles into a pocket. The only giddiness suffered by the players is based on their bets, winning or losing. No one says, “We just don’t know how it works!” as if that selection of a pocket were some sort of emergent miracle. And we could determine the outcome of the roulette spin to the level of deterministic explanation had we but world enough and time, extensive time, and all the relevant physical formulas at our fingertips. Even without that, we still “know how it works.” One might challenge the analogy thus: the roulette wheel does not provide an answer to a question, just a final outcome . . . but that’s exactly what a chatbot does.
Even plain old statistics produces results that may surprise us, but we don’t claim ignorance about how statistics works: The mean, median, and mode are the results of counting, sorting, adding, and dividing a whole lot of numbers. Didn’t we learn this way (without full biological explanation) that smoking causes cancer? We can validate and interpret a statistical result if necessary by following all the (possibly voluminous) calculations that demonstrate it. We understand that plain old statistics also draws a line from input to output without passing through interpretation.
An article in The New York Times Magazine explores worries about this opaque aspect of diagnostic and recommender systems, and describes new approaches to producing explanation and interpretation.2 That is an admirable endeavor, and, importantly, it is an endeavor predicated on knowing exactly how AI models work. Interpretability is a good goal, but it remains a distortion to call the lack of a gloss, in the terms we want, an impenetrable mystery.
The amazing thing is not that LLM application has escaped epistemic bounds, or achieved magic, or something like that, but that our collective discourse is so incredibly well modeled by token prediction based on context. What to make of that? Like the physics underlying the roulette wheel, the juicy part is not the observation, but the science of the phenomenon. We would be better served by investigating that, by seeking the theory that guides the generation of natural language, than marveling at the lack of casual, causal, intentional, interpretation that we want.
References
1. Denning, P.J. The Conundrum of LLMs. Communications 69:3 (2026), 31-34.
2. Whang, O. A Mind of Its Own. The New York Times Magazine (April 26, 2026).
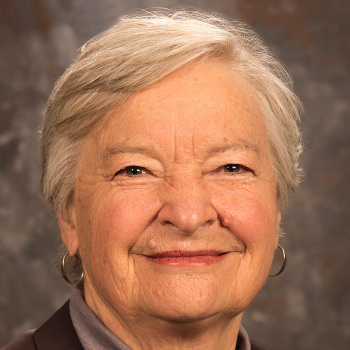
Robin K. Hill is a lecturer in the Department of Computer Science, an adjunct in the School of Computing, and an affiliate of the Department of Philosophy and Religious Studies, at the University of Wyoming. She has been a member of ACM since 1978.
Submit an Article to CACM
CACM welcomes unsolicited submissions on topics of relevance and value to the computing community.
You Just Read
We DO Know How, but Not the How We Want
© 2026 Copyright held by the owner/author(s).